Related Experiment Video
Updated: Mar 17, 2026

Analyzing Multifactorial RNA-Seq Experiments with DiCoExpress
Published on: July 29, 2022
Discovering Pair-wise Synergies in Microarray Data
Yuan Chen1,2, Dan Cao3, Jun Gao4,5
1Hunan Provincial Key Laboratory for Biology and Control of Plant Diseases and Insect Pests, Hunan Agricultural University, Changsha, Hunan, 410128, China.

Abstract:
Informative gene selection can have important implications for the improvement of cancer diagnosis and the identification of new drug targets. Individual-gene-ranking methods ignore interactions between genes. Furthermore, popular pair-wise gene evaluation methods, e.g. TSP and TSG, are helpless for discovering pair-wise interactions. Several efforts to discover pair-wise synergy have been made based on the information approach, such as EMBP and FeatKNN. However, the methods which are employed to estimate mutual information, e.g. binarization, histogram-based and KNN estimators, depend on known data or domain characteristics. Recently, Reshef et al. proposed a novel maximal information coefficient (MIC) measure to capture a wide range of associations between two variables that has the property of generality. An extension from MIC(X; Y) to MIC(X1; X2; Y) is therefore desired. We developed an approximation algorithm for estimating MIC(X1; X2; Y) where Y is a discrete variable. MIC(X1; X2; Y) is employed to detect pair-wise synergy in simulation and cancer microarray data. The results indicate that MIC(X1; X2; Y) also has the property of generality. It can discover synergic genes that are undetectable by reference feature selection methods such as MIC(X; Y) and TSG. Synergic genes can distinguish different phenotypes. Finally, the biological relevance of these synergic genes is validated with GO annotation and OUgene database.
Insights
This study introduces a new method, MIC(X1; X2; Y), to find synergistic gene pairs for improved cancer diagnosis and drug discovery. This approach uncovers gene interactions missed by existing methods, enhancing biological understanding.
Area of Science:
- Bioinformatics
- Computational Biology
- Genomics
Background:
- Accurate gene selection is crucial for cancer diagnosis and drug target identification.
- Existing methods often overlook complex gene interactions, limiting their effectiveness.
- Current information-theoretic approaches for gene synergy detection rely on assumptions about data characteristics.
Purpose of the Study:
- To develop and validate an extension of the Maximal Information Coefficient (MIC) to estimate MIC(X1; X2; Y) for detecting pair-wise gene synergy.
- To assess the generality and effectiveness of the proposed MIC(X1; X2; Y) measure in identifying synergistic genes.
- To demonstrate the utility of MIC(X1; X2; Y) in cancer diagnosis and drug discovery by analyzing simulation and microarray data.
Main Methods:
- Developed an approximation algorithm for estimating MIC(X1; X2; Y) for a discrete variable Y.
- Applied MIC(X1; X2; Y) to detect pair-wise synergy in simulated datasets and real cancer microarray data.
- Compared the performance of MIC(X1; X2; Y) against established feature selection methods like MIC(X; Y) and TSG.
Main Results:
- The proposed MIC(X1; X2; Y) measure exhibits generality in capturing a wide range of associations.
- MIC(X1; X2; Y) successfully identified synergistic genes that were undetectable by reference methods.
- Identified synergistic genes demonstrated the ability to distinguish between different phenotypes.
- The biological relevance of discovered synergistic genes was confirmed through Gene Ontology (GO) annotation and the OUgene database.
Conclusions:
- MIC(X1; X2; Y) provides a powerful and generalizable approach for discovering synergistic gene pairs.
- This method enhances the identification of informative genes for cancer diagnosis and potential drug targets.
- The findings highlight the importance of considering higher-order gene interactions for biological discovery.
Related Concept Videos
 02:34
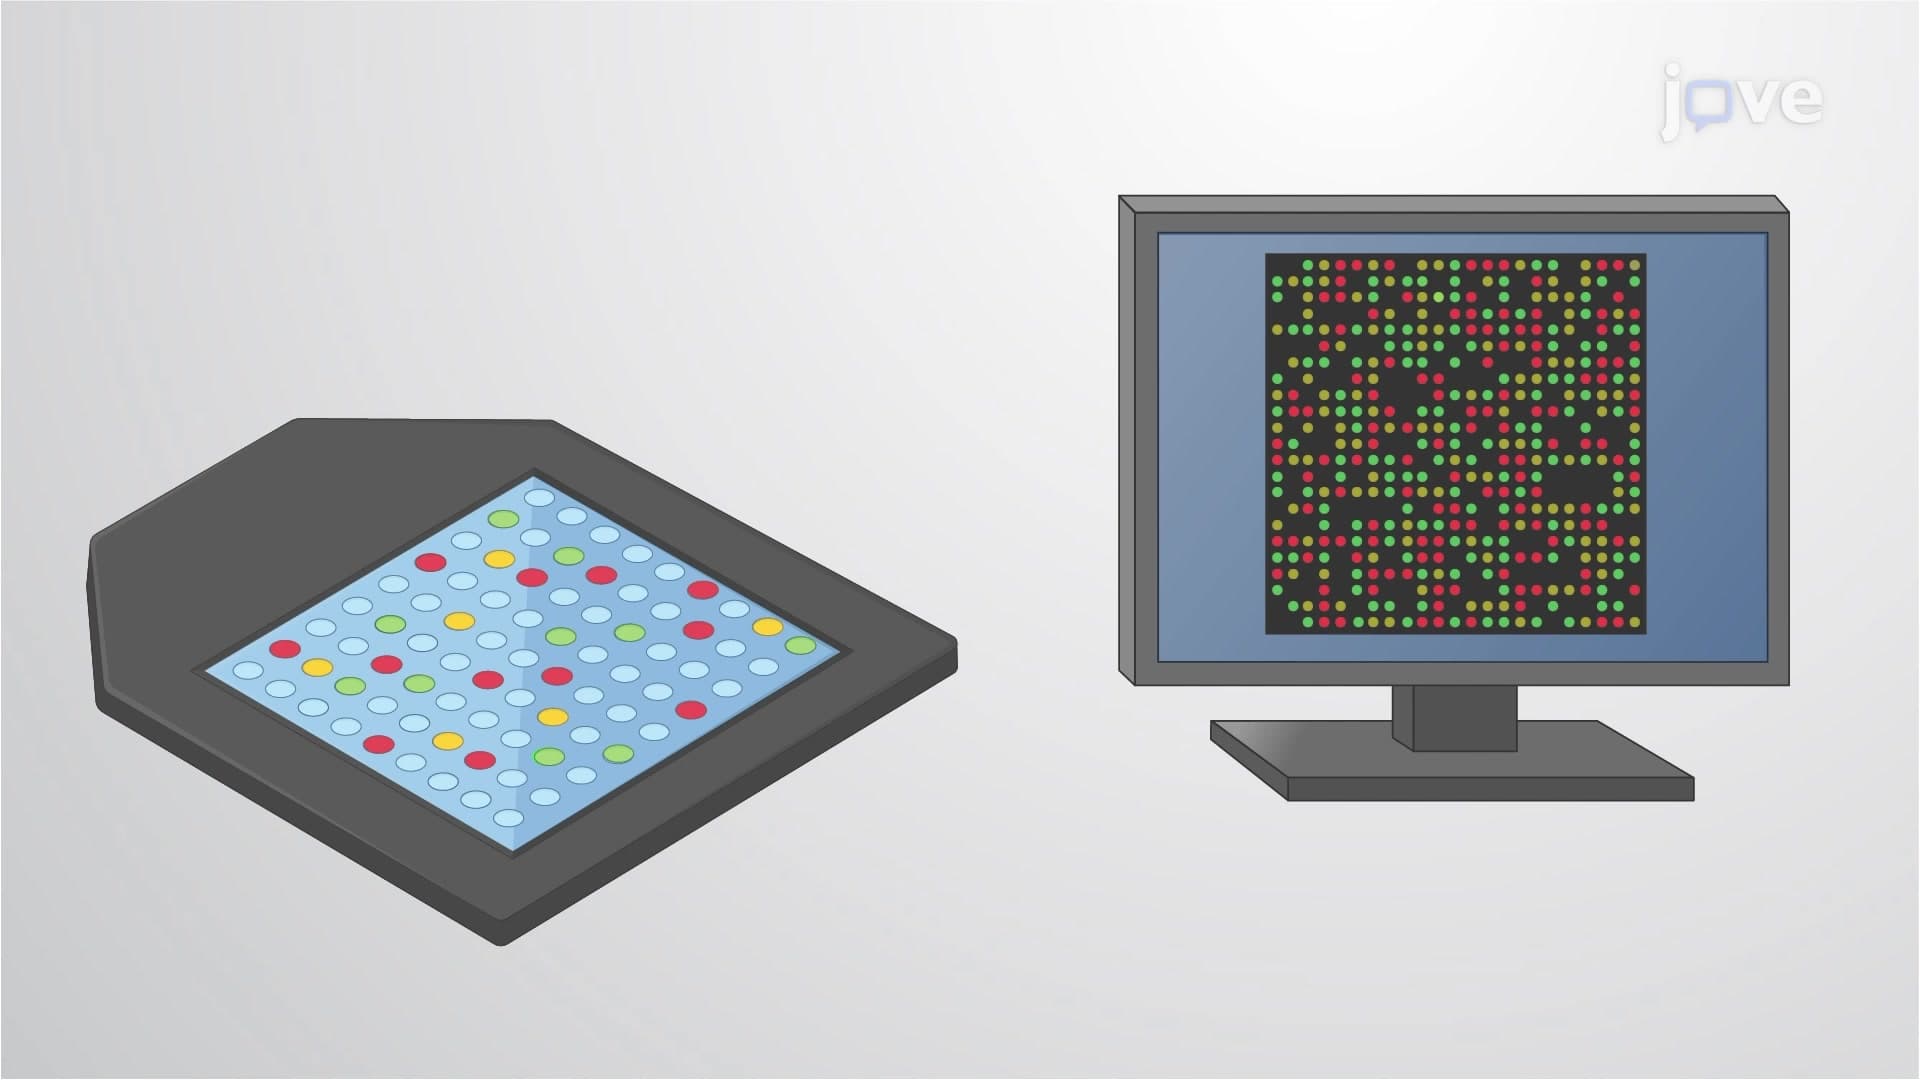
DNA Microarrays
 02:26
Comparing Copy Number Variations and SNPs
Copy number variations or CNVs are the structural variations that cover more than 1kb of DNA sequence. The single nucleotide polymorphism (SNP), on the other hand, is a single nucleotide change or a point mutation that is found in more than 1%...