Related Experiment Video
Updated: Mar 17, 2026
Interactome-Seq: A Protocol for Domainome Library Construction, Validation and Selection by Phage Display and Next Generation Sequencing
Published on: October 3, 2018
Improvement in Protein Domain Identification Is Reached by Breaking Consensus, with the Agreement of Many Profiles
Juliana Bernardes1, Gerson Zaverucha2, Catherine Vaquero3
1Sorbonne Universités, UPMC Univ-Paris 6, CNRS, UMR 7238, Laboratoire de Biologie Computationnelle et Quantitative, Paris, France.

Abstract:
Traditional protein annotation methods describe known domains with probabilistic models representing consensus among homologous domain sequences. However, when relevant signals become too weak to be identified by a global consensus, attempts for annotation fail. Here we address the fundamental question of domain identification for highly divergent proteins. By using high performance computing, we demonstrate that the limits of state-of-the-art annotation methods can be bypassed. We design a new strategy based on the observation that many structural and functional protein constraints are not globally conserved through all species but might be locally conserved in separate clades. We propose a novel exploitation of the large amount of data available: 1. for each known protein domain, several probabilistic clade-centered models are constructed from a large and differentiated panel of homologous sequences, 2. a decision-making protocol combines outcomes obtained from multiple models, 3. a multi-criteria optimization algorithm finds the most likely protein architecture. The method is evaluated for domain and architecture prediction over several datasets and statistical testing hypotheses. Its performance is compared against HMMScan and HHblits, two widely used search methods based on sequence-profile and profile-profile comparison. Due to their closeness to actual protein sequences, clade-centered models are shown to be more specific and functionally predictive than the broadly used consensus models. Based on them, we improved annotation of Plasmodium falciparum protein sequences on a scale not previously possible. We successfully predict at least one domain for 72% of P. falciparum proteins against 63% achieved previously, corresponding to 30% of improvement over the total number of Pfam domain predictions on the whole genome. The method is applicable to any genome and opens new avenues to tackle evolutionary questions such as the reconstruction of ancient domain duplications, the reconstruction of the history of protein architectures, and the estimation of protein domain age. Website and software: http://www.lcqb.upmc.fr/CLADE.
More Related Videos

Related Concept Videos
 02:26
Conservation of Protein Domains Over Different Proteins
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to...
02:26Conservation of Protein Domains
 01:49
Conserved Binding Sites
Binding sites are often located in large pockets, and if their location on a protein’s surface is unknown, it can be predicted using various approaches. The energetic method computationally...
01:49Conserved Binding Sites
 01:18
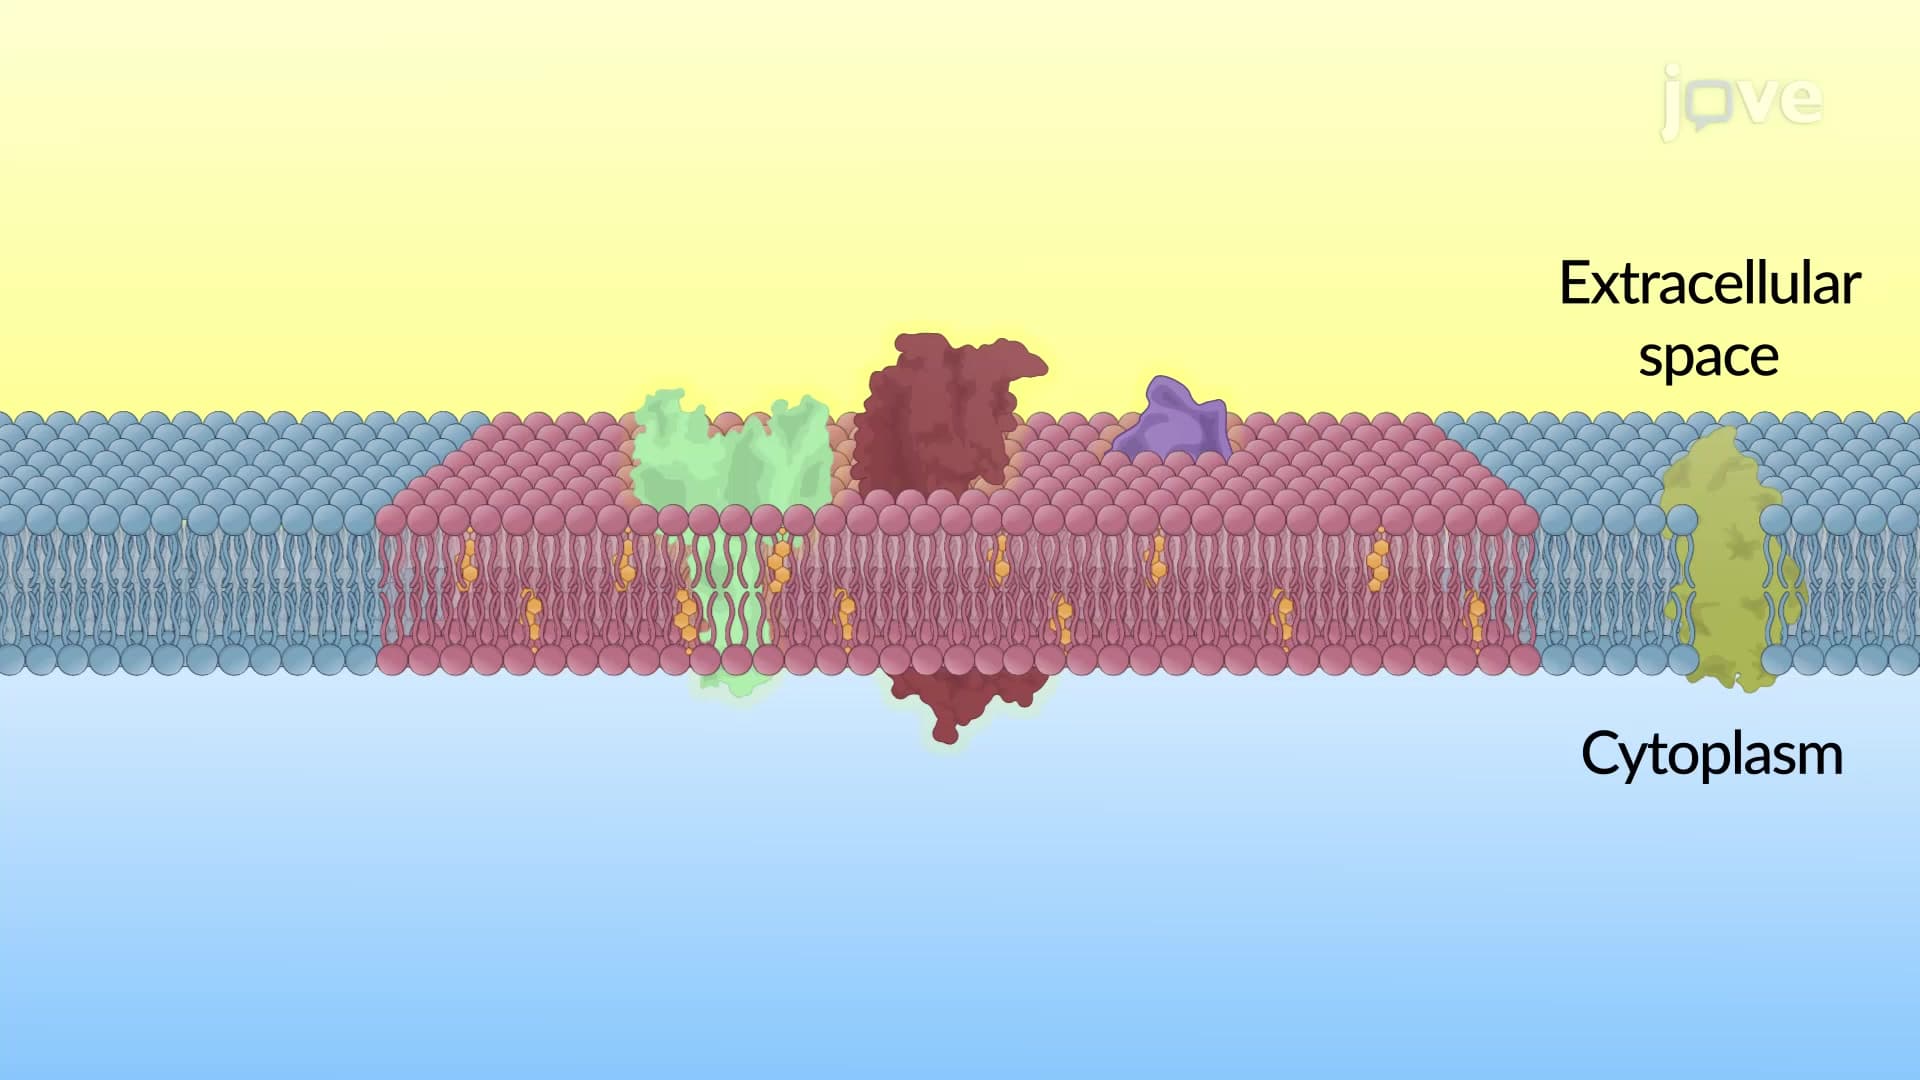
Membrane Domains
Protein Domains
The membrane comprises a group of distinct proteins responsible for carrying out a cell's specific function. For example, the plasma membrane of the human sperm, or a single germ cell, contains a unique set of proteins in the...
 02:04
Protein-protein Interfaces