Related Experiment Video
Updated: Mar 16, 2026

Discovery of Driver Genes in Colorectal HT29-derived Cancer Stem-Like Tumorspheres
Published on: July 22, 2020
Identifying candidate drivers of drug response in heterogeneous cancer by mining high throughput genomics data
1Computer Science and Engineering Department, Institute for Systems Genomics, University of Connecticut, 371 Fairfield Way, Unit 4155, Storrs, CT, 06268, USA. sheida.nabavi@uconn.edu.

Background:
With advances in technologies, huge amounts of multiple types of high-throughput genomics data are available. These data have tremendous potential to identify new and clinically valuable biomarkers to guide the diagnosis, assessment of prognosis, and treatment of complex diseases, such as cancer. Integrating, analyzing, and interpreting big and noisy genomics data to obtain biologically meaningful results, however, remains highly challenging. Mining genomics datasets by utilizing advanced computational methods can help to address these issues.
Results:
To facilitate the identification of a short list of biologically meaningful genes as candidate drivers of anti-cancer drug resistance from an enormous amount of heterogeneous data, we employed statistical machine-learning techniques and integrated genomics datasets. We developed a computational method that integrates gene expression, somatic mutation, and copy number aberration data of sensitive and resistant tumors. In this method, an integrative method based on module network analysis is applied to identify potential driver genes. This is followed by cross-validation and a comparison of the results of sensitive and resistance groups to obtain the final list of candidate biomarkers. We applied this method to the ovarian cancer data from the cancer genome atlas. The final result contains biologically relevant genes, such as COL11A1, which has been reported as a cis-platinum resistant biomarker for epithelial ovarian carcinoma in several recent studies.
Conclusions:
The described method yields a short list of aberrant genes that also control the expression of their co-regulated genes. The results suggest that the unbiased data driven computational method can identify biologically relevant candidate biomarkers. It can be utilized in a wide range of applications that compare two conditions with highly heterogeneous datasets.
More Related Videos
 10:24
Generation of Heterogeneous Drug Gradients Across Cancer Populations on a Microfluidic Evolution Accelerator for Real-Time Observation
Published on: September 19, 2019
 07:41
Performing Data Mining And Integrative Analysis Of Biomarker in Breast Cancer Using Multiple Publicly Accessible Databases
Published on: May 17, 2019
Related Concept Videos
 01:29
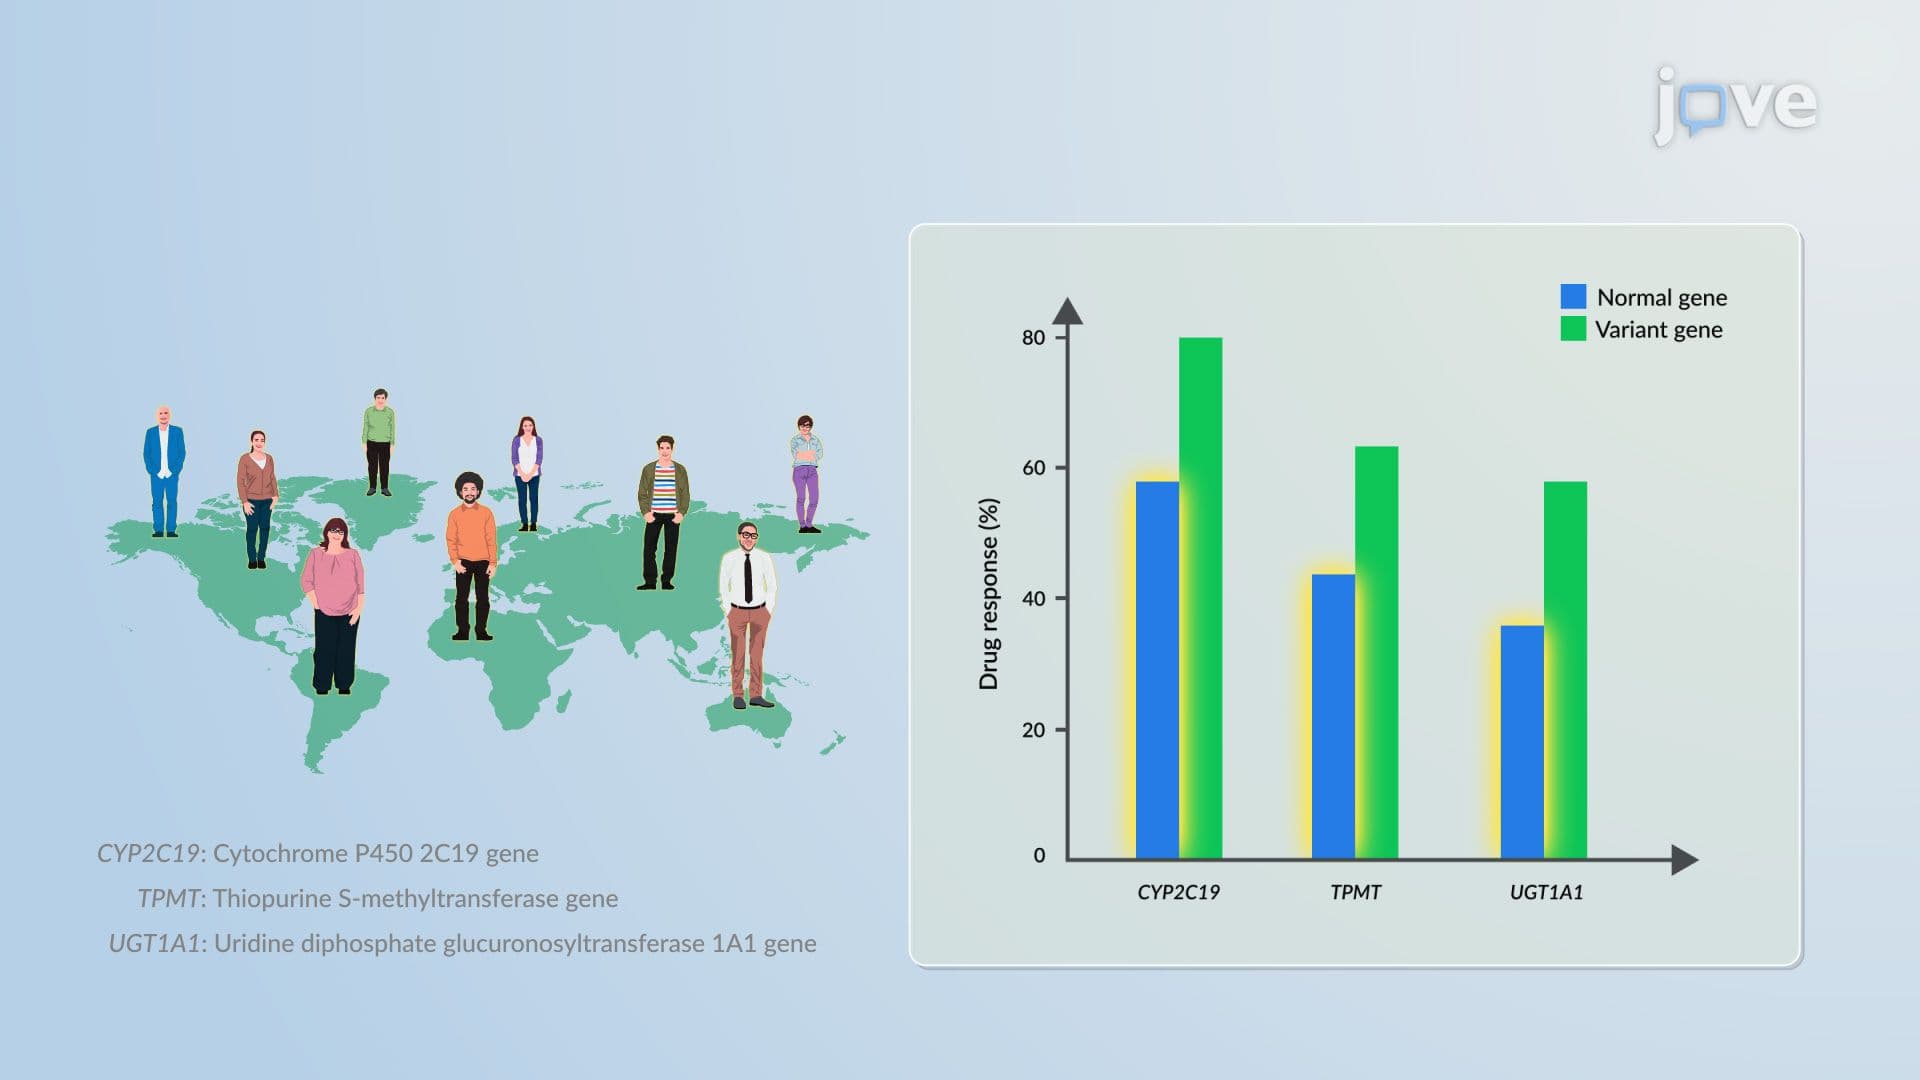
Pharmacogenomics: Identification of New Drug Targets
 01:29
Pharmacogenetics and Pharmacogenomics: Overview
 02:56
Treatment Resistant Cancers
 01:11
Pharmacogenetics of Drug Targets: β₂-Adrenergic Receptors, Apo E, Thymidylate Synthase
 02:50
Combination Therapies and Personalized Medicine
The combination of the drug acetazolamide and sulforaphane is a good example of combination therapy to treat cancer. The cells in the interior of a large tumor often die due to the hypoxic and...