Evaluating the accuracy of protein design using native secondary sub-structures
Related Experiment Video
Updated: Mar 15, 2026

Application of I TASSER, trRosetta, UCSF Chimera, HADDOCK server, and HEX loria for De Novo and In Silico Design of Proteins
Published on: July 8, 2025
Marziyeh Movahedi1, Fatemeh Zare-Mirakabad2, Seyed Shahriar Arab3
1Department of Mathematics and Computer Science, Amirkabir University of Technology, Tehran, Iran.

Background:
According to structure-dependent function of proteins, two main challenging problems called Protein Structure Prediction (PSP) and Inverse Protein Folding (IPF) are investigated. In spite of IPF essential applications, it has not been investigated as much as PSP problem. In fact, the ultimate goal of IPF problem or protein design is to create proteins with enhanced properties or even novel functions. One of the major computational challenges in protein design is its large sequence space, namely searching through all plausible sequences is impossible. Inasmuch as, protein secondary structure represents an appropriate primary scaffold of the protein conformation, undoubtedly studying the Protein Secondary Structure Inverse Folding (PSSIF) problem is a quantum leap forward in protein design, as it can reduce the search space. In this paper, a novel genetic algorithm which uses native secondary sub-structures is proposed to solve PSSIF problem. In essence, evolutionary information can lead the algorithm to design appropriate amino acid sequences respective to the target secondary structures. Furthermore, they can be folded to tertiary structures almost similar to their reference 3D structures.
Results:
The proposed algorithm called GAPSSIF benefits from evolutionary information obtained by solved proteins in the PDB. Therefore, we construct a repository of protein secondary sub-structures to accelerate convergence of the algorithm. The secondary structure of designed sequences by GAPSSIF is comparable with those obtained by Evolver and EvoDesign. Although we do not explicitly consider tertiary structure features through the algorithm, the structural similarity of native and designed sequences declares acceptable values.
Conclusions:
Using the evolutionary information of native structures can significantly improve the quality of designed sequences. In fact, the combination of this information and effective features such as solvent accessibility and torsion angles leads IPF problem to an efficient solution. GAPSSIF can be downloaded at http://bioinformatics.aut.ac.ir/GAPSSIF/ .


Related Concept Videos
 01:25
Protein Folding
Protein Structure Is Critical to Its Biological Function
Proteins perform a wide range of biological functions such as catalyzing chemical reactions, providing...
 01:22
Protein Folding
01:22Protein Folding
 02:15
Protein and Protein Structure
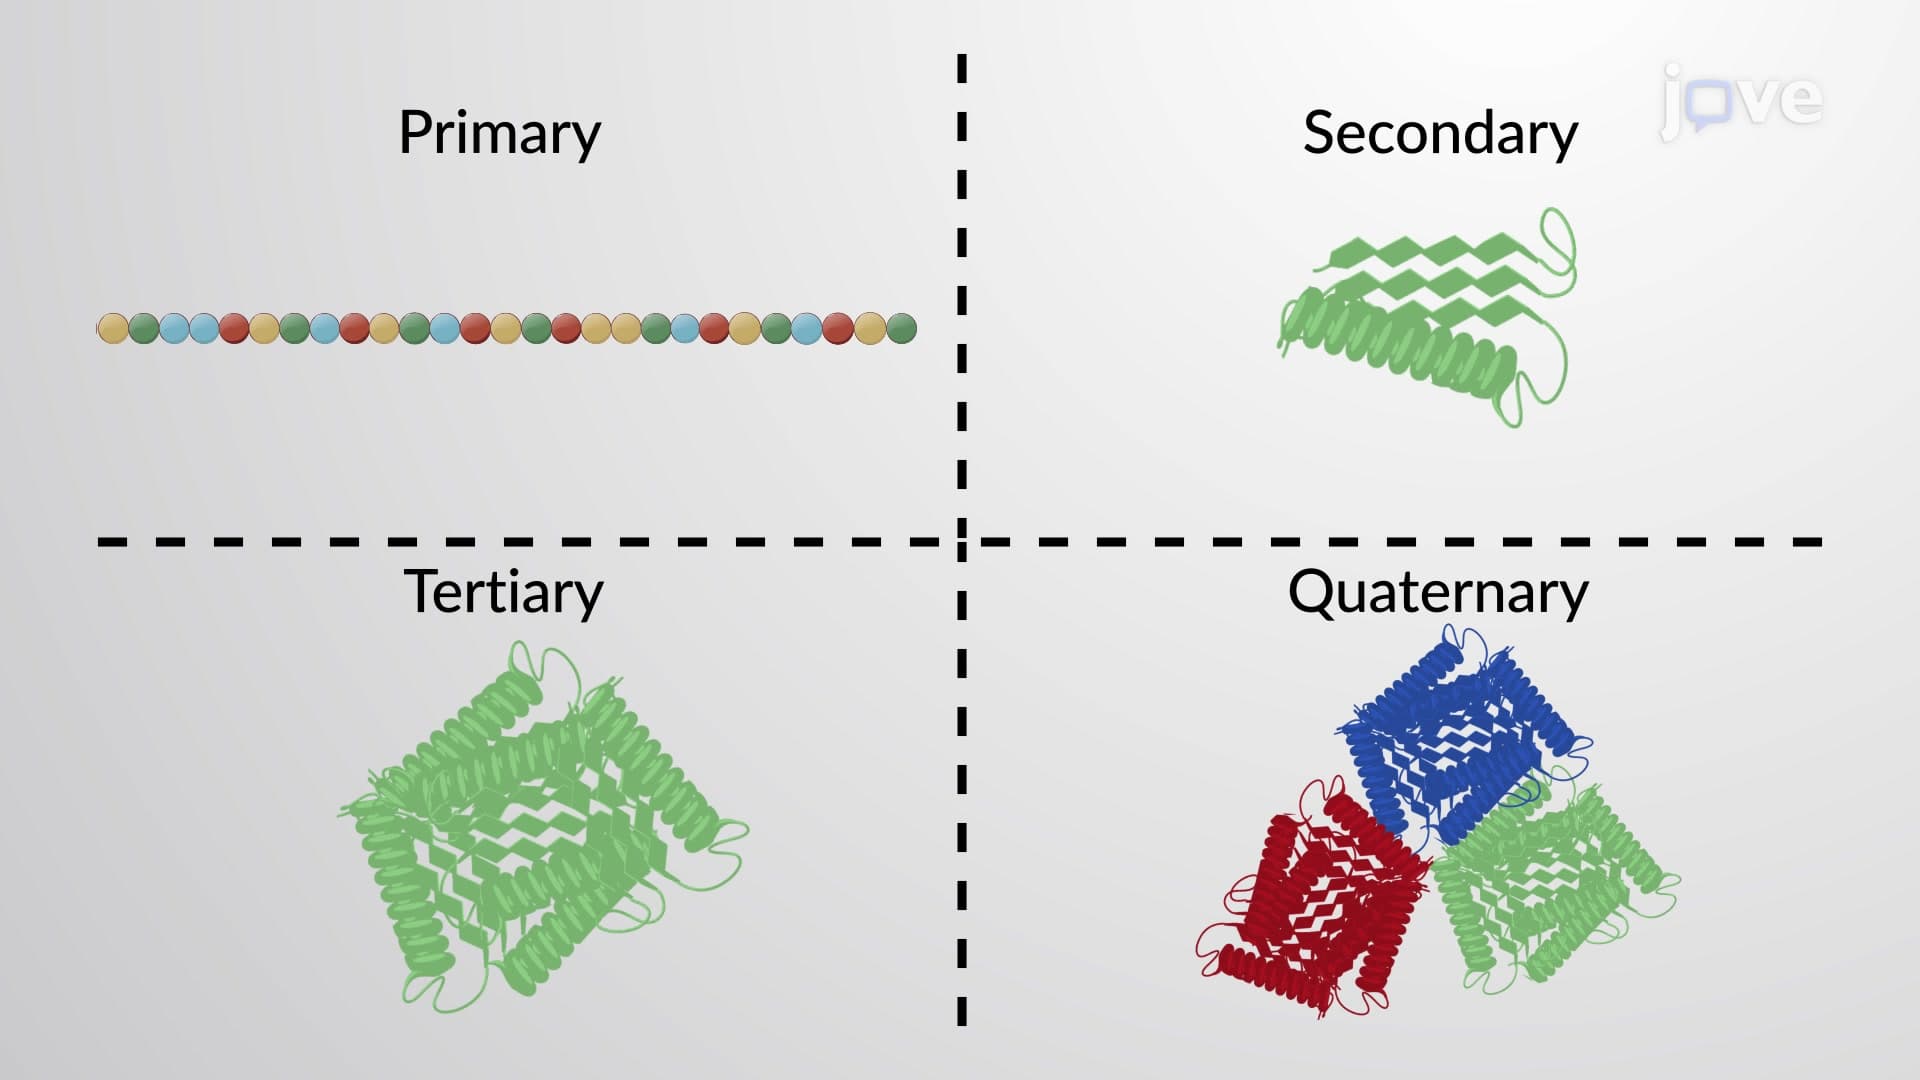
A protein's shape is critical to its function. For example, an enzyme...
 01:49
Conserved Binding Sites
Binding sites are often located in large pockets, and if their location on a protein’s surface is unknown, it can be predicted using various approaches. The energetic method computationally...
 01:13
Protein Organization