Related Experiment Video
Updated: Mar 15, 2026
An Inertial Measurement Unit Based Method to Estimate Hip and Knee Joint Kinematics in Team Sport Athletes on the Field
Published on: May 26, 2020
Player's success prediction in rugby union: From youth performance to senior level placing
Federico Y Fontana1, Alessandro L Colosio1, Giorgio Da Lozzo1
1Department of Neurosciences, Biomedicine and Movement Sciences, University of Verona, Italy; Rugby Research Centre, University of Verona, Italy.

Objectives:
The study questioned if and to what extent specific anthropometric and functional characteristics measured in youth draft camps, can accurately predict subsequent career progression in rugby union.
Design:
Original research.
Methods:
Anthropometric and functional characteristics of 531 male players (U16) were retrospectively analysed in relation to senior level team representation at age 21-24. Players were classified as International (Int: National team and international clubs) or National (Nat: 1st, 2nd and other divisions and dropout). Multivariate analysis of variance (one-way MANOVA) tested differences between Int and Nat, along a combination of anthropometric (body mass, height, body fat, fat-free mass) and functional variables (SJ, CMJ, t15m, t30m, VO2max). A discriminant function (DF) was determined to predict group assignment based on the linear combination of variables that best discriminate groups. Correct level assignment was expressed as % hit rate.
Results:
A combination of anthropometric and functional characteristics reflects future level assignment (Int vs. Nat). Players' success can be accurately predicted (hit rate=81% and 77% for Int and Nat respectively) by a DF that combines anthropometric and functional variables as measured at ∼15 years of age, percent body fat and speed being the most influential predictors of group stratification.
Conclusions:
Within a group of 15 year-olds with exceptional physical characteristics, future players' success can be predicted using a linear combination of anthropometric and functional variables, among which a lower percent body fat and higher speed over a 15m sprint provide the most important predictors of the highest career success.
Related Concept Videos
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
 01:07
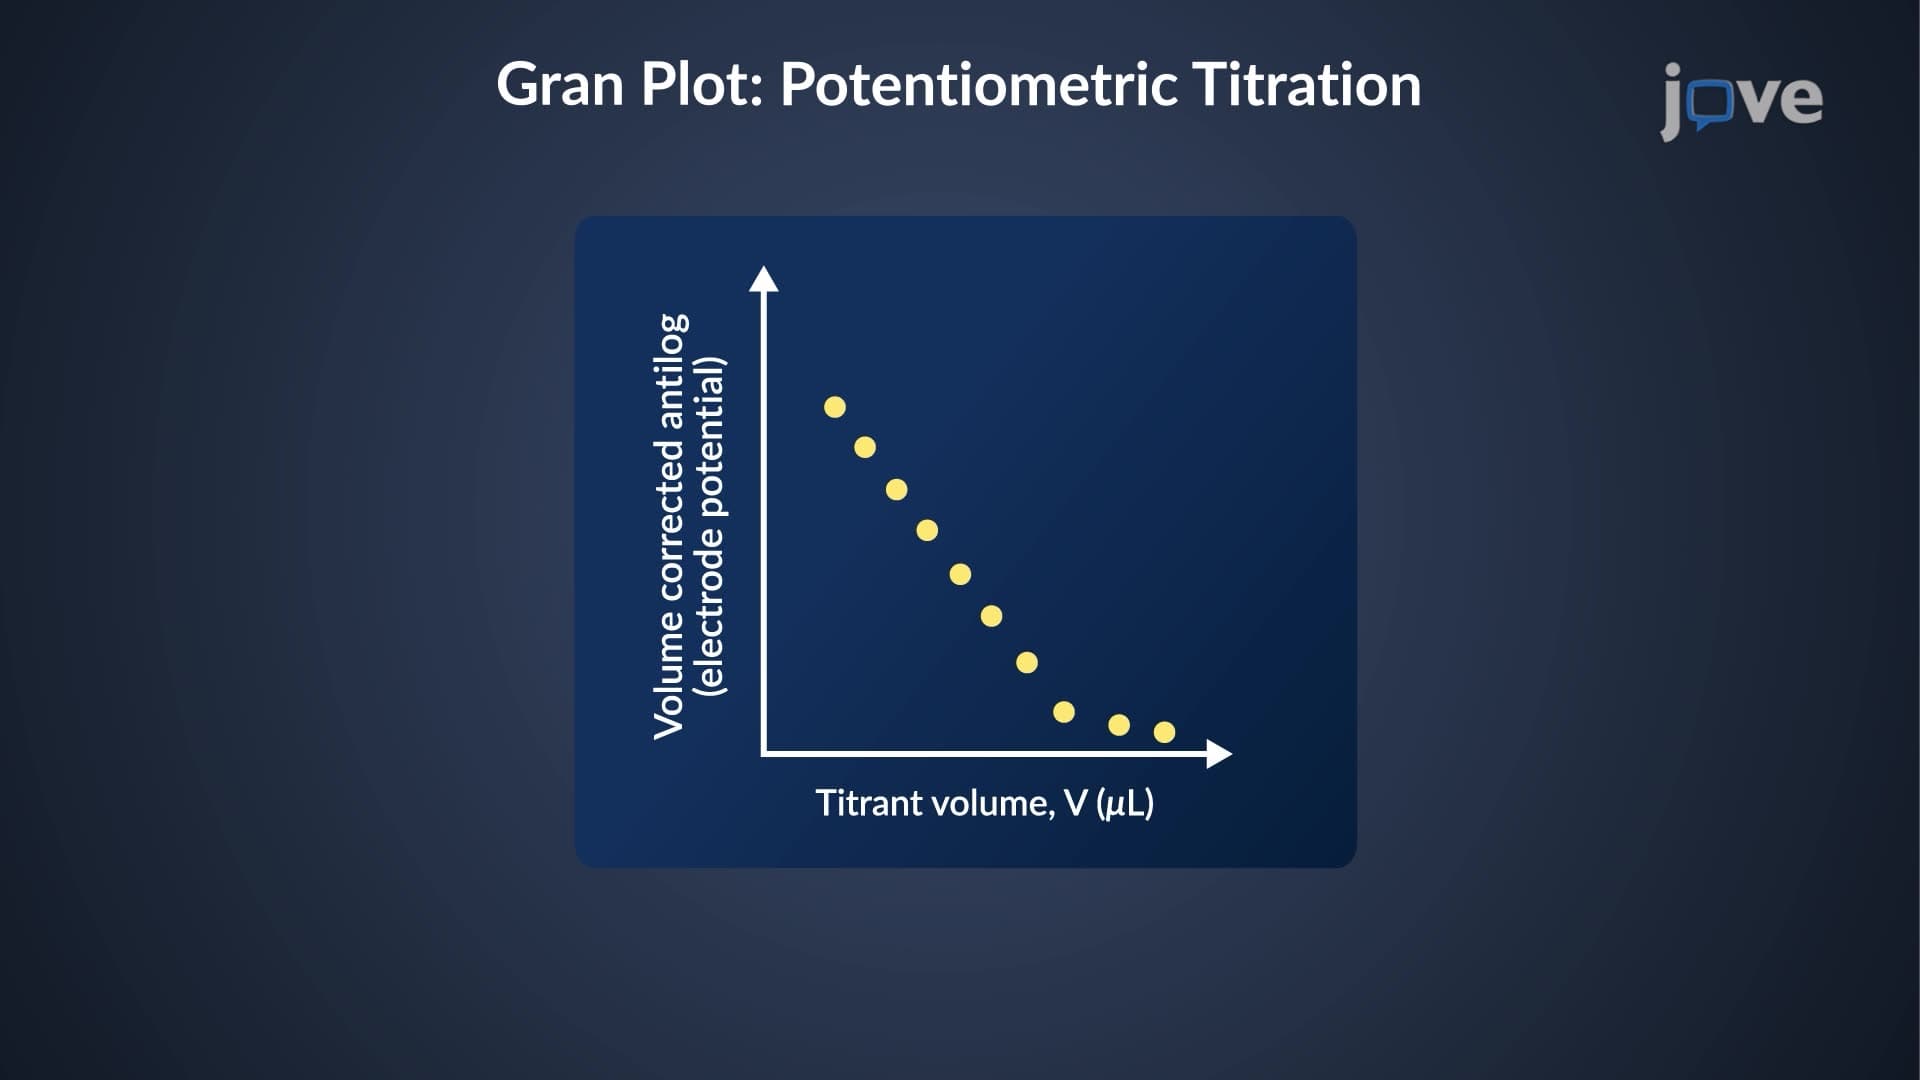
End Point Prediction: Gran Plot
For potentiometric titration, the Gran plot is created by plotting...
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:19
Variation
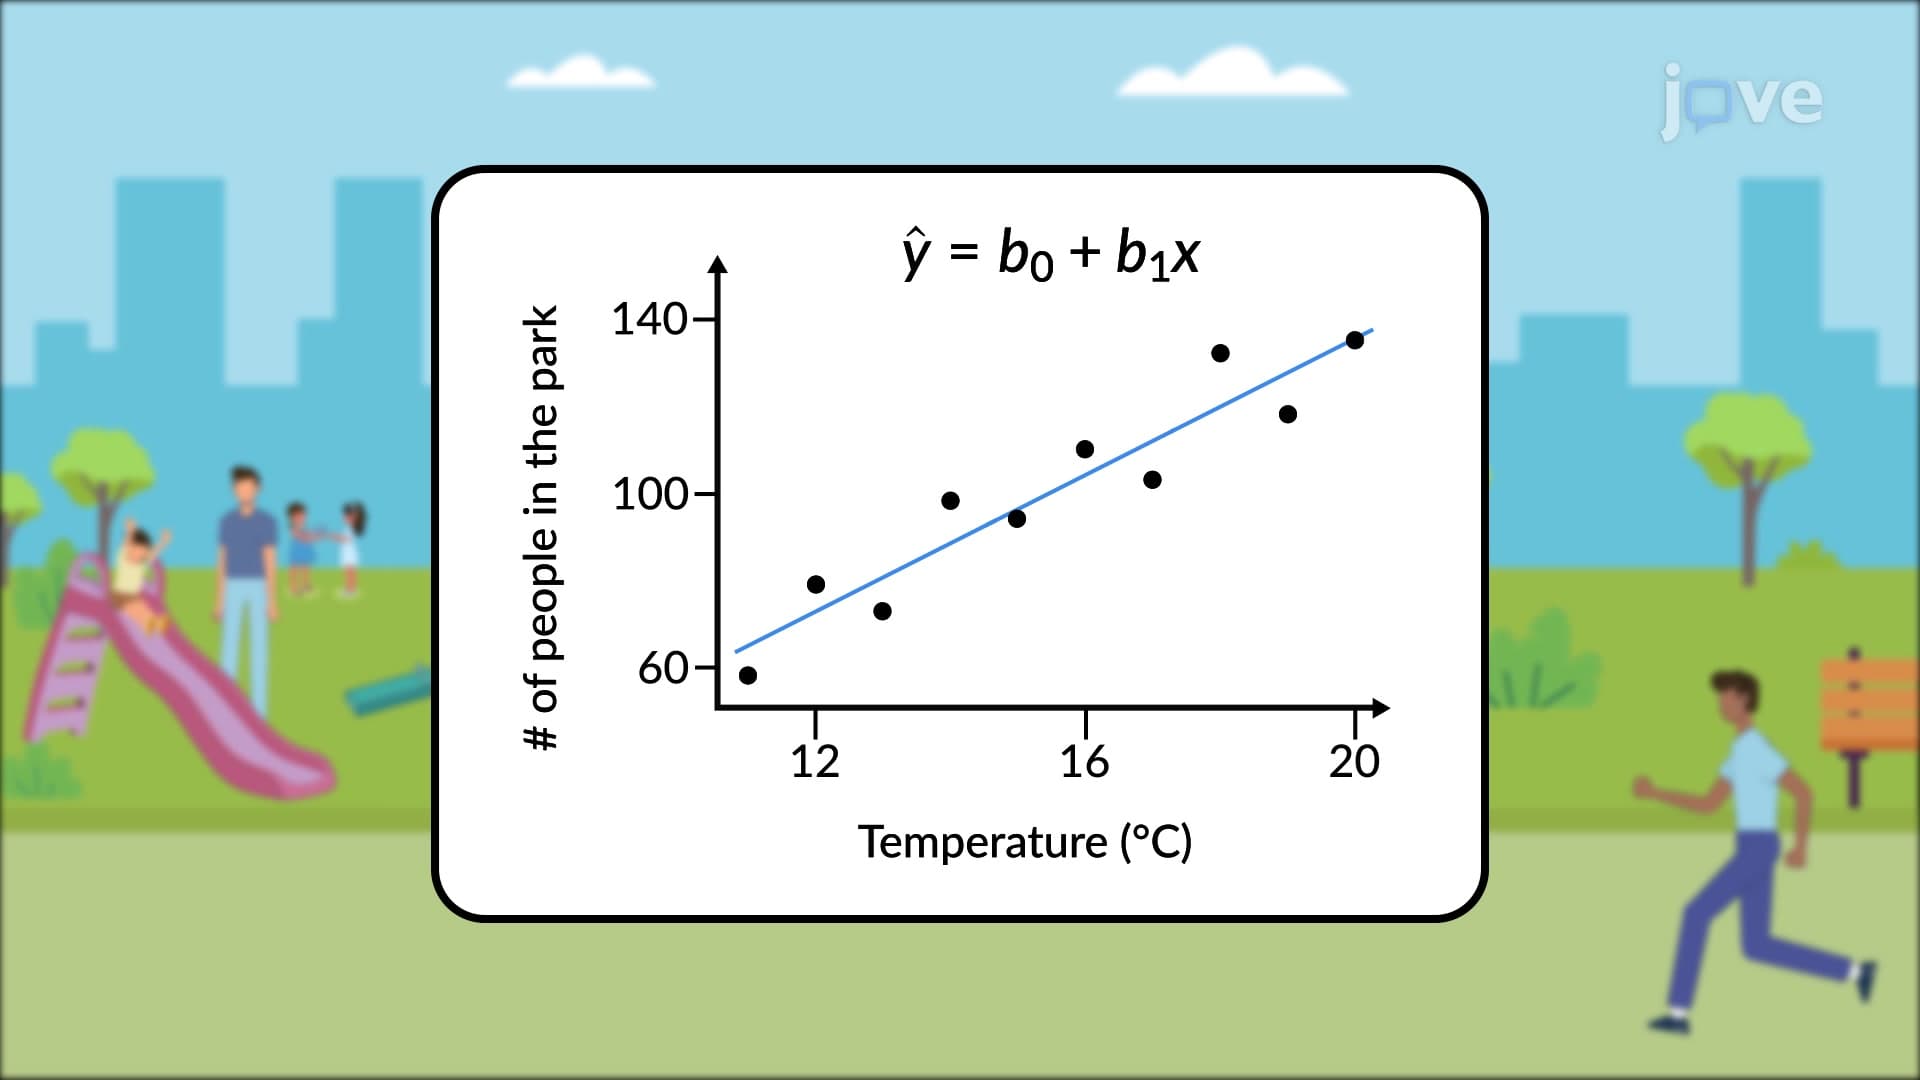
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...