Related Experiment Video
Updated: Mar 14, 2026


Development of an Individual-Tree Basal Area Increment Model using a Linear Mixed-Effects Approach
Published on: July 3, 2020
A sparsity-controlled vector autoregressive model

Abstract:
Vector autoregressive (VAR) models constitute a powerful and well studied tool to analyze multivariate time series. Since sparseness, crucial to identify and visualize joint dependencies and relevant causalities, is not expected to happen in the standard VAR model, several sparse variants have been introduced in the literature. However, in some cases it might be of interest to control some dimensions of the sparsity, as e.g. the number of causal features allowed in the prediction. To authors extent none of the existent methods endows the user with full control over the different aspects of the sparsity of the solution. In this article, we propose a versatile sparsity-controlled VAR model which enables a proper visualization of potential causalities while allows the user to control different dimensions of the sparsity if she holds some preferences regarding the sparsity of the outcome. The model coefficients are found as the solution to an optimization problem, solvable by standard numerical optimization routines. The tests performed on both simulated and real-life time series show that our approach may outperform a greedy algorithm and different Lasso approaches in terms of prediction errors and sparsity.
More Related Videos


Related Concept Videos
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:08
Vector Algebra: Method of Components
In many applications, the magnitudes and directions of...
 01:23
Quadratic Models
 01:09
Random Variables
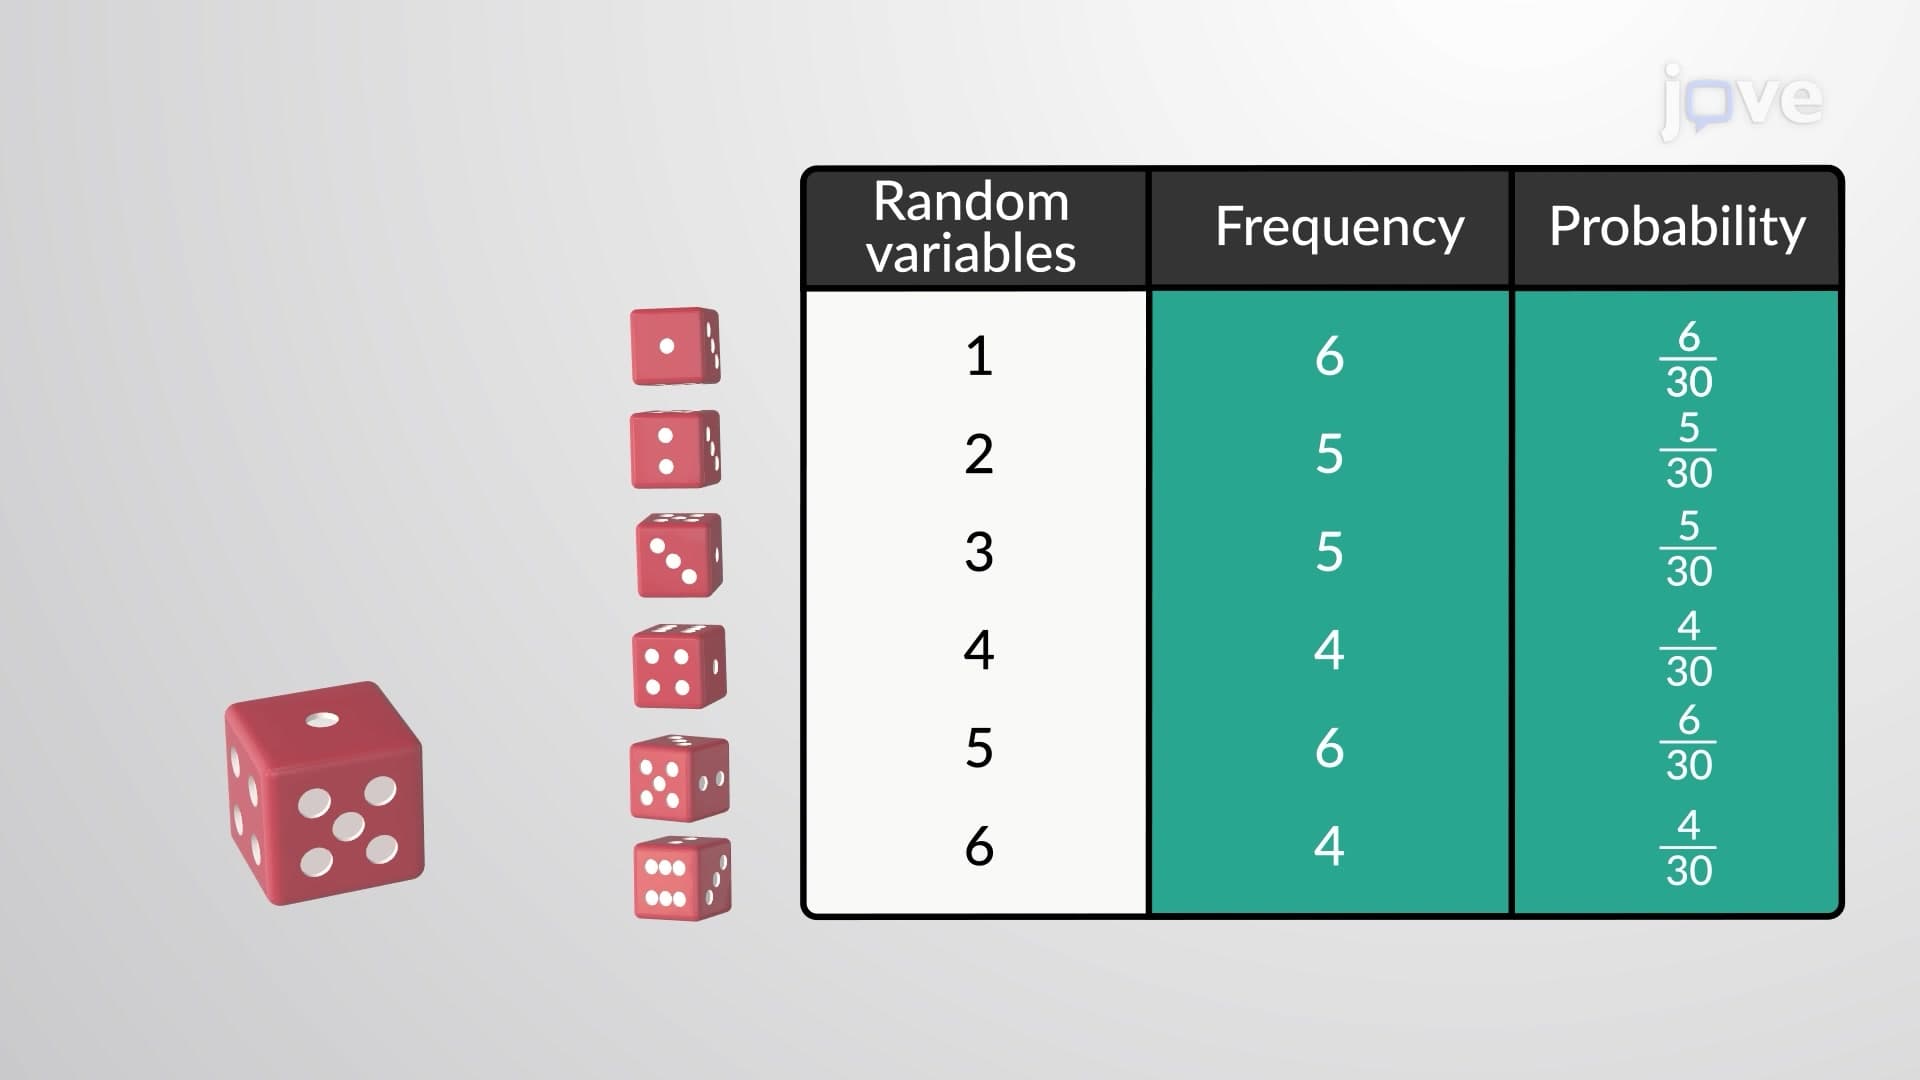
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
 01:06
Model Approaches for Pharmacokinetic Data: Distributed Parameter Models
The distributed parameter models are specifically designed to account for variations and differences in some drug classes. This model is particularly useful for assessing regional concentrations of anticancer or...
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
On...