Related Experiment Video
Updated: Mar 14, 2026

A User-friendly and Powerful R Analysis of Large-scale Datasets
Published on: November 4, 2025
Biospark: scalable analysis of large numerical datasets from biological simulations and experiments using Hadoop and
Max Klein1, Rati Sharma1, Chris H Bohrer1
1Department of Biophysics, Johns Hopkins University, Baltimore, MD 21218, USA.

Abstract:
Data-parallel programming techniques can dramatically decrease the time needed to analyze large datasets. While these methods have provided significant improvements for sequencing-based analyses, other areas of biological informatics have not yet adopted them. Here, we introduce Biospark, a new framework for performing data-parallel analysis on large numerical datasets. Biospark builds upon the open source Hadoop and Spark projects, bringing domain-specific features for biology.
Availability And Implementation:
Source code is licensed under the Apache 2.0 open source license and is available at the project website: https://www.assembla.com/spaces/roberts-lab-public/wiki/Biospark CONTACT: eroberts@jhu.eduSupplementary information: Supplementary data are available at Bioinformatics online.
Related Concept Videos
 01:12
Statistical Software for Data Analysis and Clinical Trials
 01:14
Statistical Analysis System (SAS)
Applications: SAS finds applications in numerous fields, including healthcare for clinical trial analysis, finance for risk assessment, marketing for customer data analysis, and...
 01:10
Statgraphics
 01:22
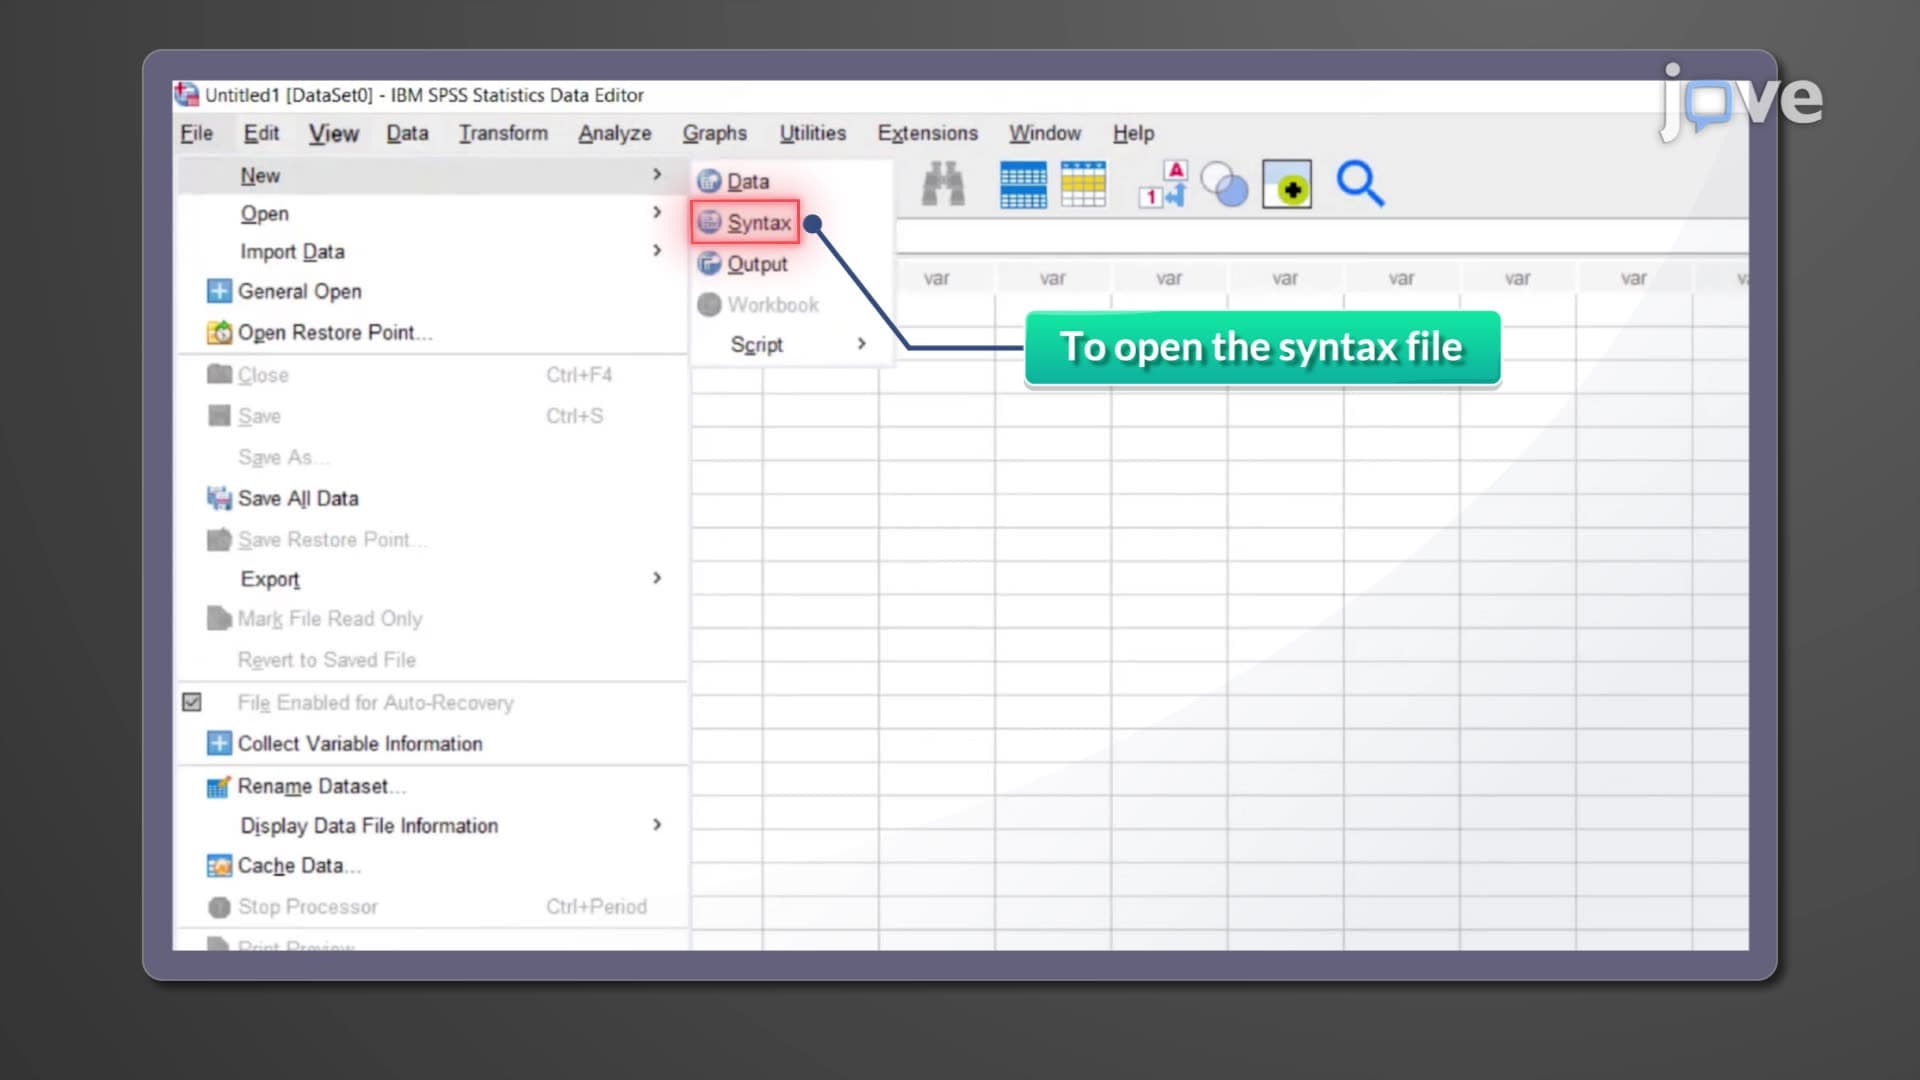
Statistical Package for the Social Sciences (SPSS)
SPSS streamlines the process from data preparation to analysis and reporting. It is characterized by its user-friendly interface, which conceals...