Related Experiment Video
Updated: Aug 12, 2026
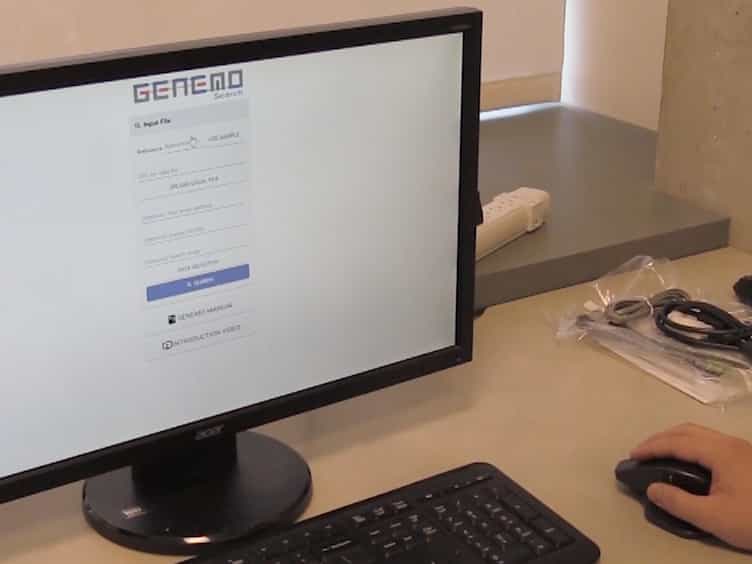

Pattern-based Search of Epigenomic Data Using GeNemo
Published on: October 8, 2017
EpiMINE, a computational program for mining epigenomic data
SriGanesh Jammula1, Diego Pasini1
1Department of Experimental Oncology, European Institute of Oncology, Via Adamello 16, 20139 Milan, Italy.

Background:
In epigenetic research, both the increasing ease of high-throughput sequencing and a greater interest in genome-wide studies have resulted in an exponential flooding of epigenetic-related data in public domain. This creates an opportunity for exploring data outside the limits of any specific query-centred study. Such data have to undergo standard primary analyses that are accessible with multiple well-stabilized programs. Further downstream analyses, such as genome-wide comparative, correlative and quantitative analyses, are critical in deciphering key biological features. However, these analyses are only accessible for computational researchers and completely lack platforms capable of handling, analysing and linking multiple interdisciplinary datasets with efficient analytical methods.
Results:
Here, we present EpiMINE, a program for mining epigenomic data. It is a user-friendly, stand-alone computational program designed to support multiple datasets, for performing genome-wide correlative and quantitative analysis of ChIP-seq and RNA-seq data. Using data available from the ENCODE project, we illustrated several features of EpiMINE through different biological scenarios to show how easy some known observations can be verified. These results highlight how these approaches can be helpful in identifying novel biological features.
Conclusions:
EpiMINE performs different kinds of genome-wide quantitative and correlative analyses, using ChIP-seq- and RNA-seq-related datasets. Its framework enables it to be used by both experimental and computational researchers. EpiMINE can be downloaded from https://sourceforge.net/projects/epimine/.