Parametric bootstrapping for biological sequence motifs
Related Experiment Video
Updated: Mar 14, 2026
Using Phylogenetic Analysis to Investigate Eukaryotic Gene Origin
Published on: August 14, 2018
Patrick K O'Neill1, Ivan Erill2
1Department of Biological Sciences, University of Maryland, Baltimore County, 1000 Hilltop Circle, Baltimore, 21250, US.

Background:
Biological sequence motifs drive the specific interactions of proteins and nucleic acids. Accordingly, the effective computational discovery and analysis of such motifs is a central theme in bioinformatics. Many practical questions about the properties of motifs can be recast as random sampling problems. In this light, the task is to determine for a given motif whether a certain feature of interest is statistically unusual among relevantly similar alternatives. Despite the generality of this framework, its use has been frustrated by the difficulties of defining an appropriate reference class of motifs for comparison and of sampling from it effectively.
Results:
We define two distributions over the space of all motifs of given dimension. The first is the maximum entropy distribution subject to mean information content, and the second is the truncated uniform distribution over all motifs having information content within a given interval. We derive exact sampling algorithms for each. As a proof of concept, we employ these sampling methods to analyze a broad collection of prokaryotic and eukaryotic transcription factor binding site motifs. In addition to positional information content, we consider the informational Gini coefficient of the motif, a measure of the degree to which information is evenly distributed throughout a motif's positions. We find that both prokaryotic and eukaryotic motifs tend to exhibit higher informational Gini coefficients (IGC) than would be expected by chance under either reference distribution. As a second application, we apply maximum entropy sampling to the motif p-value problem and use it to give elementary derivations of two new estimators.
Conclusions:
Despite the historical centrality of biological sequence motif analysis, this study constitutes to our knowledge the first use of principled null hypotheses for sequence motifs given information content. Through their use, we are able to characterize for the first time differerences in global motif statistics between biological motifs and their null distributions. In particular, we observe that biological sequence motifs show an unusual distribution of IGC, presumably due to biochemical constraints on the mechanisms of direct read-out.
More Related Videos
 07:55
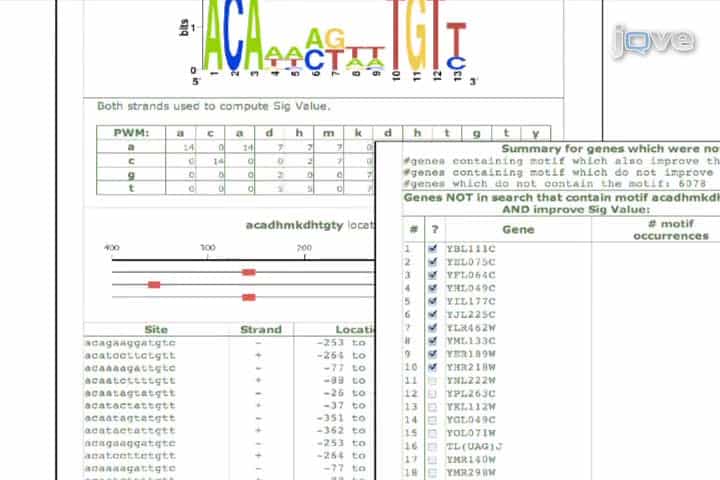
Using SCOPE to Identify Potential Regulatory Motifs in Coregulated Genes
Published on: May 31, 2011
 12:29
Identifying Transcription Factor Olig2 Genomic Binding Sites in Acutely Purified PDGFRα+ Cells by Low-cell Chromatin Immunoprecipitation Sequencing Analysis
Published on: April 16, 2018
Related Concept Videos
 01:24
Bootstrapping
 02:26
Conservation of Protein Domains Over Different Proteins
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to...
 02:51
Multi-species Conserved Sequences
Although the genome of each species varies greatly from each other, a few sequences are highly conserved. Such conserved...
 02:54
Evolutionary Relationships through Genome Comparisons
 02:02
Cis-regulatory Sequences
02:02Cis-regulatory Sequences