Related Experiment Video
Updated: Mar 10, 2026


Development of an Individual-Tree Basal Area Increment Model using a Linear Mixed-Effects Approach
Published on: July 3, 2020
Node-Splitting Generalized Linear Mixed Models for Evaluation of Inconsistency in Network Meta-Analysis
1Department of Public Health and Institute of Epidemiology and Preventive Medicine, College of Public Health, National Taiwan University, Taipei, Taiwan.

Background:
Network meta-analysis for multiple treatment comparisons has been a major development in evidence synthesis methodology. The validity of a network meta-analysis, however, can be threatened by inconsistency in evidence within the network. One particular issue of inconsistency is how to directly evaluate the inconsistency between direct and indirect evidence with regard to the effects difference between two treatments. A Bayesian node-splitting model was first proposed and a similar frequentist side-splitting model has been put forward recently. Yet, assigning the inconsistency parameter to one or the other of the two treatments or splitting the parameter symmetrically between the two treatments can yield different results when multi-arm trials are involved in the evaluation.
Objectives:
We aimed to show that a side-splitting model can be viewed as a special case of design-by-treatment interaction model, and different parameterizations correspond to different design-by-treatment interactions.
Methods:
We demonstrated how to evaluate the side-splitting model using the arm-based generalized linear mixed model, and an example data set was used to compare results from the arm-based models with those from the contrast-based models.
Results & Conclusions:
The three parameterizations of side-splitting make slightly different assumptions: the symmetrical method assumes that both treatments in a treatment contrast contribute to inconsistency between direct and indirect evidence, whereas the other two parameterizations assume that only one of the two treatments contributes to this inconsistency. With this understanding in mind, meta-analysts can then make a choice about how to implement the side-splitting method for their analysis.
Insights
Network meta-analysis validity relies on consistency. This study clarifies side-splitting model assumptions for evaluating direct versus indirect evidence inconsistency in treatment comparisons.
Area of Science:
- Biostatistics
- Evidence Synthesis
- Medical Research Methodology
Background:
- Network meta-analysis (NMA) is crucial for synthesizing evidence from multiple treatment comparisons.
- Network inconsistency, particularly between direct and indirect evidence, can threaten NMA validity.
- Existing methods like Bayesian node-splitting and frequentist side-splitting models address inconsistency, but parameter assignment in multi-arm trials can affect results.
Purpose of the Study:
- To demonstrate that the side-splitting model is a specific instance of a design-by-treatment interaction model.
- To illustrate how different parameterizations of the side-splitting model correspond to distinct design-by-treatment interactions.
Main Methods:
- Evaluation of the side-splitting model using an arm-based generalized linear mixed model.
- Comparison of results from arm-based models with contrast-based models using an example dataset.
Main Results:
- The three parameterizations of the side-splitting model involve different assumptions regarding the contribution of treatments to inconsistency.
- Symmetrical parameterization assumes both treatments contribute to inconsistency.
- Alternative parameterizations assume only one treatment contributes to inconsistency.
Conclusions:
- Understanding the distinct assumptions of side-splitting model parameterizations is essential for meta-analysts.
- This knowledge aids in selecting the appropriate implementation of the side-splitting method for specific analyses.
- Informed choices in parameterization can improve the reliability of network meta-analysis results.
Related Concept Videos
 01:29
Mechanistic Models: Compartment Models in Algorithms for Numerical Problem Solving
In individual population analyses, different algorithms are employed, such as Cauchy's method, which uses a...
 01:19
Survival Tree
Building a Survival Tree
Constructing a...
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:20
Bioequivalence Experimental Study Designs: Completely Randomized and Randomized Block Designs
 01:16
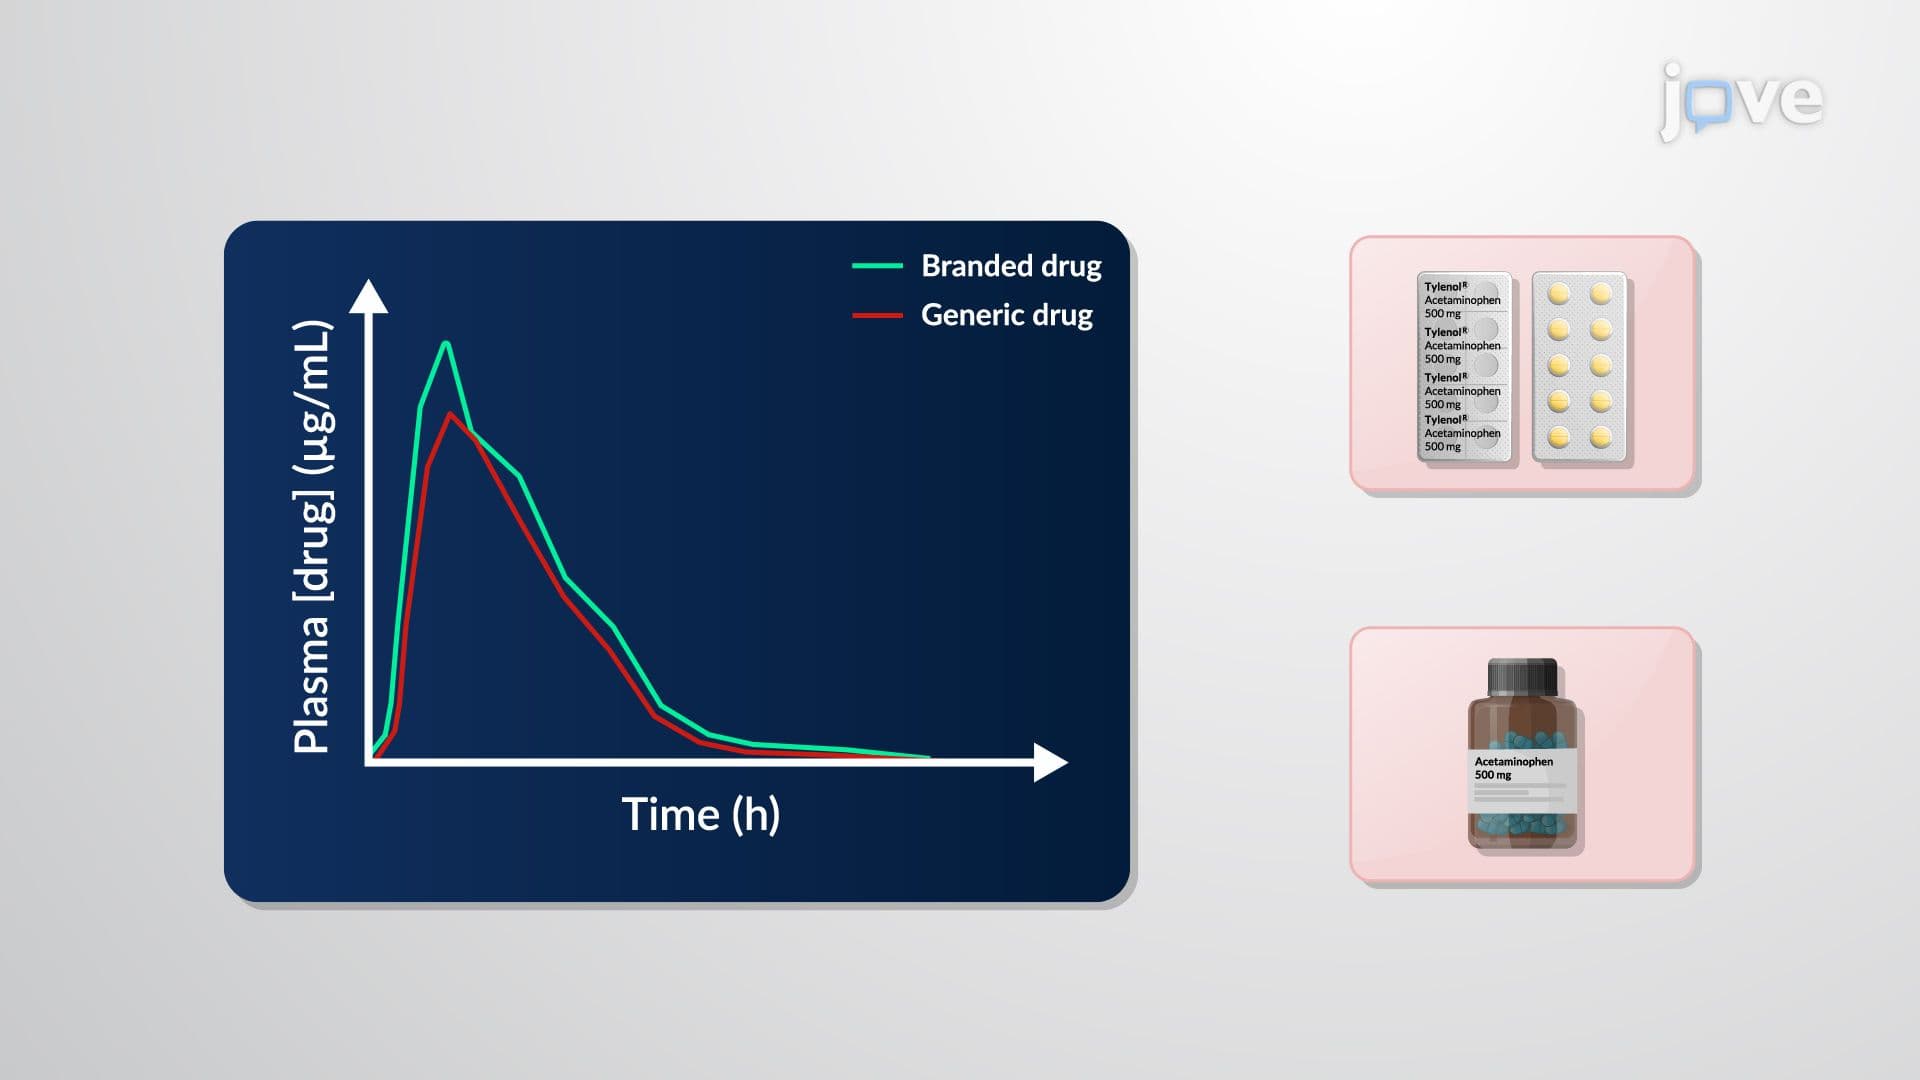
Bioequivalence Data: Statistical Interpretation