A general statistical framework for subgroup identification and comparative treatment scoring
Related Experiment Video
Updated: Mar 7, 2026
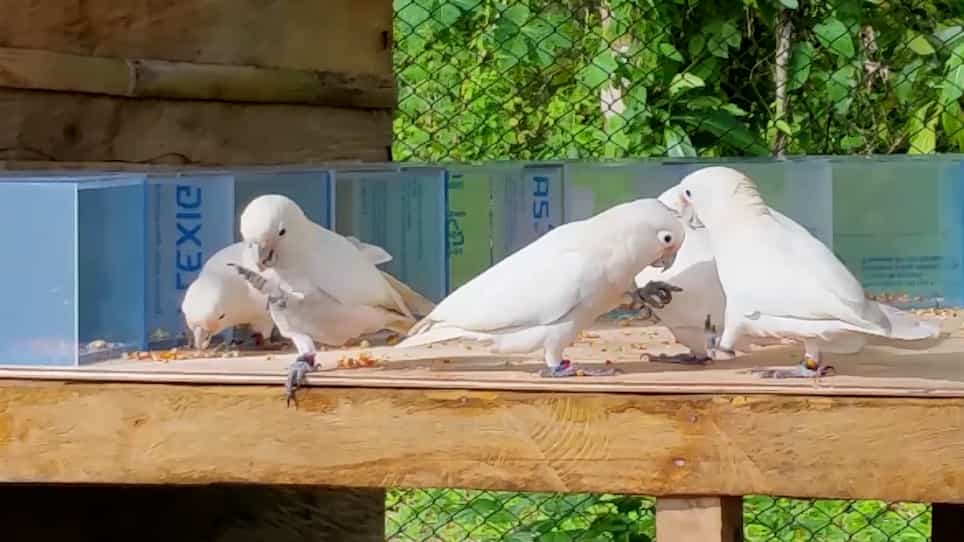
The Innovation Arena: A Method for Comparing Innovative Problem-Solving Across Groups
Published on: May 13, 2022
Shuai Chen1, Lu Tian2, Tianxi Cai3
1Department of Biostatistics and Medical Informatics, University of Wisconsin, Madison, Wisconsin 53792, U.S.A.

Abstract:
Many statistical methods have recently been developed for identifying subgroups of patients who may benefit from different available treatments. Compared with the traditional outcome-modeling approaches, these methods focus on modeling interactions between the treatments and covariates while by-pass or minimize modeling the main effects of covariates because the subgroup identification only depends on the sign of the interaction. However, these methods are scattered and often narrow in scope. In this article, we propose a general framework, by weighting and A-learning, for subgroup identification in both randomized clinical trials and observational studies. Our framework involves minimum modeling for the relationship between the outcome and covariates pertinent to the subgroup identification. Under the proposed framework, we may also estimate the magnitude of the interaction, which leads to the construction of scoring system measuring the individualized treatment effect. The proposed methods are quite flexible and include many recently proposed estimators as special cases. As a result, some estimators originally proposed for randomized clinical trials can be extended to observational studies, and procedures based on the weighting method can be converted to an A-learning method and vice versa. Our approaches also allow straightforward incorporation of regularization methods for high-dimensional data, as well as possible efficiency augmentation and generalization to multiple treatments. We examine the empirical performance of several procedures belonging to the proposed framework through extensive numerical studies.
More Related Videos
 06:55
Inverse Probability of Treatment Weighting Propensity Score using the Military Health System Data Repository and National Death Index
Published on: January 8, 2020
 08:27
Applying an eMASS Customization Program as a Research Tool to Evaluate Consumer Benefits
Published on: September 27, 2019
Related Concept Videos
 01:20
Comparing the Survival Analysis of Two or More Groups
 01:15
Study Design in Statistics
Does aspirin reduce the risk of heart attacks? Is one brand of fertilizer more effective at growing roses than another? Is fatigue as dangerous to a driver as the influence of alcohol? Questions like these are answered using randomized experiments with proper...
 01:23
Sampling Plans
Random sampling is a method where each member of the population has an equal chance of being selected for the sample. It involves selecting individuals randomly, often using random number generators or lottery-type methods. For example, when analyzing the properties of a...
 01:09
Statistical Methods to Analyze Parametric Data: Student t-Test and Goodness-of-Fit Test
The Student's t-test is a statistical test that examines if there is a statistically significant difference between the means of two groups. This test is instrumental when dealing with...
 01:23
Test for Homogeneity
 01:16
Stratified Sampling Method
To choose a stratified sample, divide the population into groups called strata and then take a...