A Survey on Learning to Hash
Related Experiment Video
Updated: Mar 3, 2026

The HoneyComb Paradigm for Research on Collective Human Behavior
Published on: January 19, 2019

Abstract:
Nearest neighbor search is a problem of finding the data points from the database such that the distances from them to the query point are the smallest. Learning to hash is one of the major solutions to this problem and has been widely studied recently. In this paper, we present a comprehensive survey of the learning to hash algorithms, categorize them according to the manners of preserving the similarities into: pairwise similarity preserving, multiwise similarity preserving, implicit similarity preserving, as well as quantization, and discuss their relations. We separate quantization from pairwise similarity preserving as the objective function is very different though quantization, as we show, can be derived from preserving the pairwise similarities. In addition, we present the evaluation protocols, and the general performance analysis, and point out that the quantization algorithms perform superiorly in terms of search accuracy, search time cost, and space cost. Finally, we introduce a few emerging topics.
Related Concept Videos
 01:28
Survey Safety
 02:16
Surveys
 01:27
Types of Surveys
 01:19
Errors and Mistakes in Surveying
 02:28
Leaky Scanning
 01:08
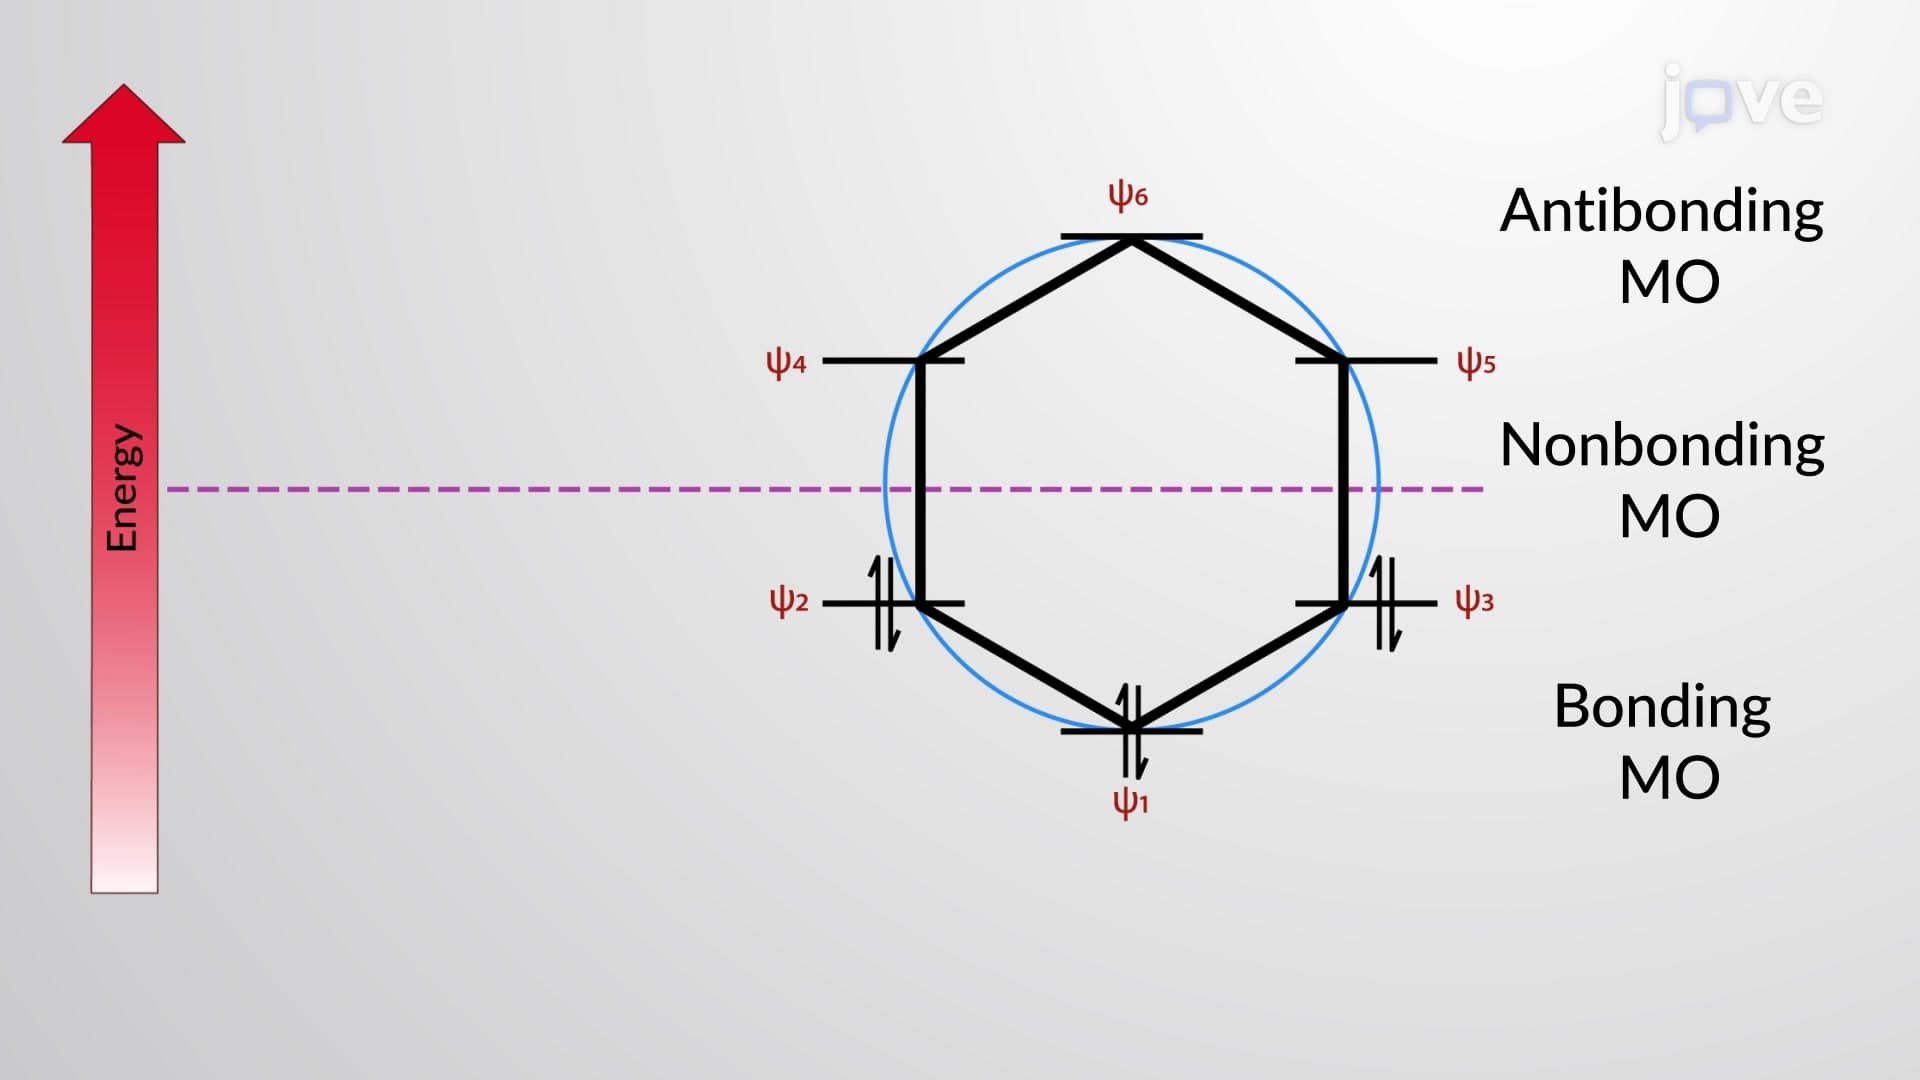
Hückel's Rule Diagram of π MOs: Frost Circle
A Frost circle is constructed by drawing a polygon whose number of edges is equal to the number of carbons of the given cyclic system, with one of the vertices pointing down. Then, a circle is drawn enclosing the polygon so that...