Related Experiment Video
Updated: Mar 1, 2026

Signal Acquisition, Score Interpretation, and Economics of a Non-Invasive Point-of-Care Test for Coronary Artery Disease
Published on: August 9, 2024
An Efficient Predictive Model for Myocardial Infarction Using Cost-sensitive J48 Model
Atefeh Daraei1, Hodjat Hamidi1
1Dept. of Information Technology, Faculty of Industrial Engineering, K.N. Toosi University of Technology, Tehran, Iran.

Insights
This study developed a reliable Myocardial Infarction (MI) prediction model. A cost-sensitive method with hybrid feature selection significantly improved prediction accuracy for this critical heart condition.
Area of Science:
- Medical Informatics
- Data Mining
- Cardiology
Background:
- Myocardial Infarction (MI) is a life-threatening condition with significant human and economic costs.
- Predicting MI is crucial for timely intervention and improved patient outcomes.
- Existing prediction models often struggle with the inherent imbalance in patient data.
Purpose of the Study:
- To develop and evaluate a novel data mining model for predicting Myocardial Infarction.
- To address the challenge of imbalanced datasets in MI prediction.
- To enhance the accuracy and reliability of MI prediction models.
Main Methods:
- A hybrid feature selection method combining Relief and Genetic Algorithm was employed.
- A cost-sensitive classifier (Metacost with J48) was utilized to handle misclassification costs.
- The model was trained and tested on a dataset of 750 patients (455 healthy, 295 MI cases).
Main Results:
- The optimal cost ratio of 1:200 yielded the best performance compared to models without feature selection or cost-sensitivity.
- The developed model achieved a sensitivity of 86.67%, F-measure of 80%, and accuracy of 82.67%.
- The integration of cost-sensitive learning and feature selection demonstrably improved prediction outcomes.
Conclusions:
- The proposed cost-sensitive prediction model, enhanced by hybrid feature selection, proves effective for Myocardial Infarction.
- This approach offers a reliable tool for predicting MI, particularly in imbalanced datasets.
- The findings support the clinical utility of advanced data mining techniques in cardiovascular disease prediction.
Background:
Myocardial infarction (MI) occurs due to heart muscle death that costs like human life, which is higher than the treatment costs. This study aimed to present an MI prediction model using classification data mining methods, which consider the imbalance nature of the problem.
Methods:
We enrolled 455 healthy and 295 myocardial infarction cases of visitors to Shahid Madani Specialized Hospital, Khorramabad, Iran, in 2015. Then, a hybrid feature selection method included Weight by Relief and Genetic algorithm applied on the dataset to select the best features. After selection of the features, the metacost classifier applied on the sampled dataset. Metacost made a cost sensitive J48 model by assigning different costs ratios for misclassified cases; include 1:10, 1:50, 1:100, 1:150 and 1:200.
Results:
After applying the model on the imbalanced dataset, the cost ratio 1:200 led to the best results in comparison to not using feature selection and cost sensitive model. The model achieved sensitivity, F-measure and accuracy of 86.67%, 80% and 82.67%, respectively.
Conclusion:
Experiments on the real dataset showed that using the cost-sensitive method along with the hybrid feature selection method improved model performance. Therefore, the model considered a reliable Myocardial Infarction prediction model.
More Related Videos
Related Concept Videos
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
 01:17
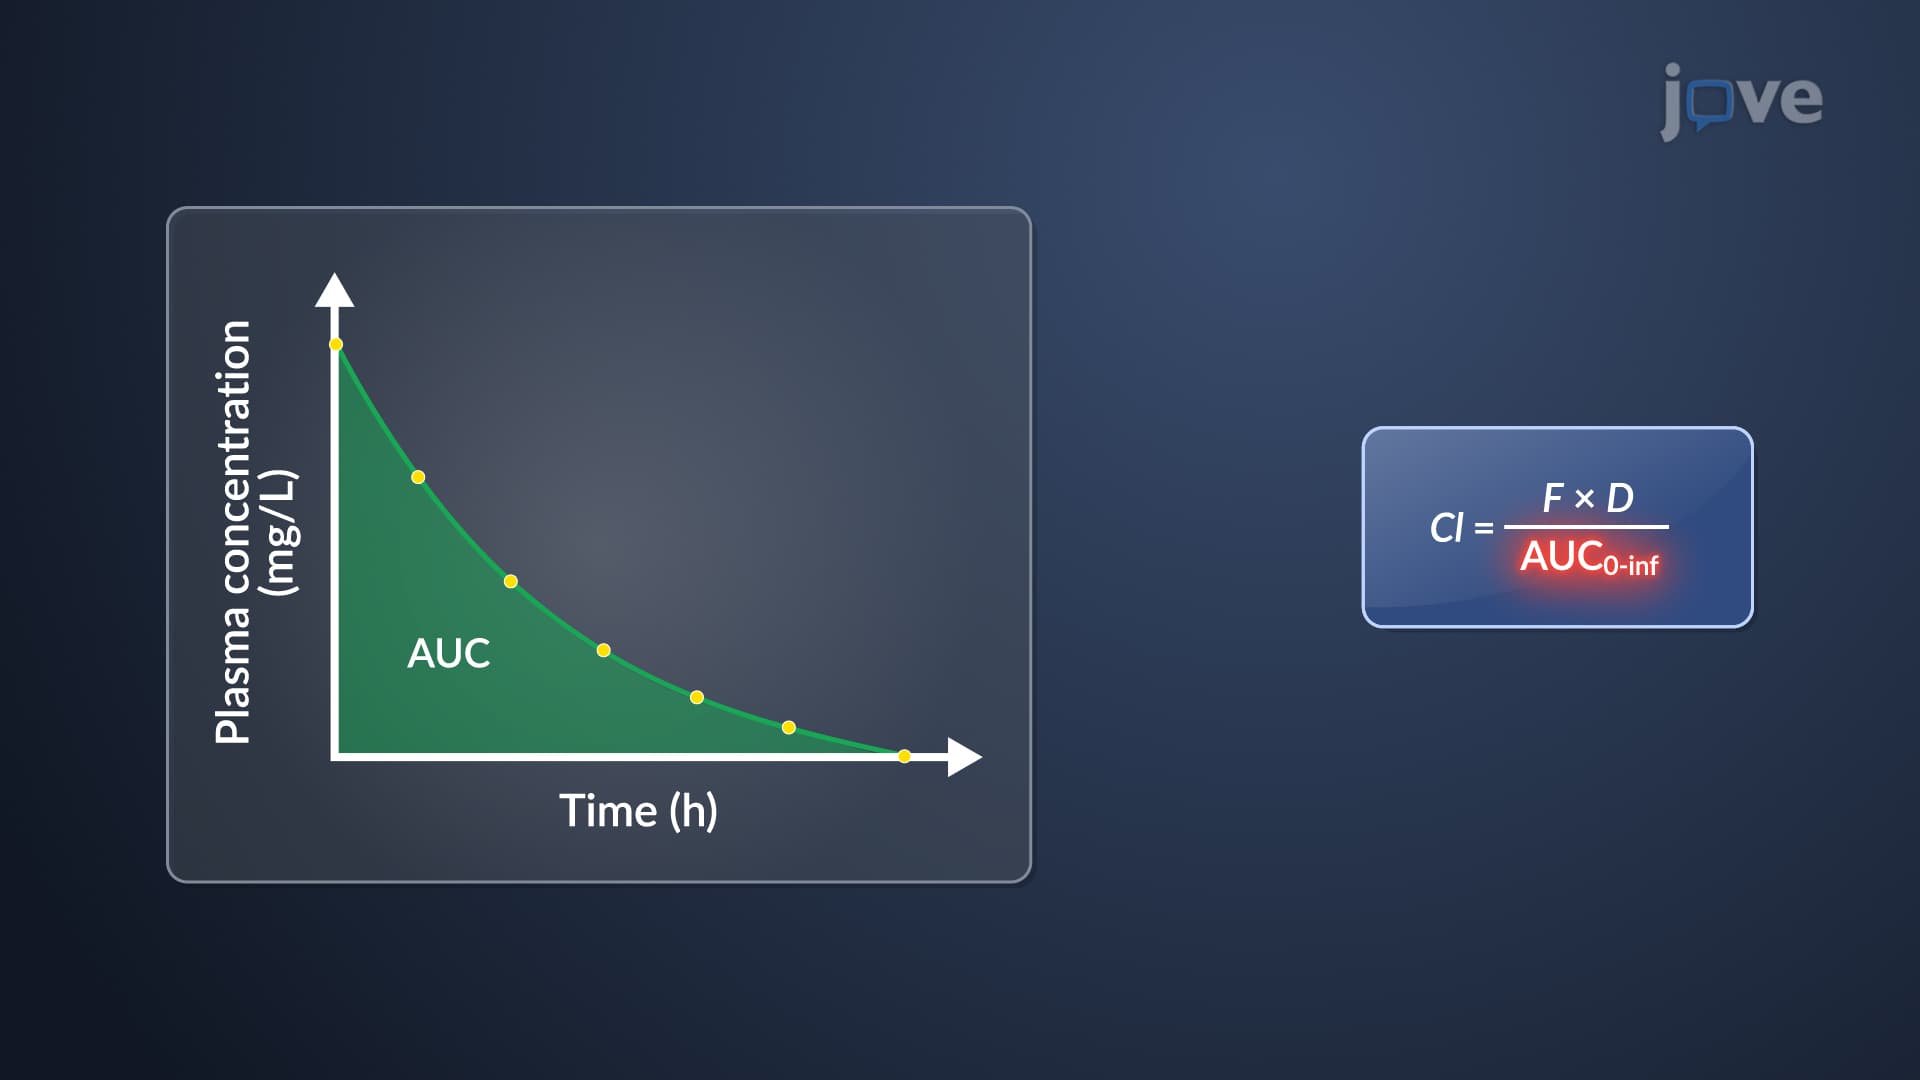
Clearance Models: Noncompartmental Models
The noncompartmental approach capitalizes on extensive sampling data, correlating the volume of distribution to systemic exposure and the administered dosage. This method enables...
 01:26
Pharmacokinetic Models: Comparison and Selection Criterion
Physiological models take a detailed approach by considering specific molecular processes. They can predict drug distribution, metabolism, and elimination changes, providing a comprehensive understanding of how drugs interact with the body.
 01:13
Sensitivity, Specificity, and Predicted Value
Sensitivity is the...