Related Experiment Video
Updated: Feb 22, 2026

Author Spotlight: Enhancement of Salient Object Detection for Smart Grid Applications
Published on: December 15, 2023
Video Salient Object Detection via Fully Convolutional Networks
Wenguan Wang1, Jianbing Shen1, Ling Shao2
1Beijing Laboratory of Intelligent Information Technology, School of Computer Science, Beijing Institute of Technology, Beijing, China.

Abstract:
This paper proposes a deep learning model to efficiently detect salient regions in videos. It addresses two important issues: 1) deep video saliency model training with the absence of sufficiently large and pixel-wise annotated video data and 2) fast video saliency training and detection. The proposed deep video saliency network consists of two modules, for capturing the spatial and temporal saliency information, respectively. The dynamic saliency model, explicitly incorporating saliency estimates from the static saliency model, directly produces spatiotemporal saliency inference without time-consuming optical flow computation. We further propose a novel data augmentation technique that simulates video training data from existing annotated image data sets, which enables our network to learn diverse saliency information and prevents overfitting with the limited number of training videos. Leveraging our synthetic video data (150K video sequences) and real videos, our deep video saliency model successfully learns both spatial and temporal saliency cues, thus producing accurate spatiotemporal saliency estimate. We advance the state-of-the-art on the densely annotated video segmentation data set (MAE of .06) and the Freiburg-Berkeley Motion Segmentation data set (MAE of .07), and do so with much improved speed (2 fps with all steps).This paper proposes a deep learning model to efficiently detect salient regions in videos. It addresses two important issues: 1) deep video saliency model training with the absence of sufficiently large and pixel-wise annotated video data and 2) fast video saliency training and detection. The proposed deep video saliency network consists of two modules, for capturing the spatial and temporal saliency information, respectively. The dynamic saliency model, explicitly incorporating saliency estimates from the static saliency model, directly produces spatiotemporal saliency inference without time-consuming optical flow computation. We further propose a novel data augmentation technique that simulates video training data from existing annotated image data sets, which enables our network to learn diverse saliency information and prevents overfitting with the limited number of training videos. Leveraging our synthetic video data (150K video sequences) and real videos, our deep video saliency model successfully learns both spatial and temporal saliency cues, thus producing accurate spatiotemporal saliency estimate. We advance the state-of-the-art on the densely annotated video segmentation data set (MAE of .06) and the Freiburg-Berkeley Motion Segmentation data set (MAE of .07), and do so with much improved speed (2 fps with all steps).
Related Concept Videos
 01:22
Force Classification
Contact and non-contact forces are two of the most widely used categories of forces. As the name suggests, contact forces require physical contact between two objects to act upon each other. Examples of contact forces include frictional,...
 01:20
Deconvolution
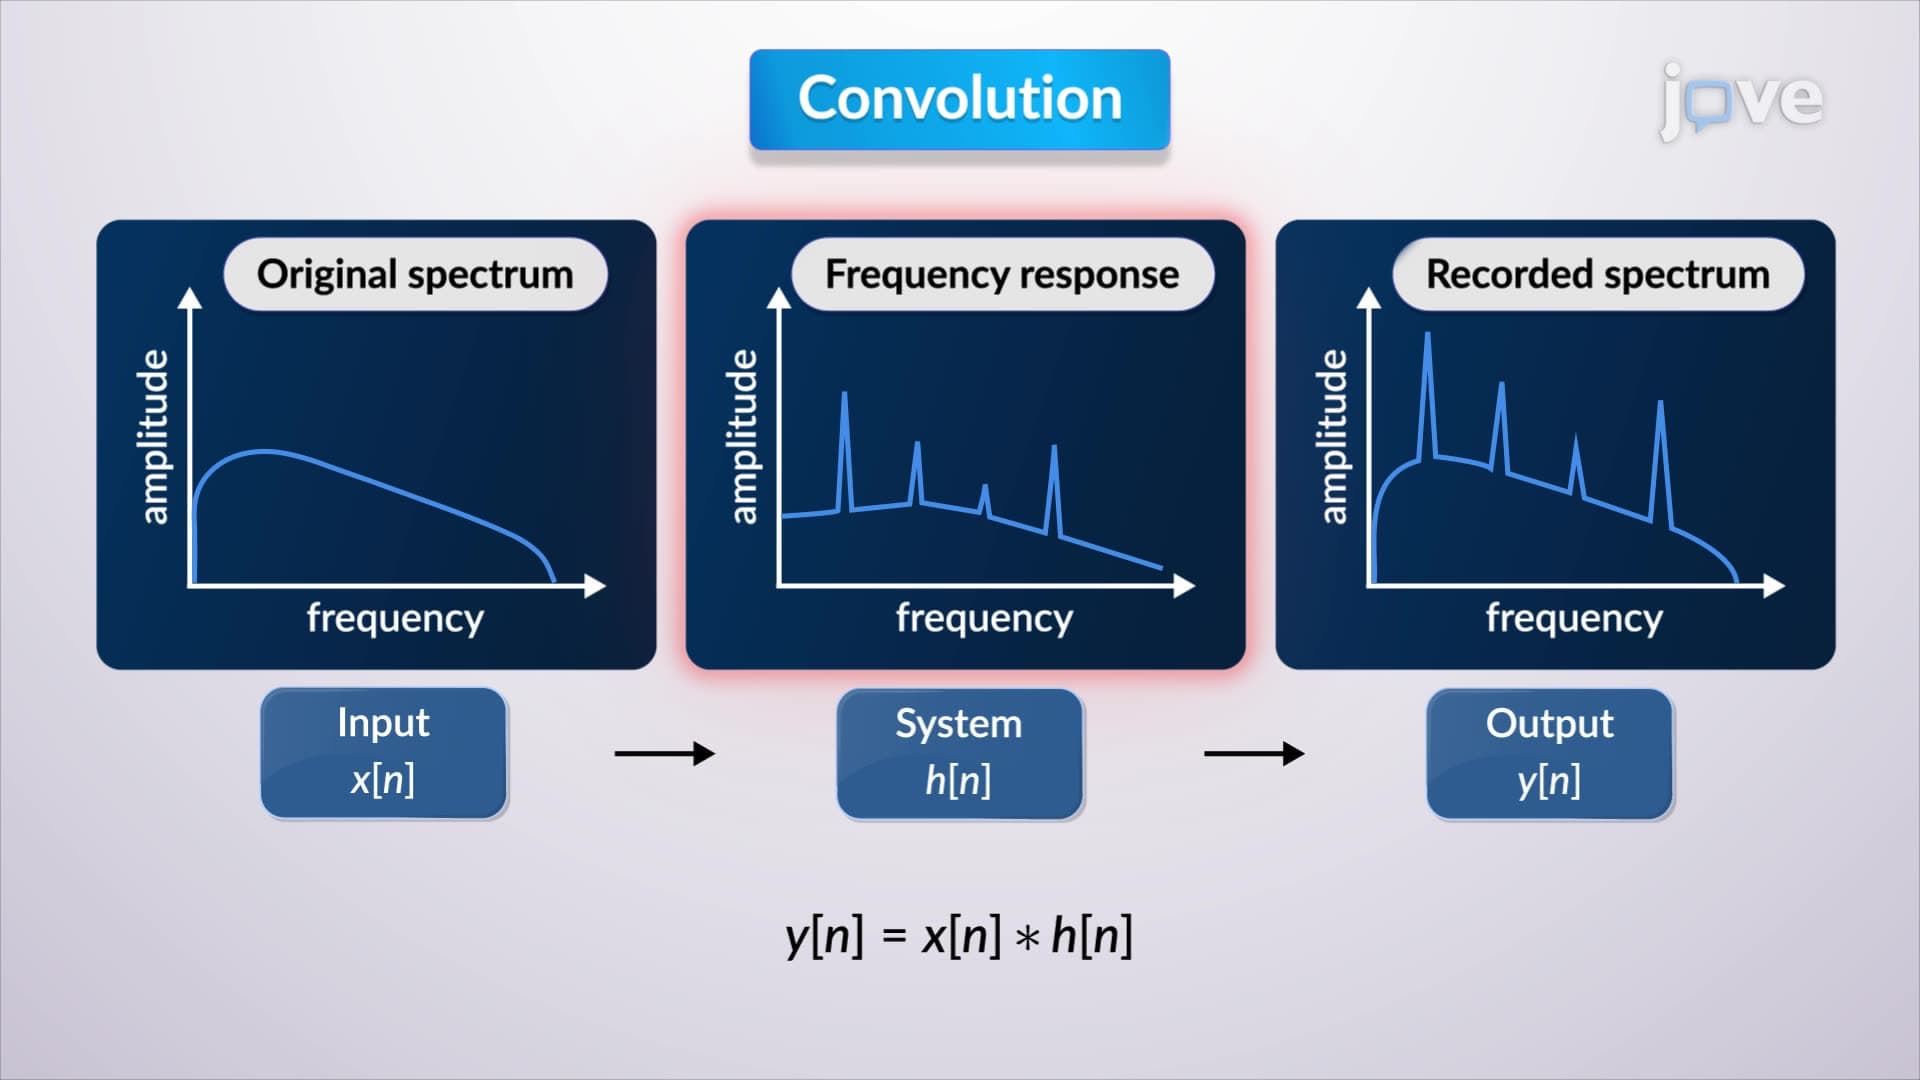
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
 01:05
Difference from Background: Limit of Detection
The LOD indicates the presence or absence...
 01:17
Convolution Properties II
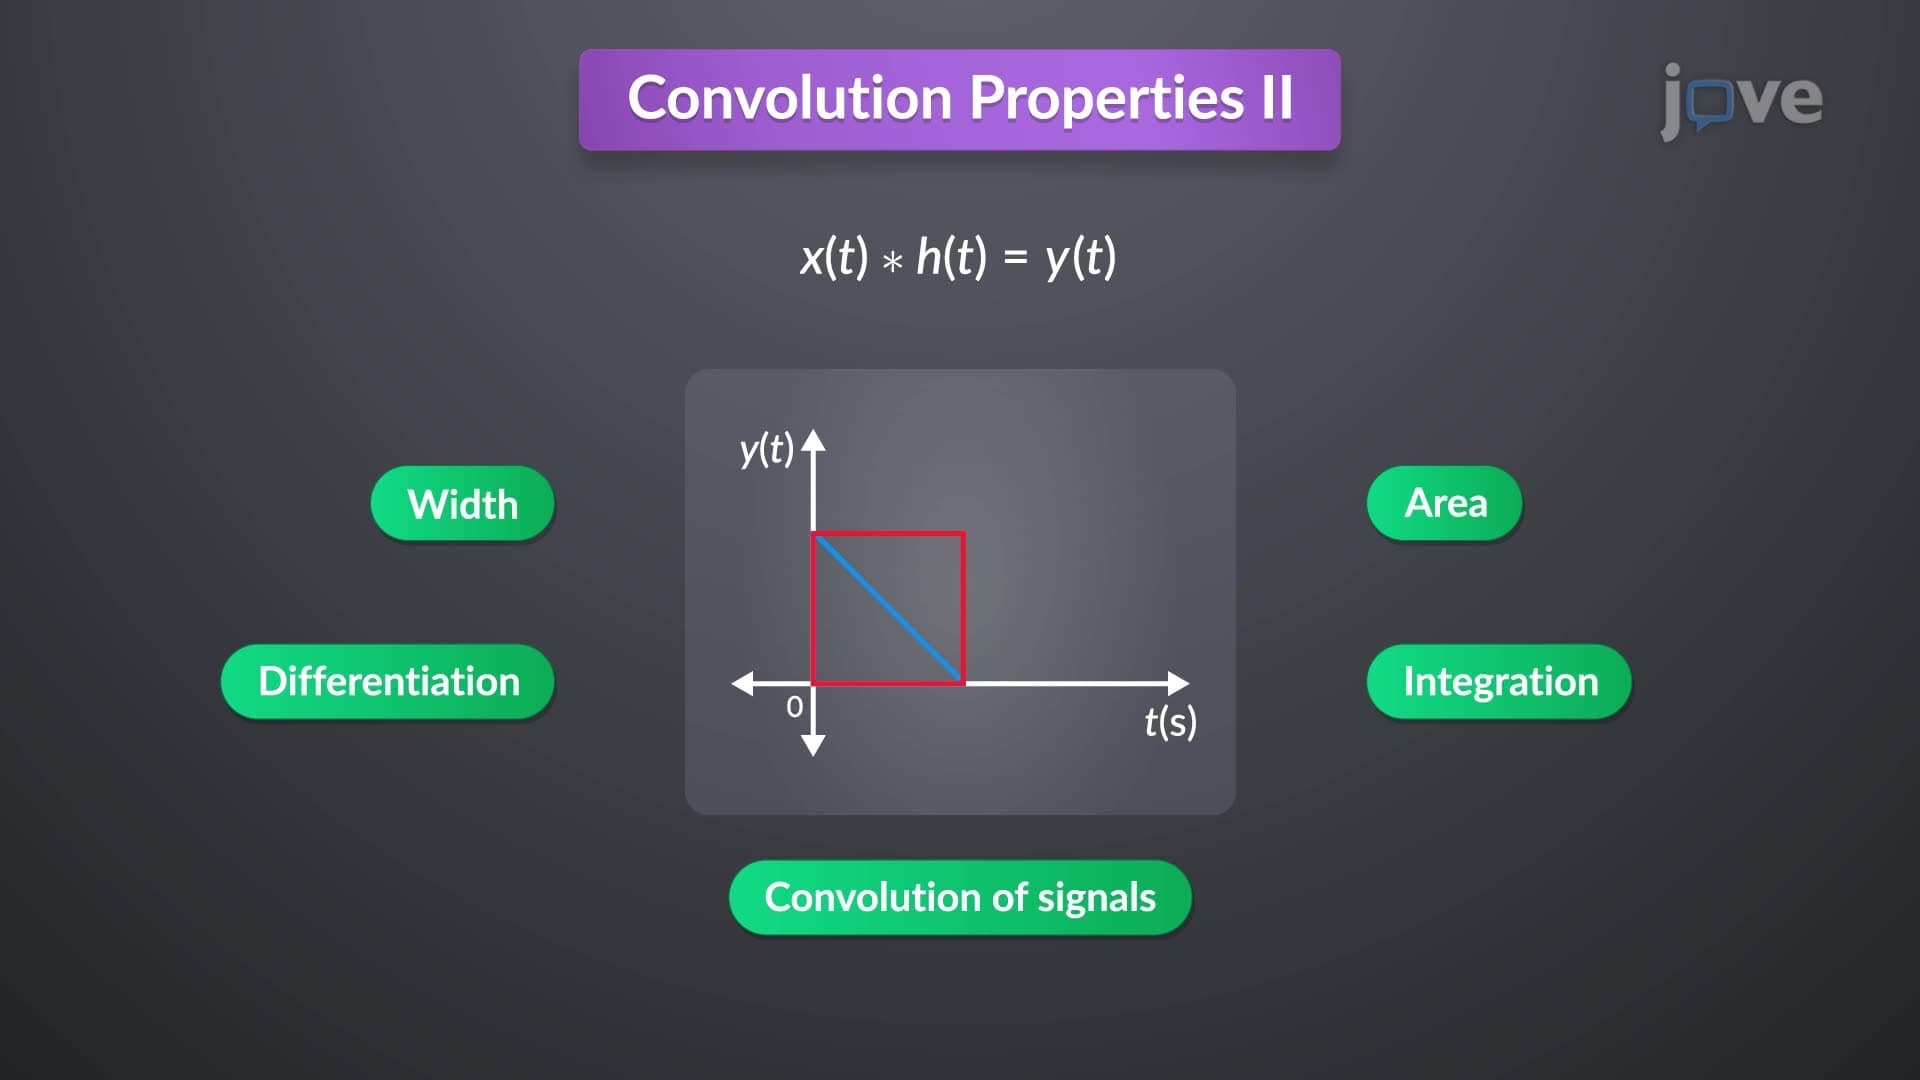
The width property indicates that if the durations of input signals are T1 and T2, then the width of the output response equals the sum of both durations, irrespective of the shapes of the two functions. For instance, convolving two rectangular pulses with durations of 2 seconds and 1 second results in a function with a width of 3 seconds.
The area property asserts that the area under the...
 01:24
Convolution: Math, Graphics, and Discrete Signals
To simplify the convolution integral, it is assumed that both the input signal and impulse response are zero for negative time values. The graphical convolution process...