Related Experiment Video
Updated: Feb 22, 2026
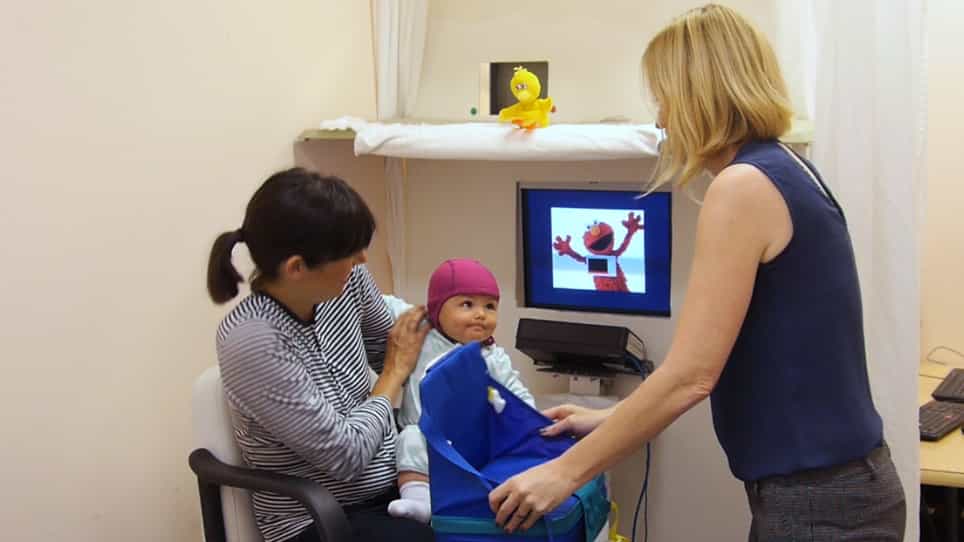

Exploring Infant Sensitivity to Visual Language using Eye Tracking and the Preferential Looking Paradigm
Published on: May 15, 2019
Sample size, statistical power, and false conclusions in infant looking-time research
1UC Davis.

Insights
Infant research often uses small sample sizes, leading to unreliable results. This study shows that small samples in infant looking time studies increase false positives and negatives, impacting research conclusions.
Area of Science:
- Developmental Psychology
- Cognitive Science
- Infant Research Methodologies
Background:
- Infant research, particularly using looking time measures, is characterized by small sample sizes due to recruitment and logistical challenges.
- Many published infant looking time studies utilize fewer than 24 infants per condition, raising concerns about statistical power.
Purpose of the Study:
- To investigate the impact of small sample sizes on statistical power and research outcomes in infant looking time studies.
- To evaluate the reliability of conclusions drawn from studies with limited participant numbers.
Main Methods:
- Analysis of three large infant datasets (>30 infants per condition).
- Simulation of 1000 subsamples with sizes ranging from 8 to 24 infants.
- Systematic examination of how varying sample sizes affect statistical results and conclusion validity.
Main Results:
- Studies with small sample sizes (8-24 infants) demonstrated high variability in outcomes, even when original large samples yielded clear results.
- Simulated small samples frequently produced both false positive and false negative findings.
- Low statistical power in typical infant looking time studies contributes to unreliable research findings.
Conclusions:
- Current small sample sizes in infant looking time research compromise study power and lead to erroneous conclusions.
- The variability introduced by small samples necessitates a re-evaluation of published findings and research practices.
- Exploring emerging solutions is crucial to enhance the reliability and validity of infant research.
Abstract:
Infant research is hard. It is difficult, expensive, and time consuming to identify, recruit and test infants. As a result, ours is a field of small sample sizes. Many studies using infant looking time as a measure have samples of 8 to 12 infants per cell, and studies with more than 24 infants per cell are uncommon. This paper examines the effect of such sample sizes on statistical power and the conclusions drawn from infant looking time research. An examination of the state of the current literature suggests that most published looking time studies have low power, which leads in the long run to an increase in both false positive and false negative results. Three data sets with large samples (>30 infants) were used to simulate experiments with smaller sample sizes; 1000 random subsamples of 8, 12, 16, 20, and 24 infants from the overall samples were selected, making it possible to examine the systematic effect of sample size on the results. This approach revealed that despite clear results with the original large samples, the results with smaller subsamples were highly variable, yielding both false positive and false negative outcomes. Finally, a number of emerging possible solutions are discussed.
Related Concept Videos
 01:50
Statistical Significance
 01:14
Errors In Hypothesis Tests
 01:13
Accuracy and Errors in Hypothesis Testing
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5%...
 01:52
Regression Toward the Mean