Related Experiment Video
Updated: Feb 16, 2026
Collecting and Processing Drone-based Remotely Sensed Data for Use in Forest Recovery Monitoring
Published on: October 24, 2025
Improved high-dimensional prediction with Random Forests by the use of co-data
Dennis E Te Beest1, Steven W Mes2, Saskia M Wilting3
1Department of Epidemiology and Biostatistics, VU University Medical Center, Amsterdam, 1007 MB, The Netherlands.

Background:
Prediction in high dimensional settings is difficult due to the large number of variables relative to the sample size. We demonstrate how auxiliary 'co-data' can be used to improve the performance of a Random Forest in such a setting.
Results:
Co-data are incorporated in the Random Forest by replacing the uniform sampling probabilities that are used to draw candidate variables by co-data moderated sampling probabilities. Co-data here are defined as any type information that is available on the variables of the primary data, but does not use its response labels. These moderated sampling probabilities are, inspired by empirical Bayes, learned from the data at hand. We demonstrate the co-data moderated Random Forest (CoRF) with two examples. In the first example we aim to predict the presence of a lymph node metastasis with gene expression data. We demonstrate how a set of external p-values, a gene signature, and the correlation between gene expression and DNA copy number can improve the predictive performance. In the second example we demonstrate how the prediction of cervical (pre-)cancer with methylation data can be improved by including the location of the probe relative to the known CpG islands, the number of CpG sites targeted by a probe, and a set of p-values from a related study.
Conclusion:
The proposed method is able to utilize auxiliary co-data to improve the performance of a Random Forest.
Related Concept Videos
 02:27
Predicting Molecular Geometry
 01:04
Random Error
 01:09
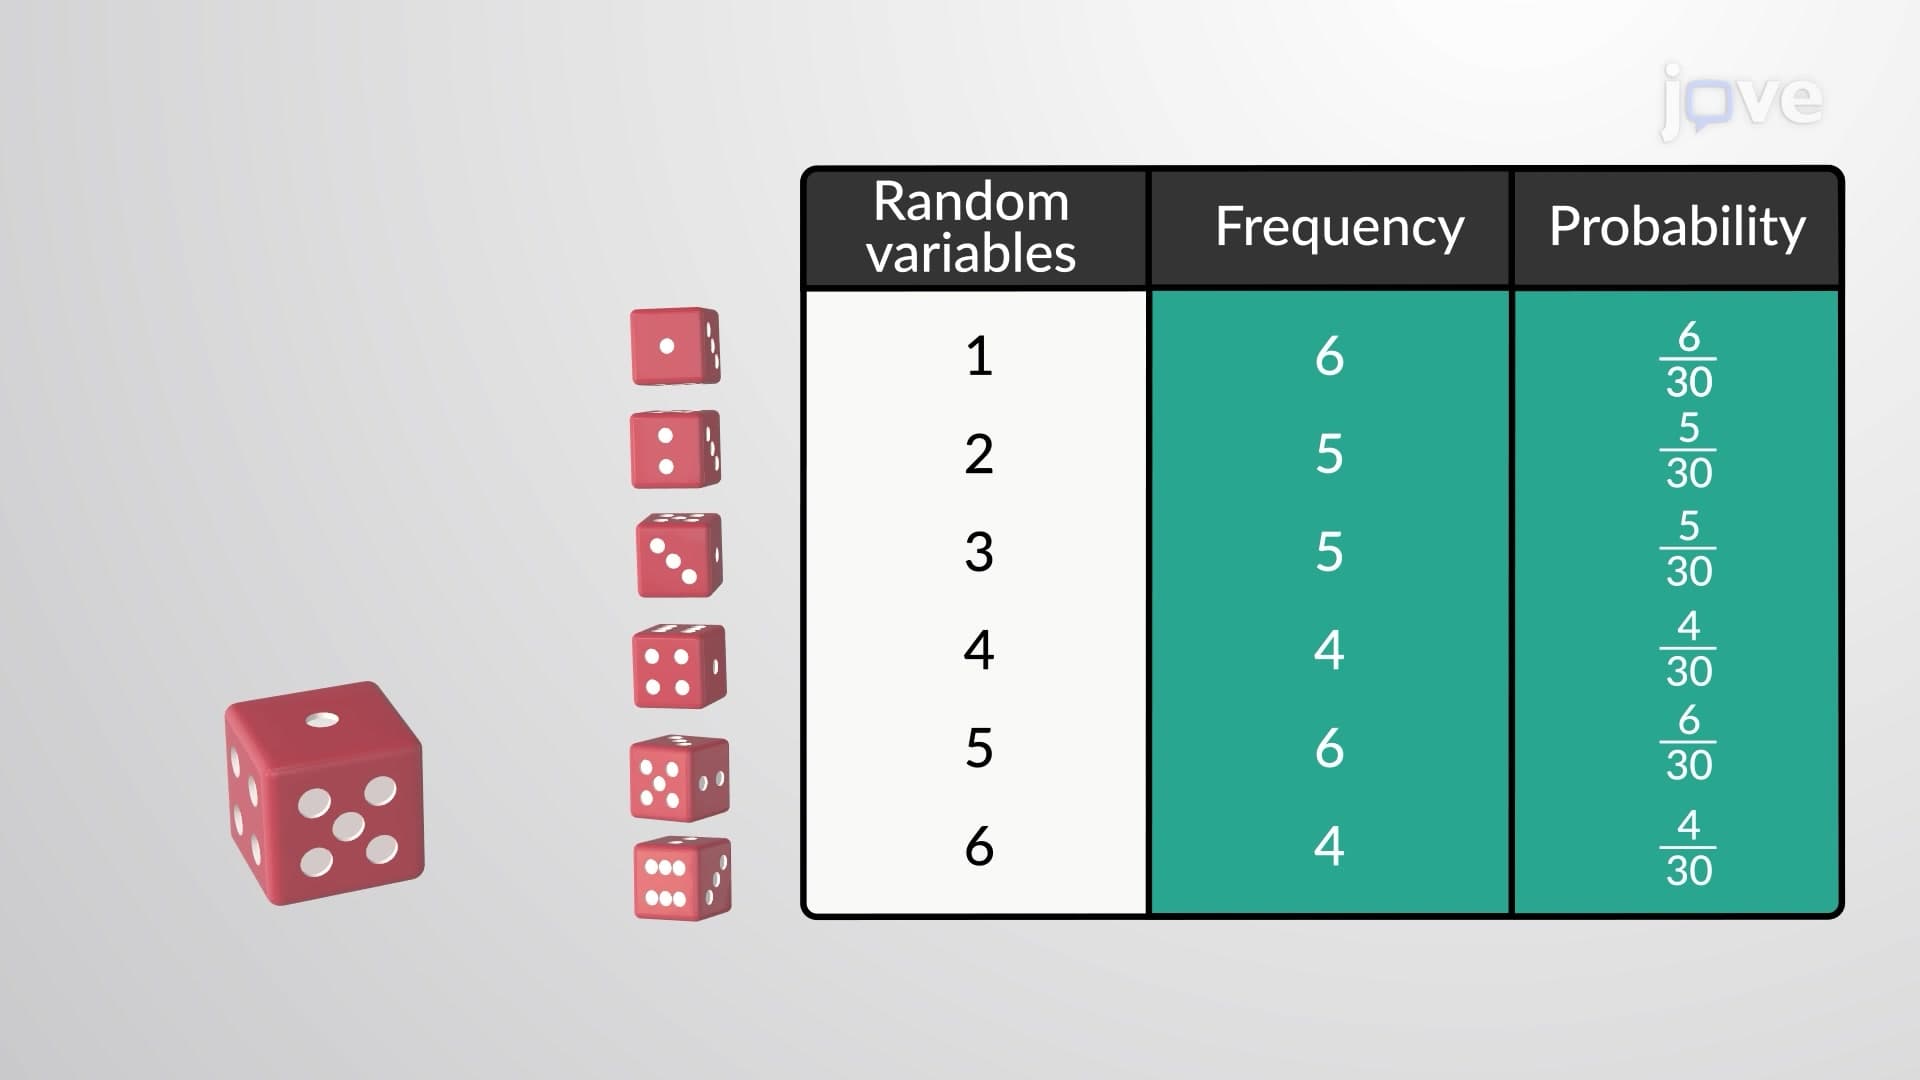
Random Variables
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
 01:13
Randomized Experiments
Simple randomization
Simple...
 01:20
Random and Systematic Errors
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.