Related Experiment Video
Updated: Feb 16, 2026

A Practical Guide to Phylogenetics for Nonexperts
Published on: February 5, 2014
Variable selection - A review and recommendations for the practicing statistician
Georg Heinze1, Christine Wallisch1, Daniela Dunkler1
1Section for Clinical Biometrics, Center for Medical Statistics, Informatics and Intelligent Systems, Medical University of Vienna, Vienna, 1090, Austria.

Abstract:
Statistical models support medical research by facilitating individualized outcome prognostication conditional on independent variables or by estimating effects of risk factors adjusted for covariates. Theory of statistical models is well-established if the set of independent variables to consider is fixed and small. Hence, we can assume that effect estimates are unbiased and the usual methods for confidence interval estimation are valid. In routine work, however, it is not known a priori which covariates should be included in a model, and often we are confronted with the number of candidate variables in the range 10-30. This number is often too large to be considered in a statistical model. We provide an overview of various available variable selection methods that are based on significance or information criteria, penalized likelihood, the change-in-estimate criterion, background knowledge, or combinations thereof. These methods were usually developed in the context of a linear regression model and then transferred to more generalized linear models or models for censored survival data. Variable selection, in particular if used in explanatory modeling where effect estimates are of central interest, can compromise stability of a final model, unbiasedness of regression coefficients, and validity of p-values or confidence intervals. Therefore, we give pragmatic recommendations for the practicing statistician on application of variable selection methods in general (low-dimensional) modeling problems and on performing stability investigations and inference. We also propose some quantities based on resampling the entire variable selection process to be routinely reported by software packages offering automated variable selection algorithms.
More Related Videos
 11:53
Spatial Multiobjective Optimization of Agricultural Conservation Practices using a SWAT Model and an Evolutionary Algorithm
Published on: December 9, 2012
 12:18
A Machine Learning Approach to Design an Efficient Selective Screening of Mild Cognitive Impairment
Published on: January 11, 2020
Related Concept Videos
 01:10
Review and Preview
Percentiles are a type of fractile that partition data into...
 01:13
Review and Preview
 01:11
Variability: Analysis
The range is a simple measure of variability, indicating the difference between the highest and...
 01:09
Random Variables
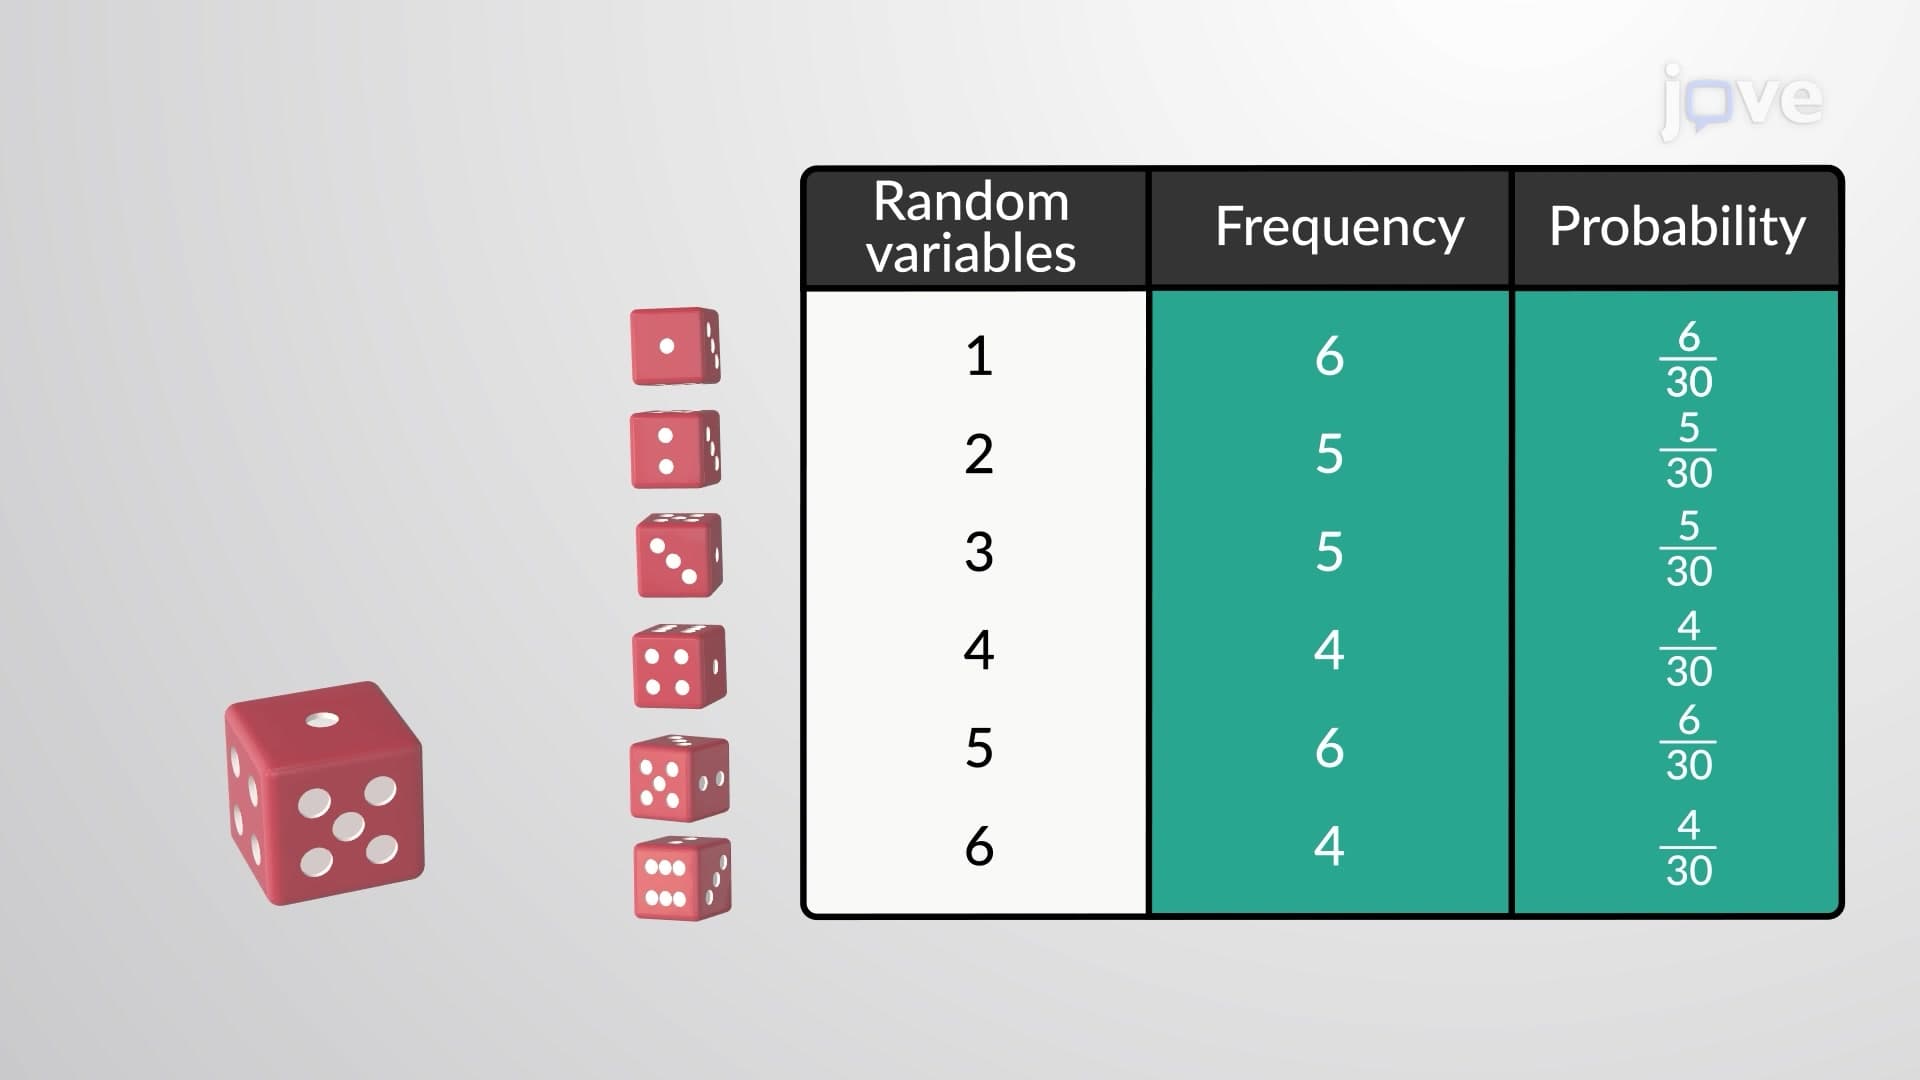
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
 01:30
Graphs of Equations in Two Variables
 01:26
Variables Affecting Phosphorescence and Fluorescence