Related Experiment Video
Updated: Feb 15, 2026
Spotting Cheetahs: Identifying Individuals by Their Footprints
Published on: May 1, 2016
Leveraging Linkage of Cohort Studies With Administrative Claims Data to Identify Individuals With Cancer
Mackenzie R Bronson1, Nirav S Kapadia1,2, Andrea M Austin1
1The Dartmouth Institute for Health Policy and Clinical Practice.

Background:
In an effort to overcome quality and cost constraints inherent in population-based research, diverse data sources are increasingly being combined. In this paper, we describe the performance of a Medicare claims-based incident cancer identification algorithm in comparison with observational cohort data from the Nurses' Health Study (NHS).
Methods:
NHS-Medicare linked participants' claims data were analyzed using 4 versions of a cancer identification algorithm across 3 cancer sites (breast, colorectal, and lung). The algorithms evaluated included an update of the original Setoguchi algorithm, and 3 other versions that differed in the data used for prevalent cancer exclusions.
Results:
The algorithm that yielded the highest positive predictive value (PPV) (0.52-0.82) and κ statistic (0.62-0.87) in identifying incident cancer cases utilized both Medicare claims and observational cohort data (NHS) to remove prevalent cases. The algorithm that only used NHS data to inform the removal of prevalent cancer cases performed nearly equivalently in statistical performance (PPV, 0.50-0.79; κ, 0.61-0.85), whereas the version that used only claims to inform the removal of prevalent cancer cases performed substantially worse (PPV, 0.42-0.60; κ, 0.54-0.70), in comparison with the dual data source-informed algorithm.
Conclusions:
Our findings suggest claims-based algorithms identify incident cancer with variable reliability when measured against an observational cohort study reference standard. Self-reported baseline information available in cohort studies is more effective in removing prevalent cancer cases than are claims data algorithms. Use of claims-based algorithms should be tailored to the research question at hand and the nature of available observational cohort data.
Related Concept Videos
 01:01
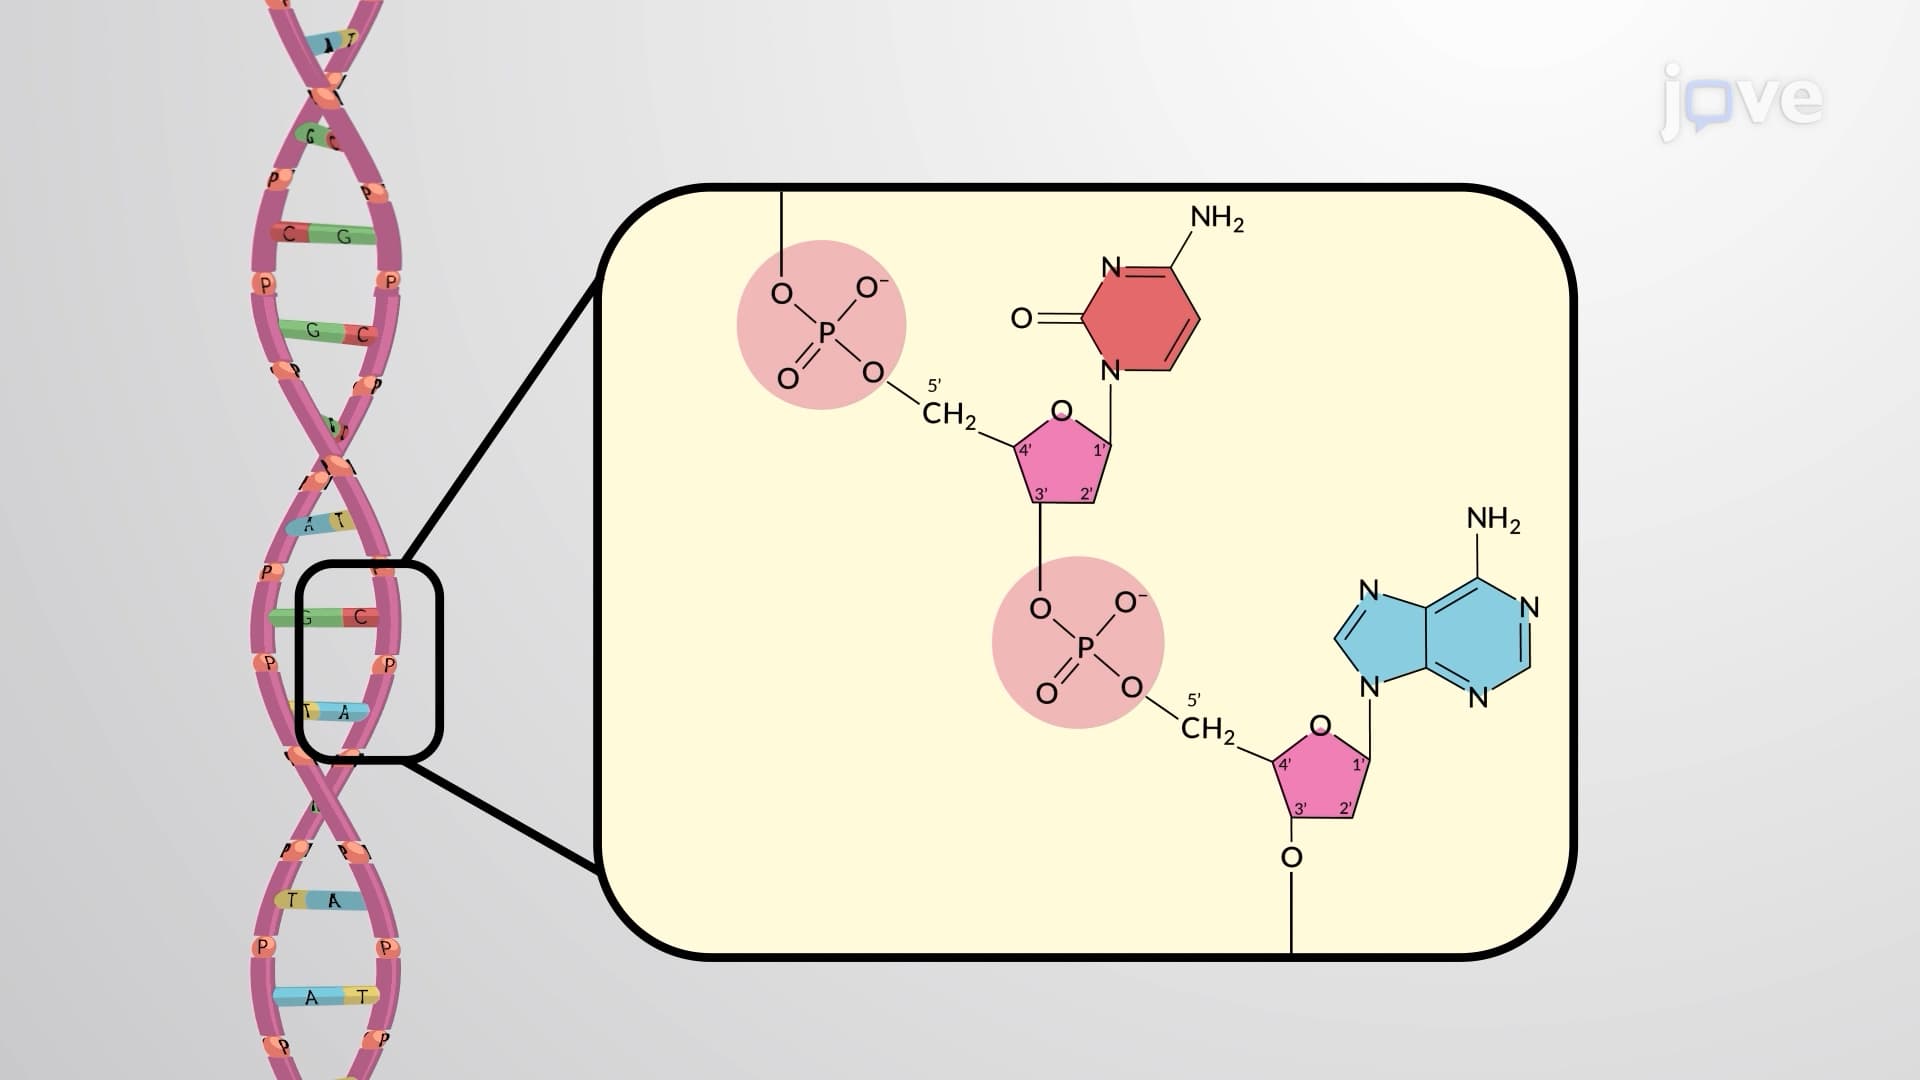
Phosphodiester Linkages
Phosphodiester bond forms when a phosphoric acid molecule (H3PO4) links with two hydroxyl groups (–OH) of two other molecules, forming two ester bonds. Two water molecules are released in this process. The phosphodiester bond is commonly found in nucleic acids (DNA and RNA) and plays a critical role in their structure and function.
Phosphodiester Bonds Link Nucleotides Together
DNA and RNA are polynucleotides or long chains of nucleotides that are linked together. A nucleotide is...
 00:49
Ligand Binding and Linkage
00:49Ligand Binding and Linkage
 01:11
Testing a Claim about Mean: Known Population SD
Estimating a population mean requires the samples to be distributed normally. The data should be collected from the randomly selected samples having no sampling bias. The sample size needed to be higher than 30, and most importantly, the population standard deviation should be already known.
In most realistic situations, the population standard deviation is often unknown, but in rare circumstances, when it...
 01:24
Testing a Claim about Population Proportion
There are two methods of testing a claim about a population proportion: (1) Using the sample proportion from the data where a binomial distribution is approximated to the normal distribution and (2) Using the binomial probabilities calculated from the data.
The first method uses normal distribution as an approximation to the binomial distribution. The requirements are as follows: sample size is large...
 01:19
Testing a Claim about Standard Deviation
The hypothesis testing for the claim of population standard deviation (or variance) requires the data and samples to be random and unbiased. The population distribution also must be normal. There is no specific requirement on the sample size as the estimation is based on the chi-square distribution.
As a first step, the hypothesis (null and alternative) concerning the claim about...