Related Experiment Video
Updated: Feb 13, 2026
Mass Spectrometry-Guided Genome Mining as a Tool to Uncover Novel Natural Products
Published on: March 12, 2020
Natural language processing in text mining for structural modeling of protein complexes
Varsha D Badal1, Petras J Kundrotas2, Ilya A Vakser3
1Center for Computational Biology and Department of Molecular Biosciences, The University of Kansas, Lawrence, Kansas, 66047, USA.

Background:
Structural modeling of protein-protein interactions produces a large number of putative configurations of the protein complexes. Identification of the near-native models among them is a serious challenge. Publicly available results of biomedical research may provide constraints on the binding mode, which can be essential for the docking. Our text-mining (TM) tool, which extracts binding site residues from the PubMed abstracts, was successfully applied to protein docking (Badal et al., PLoS Comput Biol, 2015; 11: e1004630). Still, many extracted residues were not relevant to the docking.
Results:
We present an extension of the TM tool, which utilizes natural language processing (NLP) for analyzing the context of the residue occurrence. The procedure was tested using generic and specialized dictionaries. The results showed that the keyword dictionaries designed for identification of protein interactions are not adequate for the TM prediction of the binding mode. However, our dictionary designed to distinguish keywords relevant to the protein binding sites led to considerable improvement in the TM performance. We investigated the utility of several methods of context analysis, based on dissection of the sentence parse trees. The machine learning-based NLP filtered the pool of the mined residues significantly more efficiently than the rule-based NLP. Constraints generated by NLP were tested in docking of unbound proteins from the DOCKGROUND X-ray benchmark set 4. The output of the global low-resolution docking scan was post-processed, separately, by constraints from the basic TM, constraints re-ranked by NLP, and the reference constraints. The quality of a match was assessed by the interface root-mean-square deviation. The results showed significant improvement of the docking output when using the constraints generated by the advanced TM with NLP.
Conclusions:
The basic TM procedure for extracting protein-protein binding site residues from the PubMed abstracts was significantly advanced by the deep parsing (NLP techniques for contextual analysis) in purging of the initial pool of the extracted residues. Benchmarking showed a substantial increase of the docking success rate based on the constraints generated by the advanced TM with NLP.
More Related Videos
Related Concept Videos
 01:57
Protein Complexes with Interchangeable Parts
The SCF ubiquitin ligase is a protein complex of five individual proteins. This complex attaches ubiquitin to other target proteins to mark them for degradation. In order...
01:57Protein Complexes with Interchangeable Parts
 02:15
Protein and Protein Structure
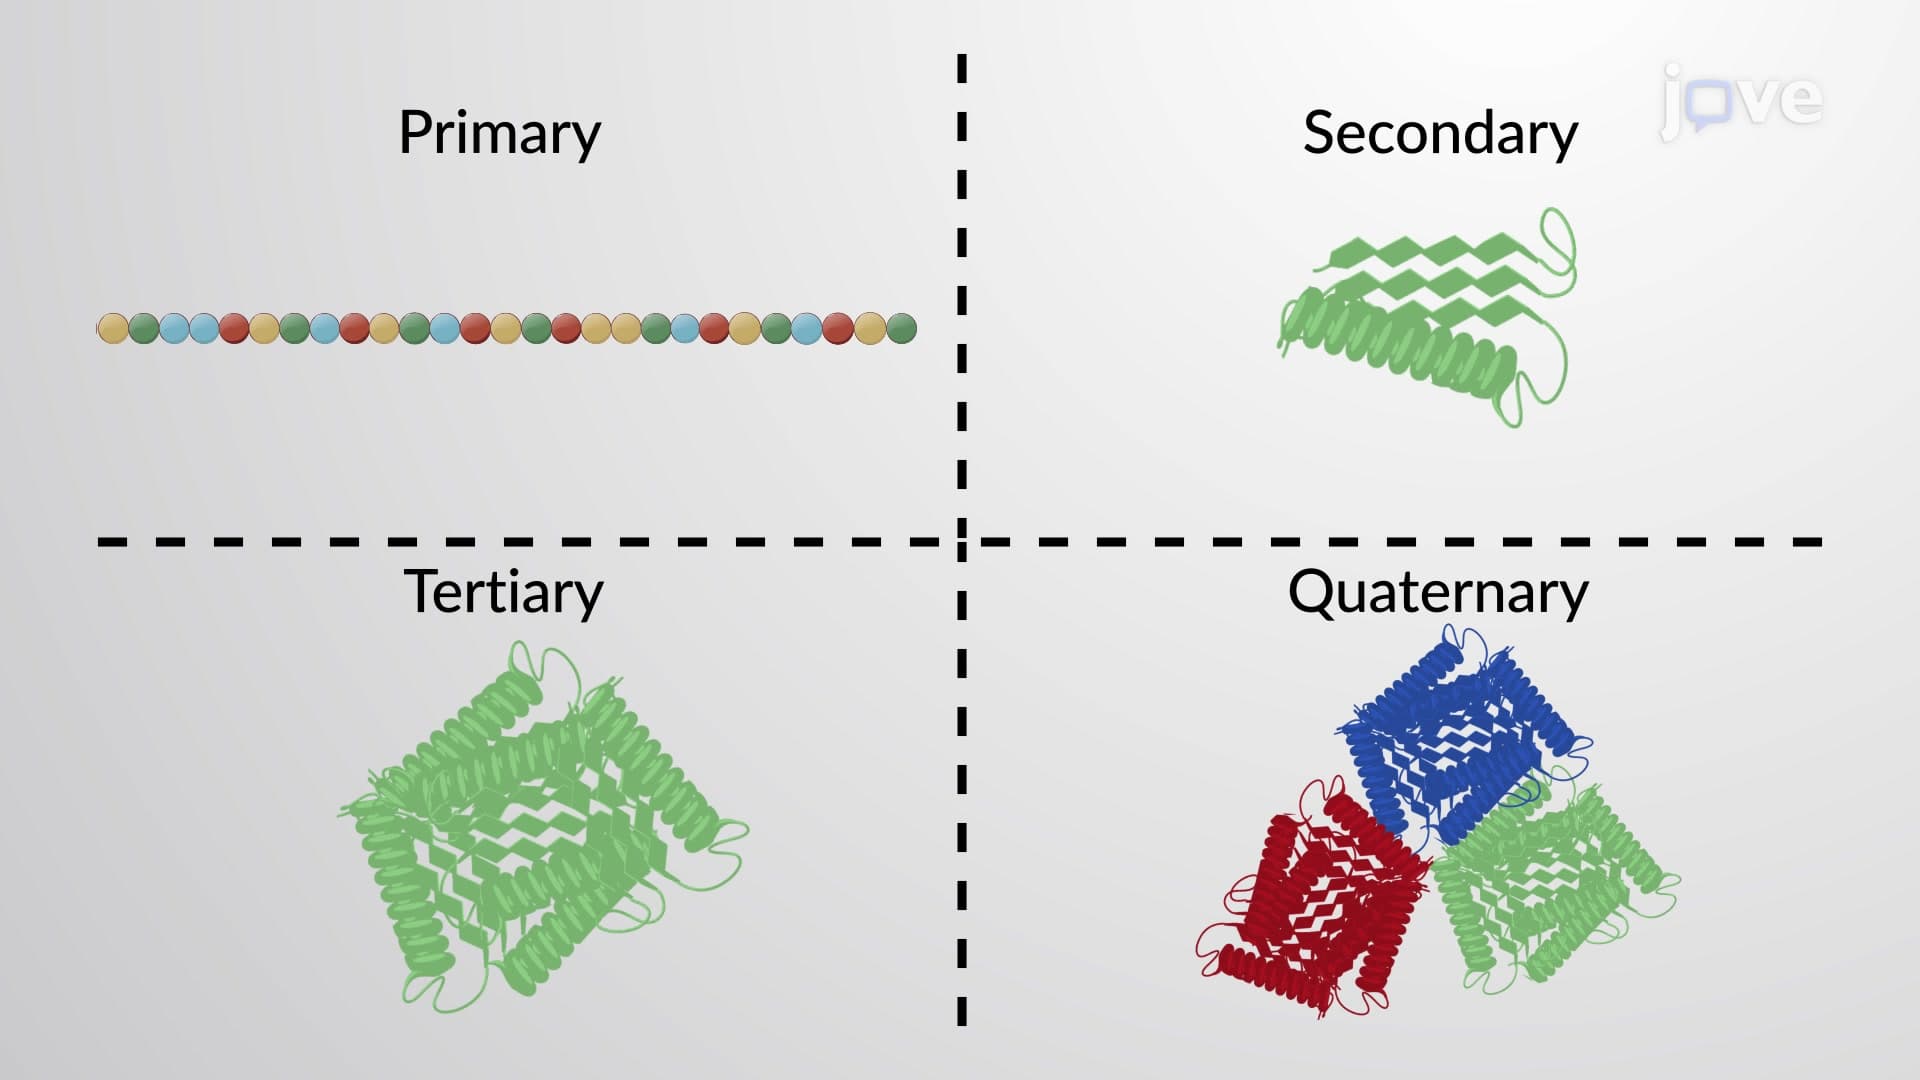
A protein's shape is critical to its function. For example, an enzyme...
 02:41
Protein Complex Assembly
Many viruses self-assemble into a fully functional unit using the infected host cell to...
02:41Protein Complex Assembly
 02:41
Chromatin Structure Regulates pre-mRNA Processing
The chromatin structure, especially...