Related Experiment Video
Updated: Feb 12, 2026

An Ultrahigh-throughput Microfluidic Platform for Single-cell Genome Sequencing
Published on: May 23, 2018
Linkage Disequilibrium Estimation in Low Coverage High-Throughput Sequencing Data
Timothy P Bilton1, John C McEwan2, Shannon M Clarke2
1AgResearch, Invermay Agricultural Centre, Mosgiel 9053, New Zealand timothy.bilton@agresearch.co.nz.

Abstract:
High-throughput sequencing methods that multiplex a large number of individuals have provided a cost-effective approach for discovering genome-wide genetic variation in large populations. These sequencing methods are increasingly being utilized in population genetic studies across a diverse range of species. Two side-effects of these methods, however, are (1) sequencing errors and (2) heterozygous genotypes called as homozygous due to only one allele at a particular locus being sequenced, which occurs when the sequencing depth is insufficient. Both of these errors have a profound effect on the estimation of linkage disequilibrium (LD) and, if not taken into account, lead to inaccurate estimates. We developed a new likelihood method, GUS-LD, to estimate pairwise linkage disequilibrium using low coverage sequencing data that accounts for undercalled heterozygous genotypes and sequencing errors. Our findings show that accurate estimates were obtained using GUS-LD, whereas underestimation of LD results if no adjustment is made for the errors.
Related Concept Videos
 01:01
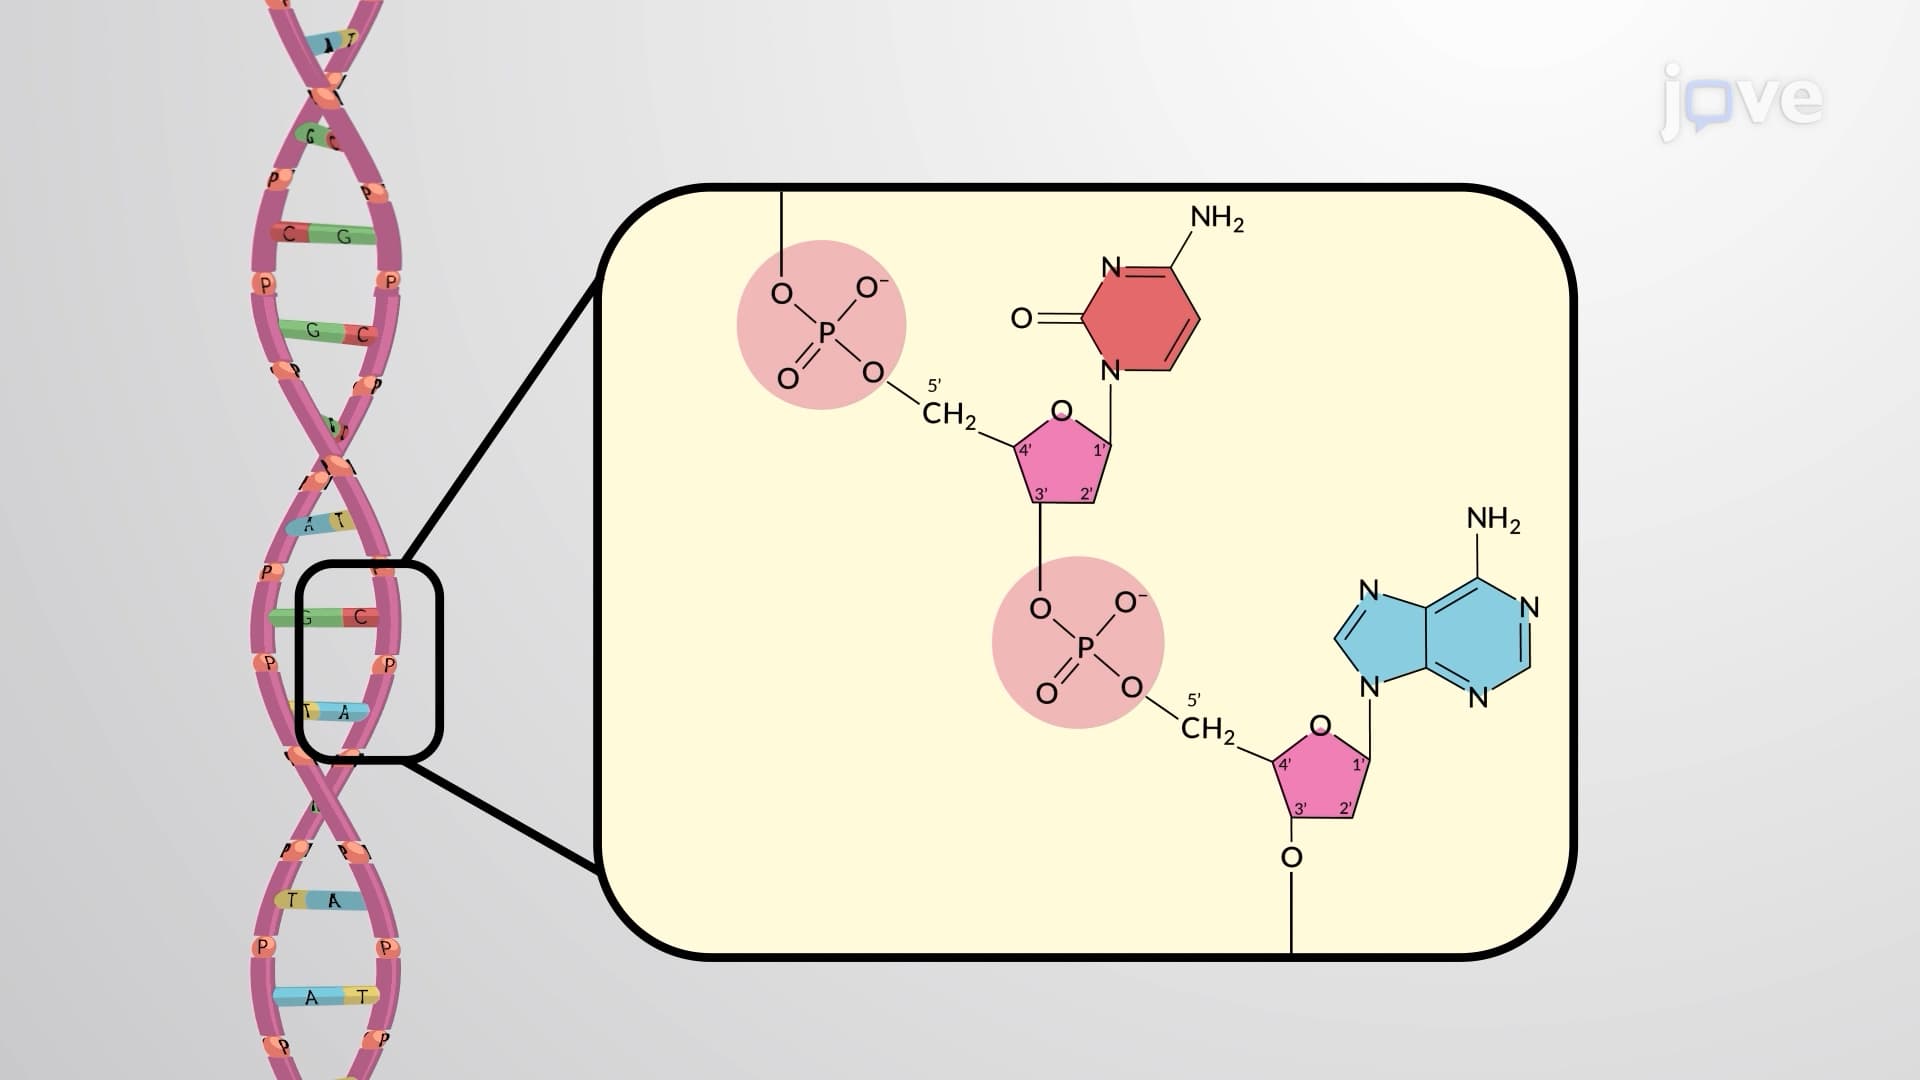
Phosphodiester Linkages
Phosphodiester bond forms when a phosphoric acid molecule (H3PO4) links with two hydroxyl groups (–OH) of two other molecules, forming two ester bonds. Two water molecules are released in this process. The phosphodiester bond is commonly found in nucleic acids (DNA and RNA) and plays a critical role in their structure and function.
Phosphodiester Bonds Link Nucleotides Together
DNA and RNA are polynucleotides or long chains of nucleotides that are linked together. A nucleotide is...
 00:49
Ligand Binding and Linkage
00:49Ligand Binding and Linkage
 01:06
What are Estimates?
The estimate for the mean of a sample is denoted by ͞x, whereas the mean of the population is designated as μ. Further, parameters such...
 01:20
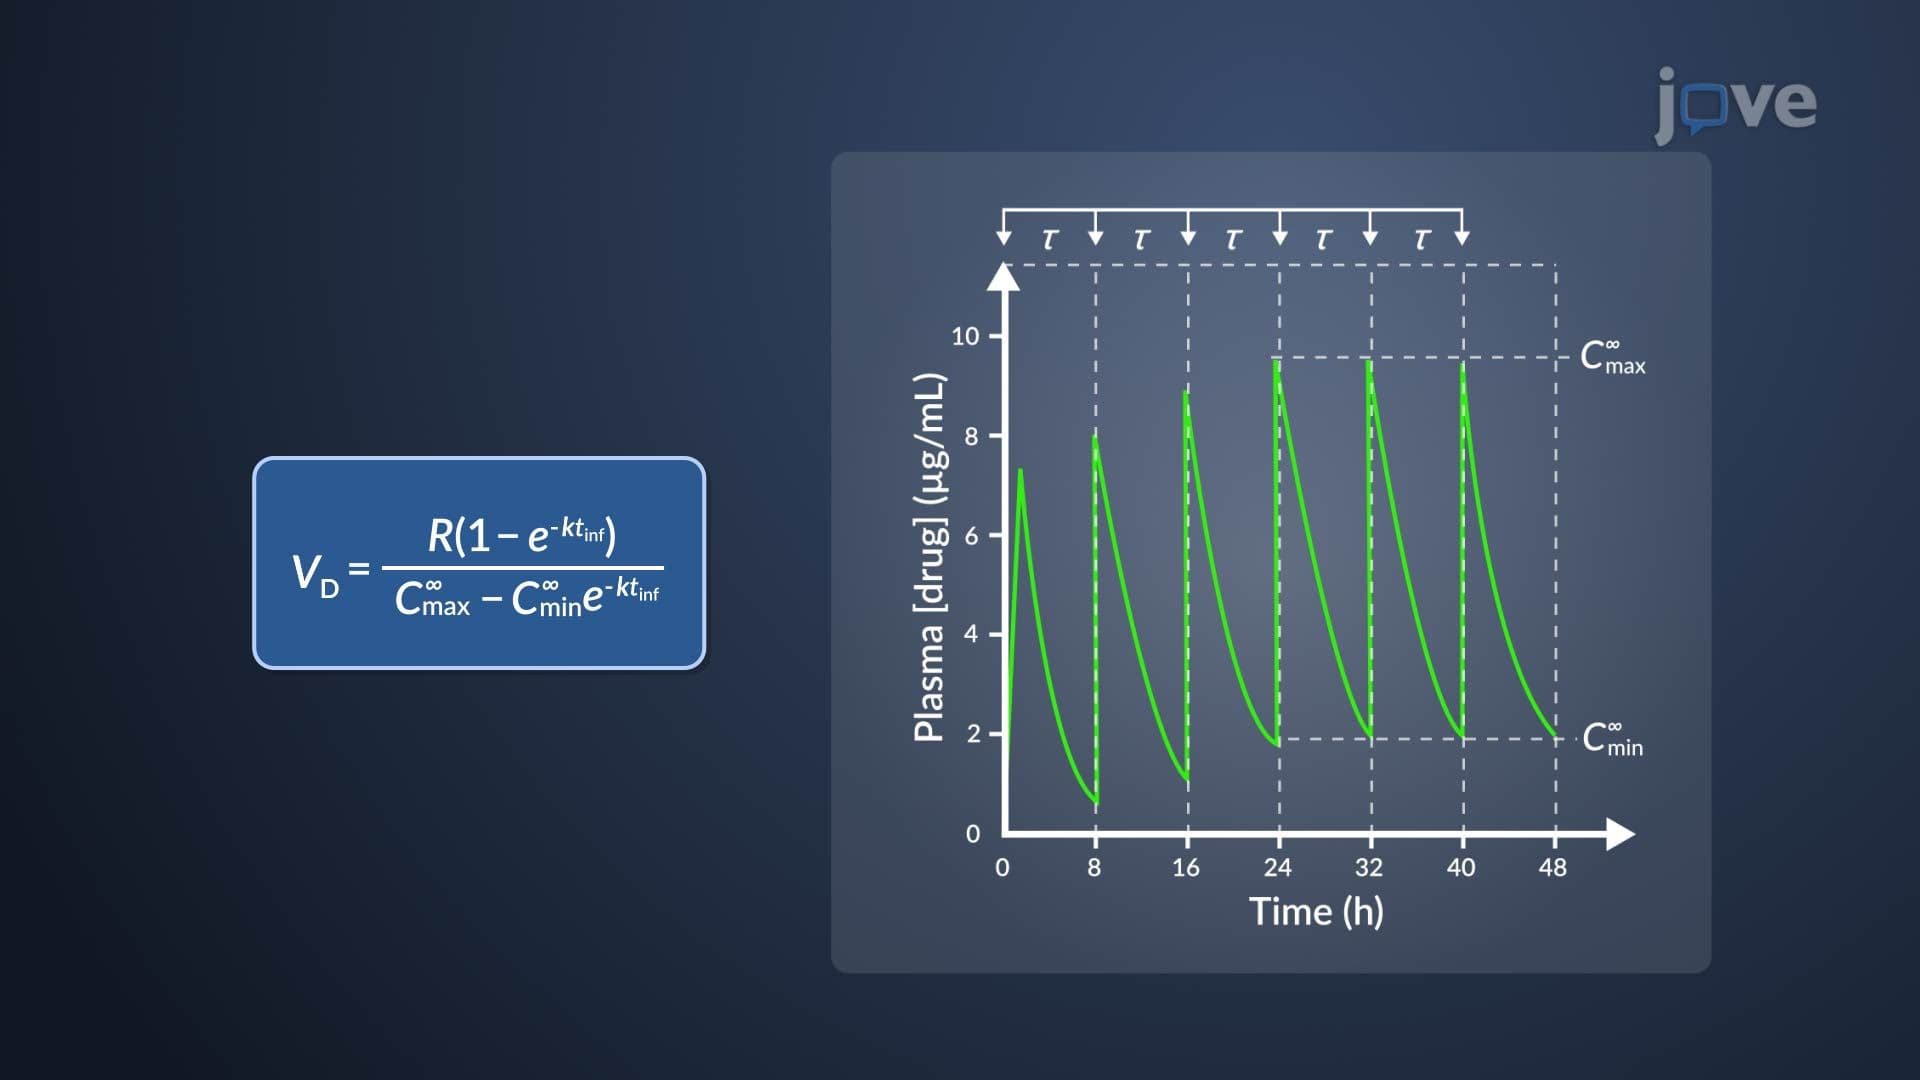
Estimation of k and VD of Aminoglycosides
 02:02
Cis-regulatory Sequences