Sensitivity Analysis for Not-at-Random Missing Data in Trial-Based Cost-Effectiveness Analysis: A Tutorial
Related Experiment Video
Updated: Feb 11, 2026
Author Spotlight: Evaluating the Adjuvant Efficacy and Safety of Angong Niuhuang Pill in Viral Encephalitis Treatment
Published on: April 19, 2024
Baptiste Leurent1, Manuel Gomes2, Rita Faria3
1Department of Medical Statistics, London School of Hygiene and Tropical Medicine, Keppel Street, London, WC1E 7HT, UK. baptiste.leurent@lshtm.ac.uk.

Abstract:
Cost-effectiveness analyses (CEA) of randomised controlled trials are a key source of information for health care decision makers. Missing data are, however, a common issue that can seriously undermine their validity. A major concern is that the chance of data being missing may be directly linked to the unobserved value itself [missing not at random (MNAR)]. For example, patients with poorer health may be less likely to complete quality-of-life questionnaires. However, the extent to which this occurs cannot be ascertained from the data at hand. Guidelines recommend conducting sensitivity analyses to assess the robustness of conclusions to plausible MNAR assumptions, but this is rarely done in practice, possibly because of a lack of practical guidance. This tutorial aims to address this by presenting an accessible framework and practical guidance for conducting sensitivity analysis for MNAR data in trial-based CEA. We review some of the methods for conducting sensitivity analysis, but focus on one particularly accessible approach, where the data are multiply-imputed and then modified to reflect plausible MNAR scenarios. We illustrate the implementation of this approach on a weight-loss trial, providing the software code. We then explore further issues around its use in practice.
Related Concept Videos
 01:12
Statistical Software for Data Analysis and Clinical Trials
 01:12
Analysis of Population Pharmacokinetic Data
 01:13
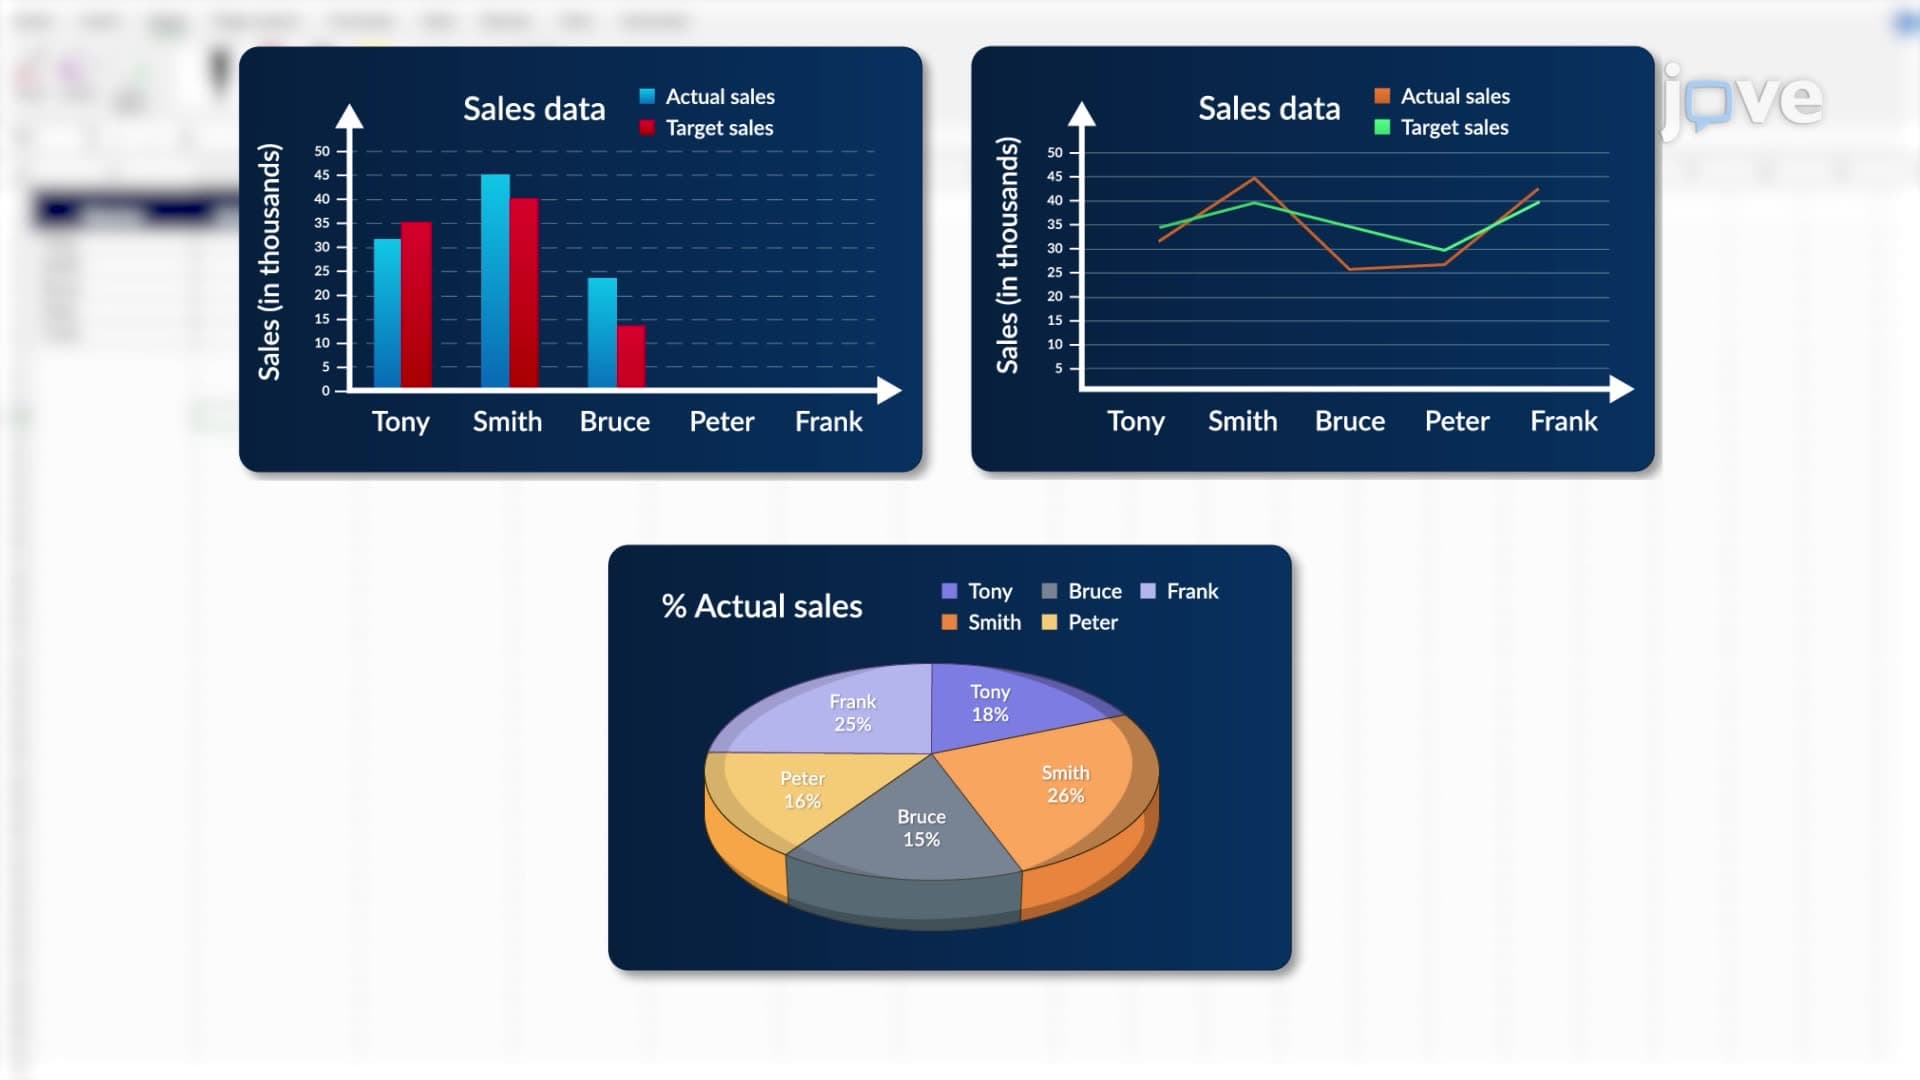
Overview of Microsoft Excel as a Data Analysis Tool
 01:17
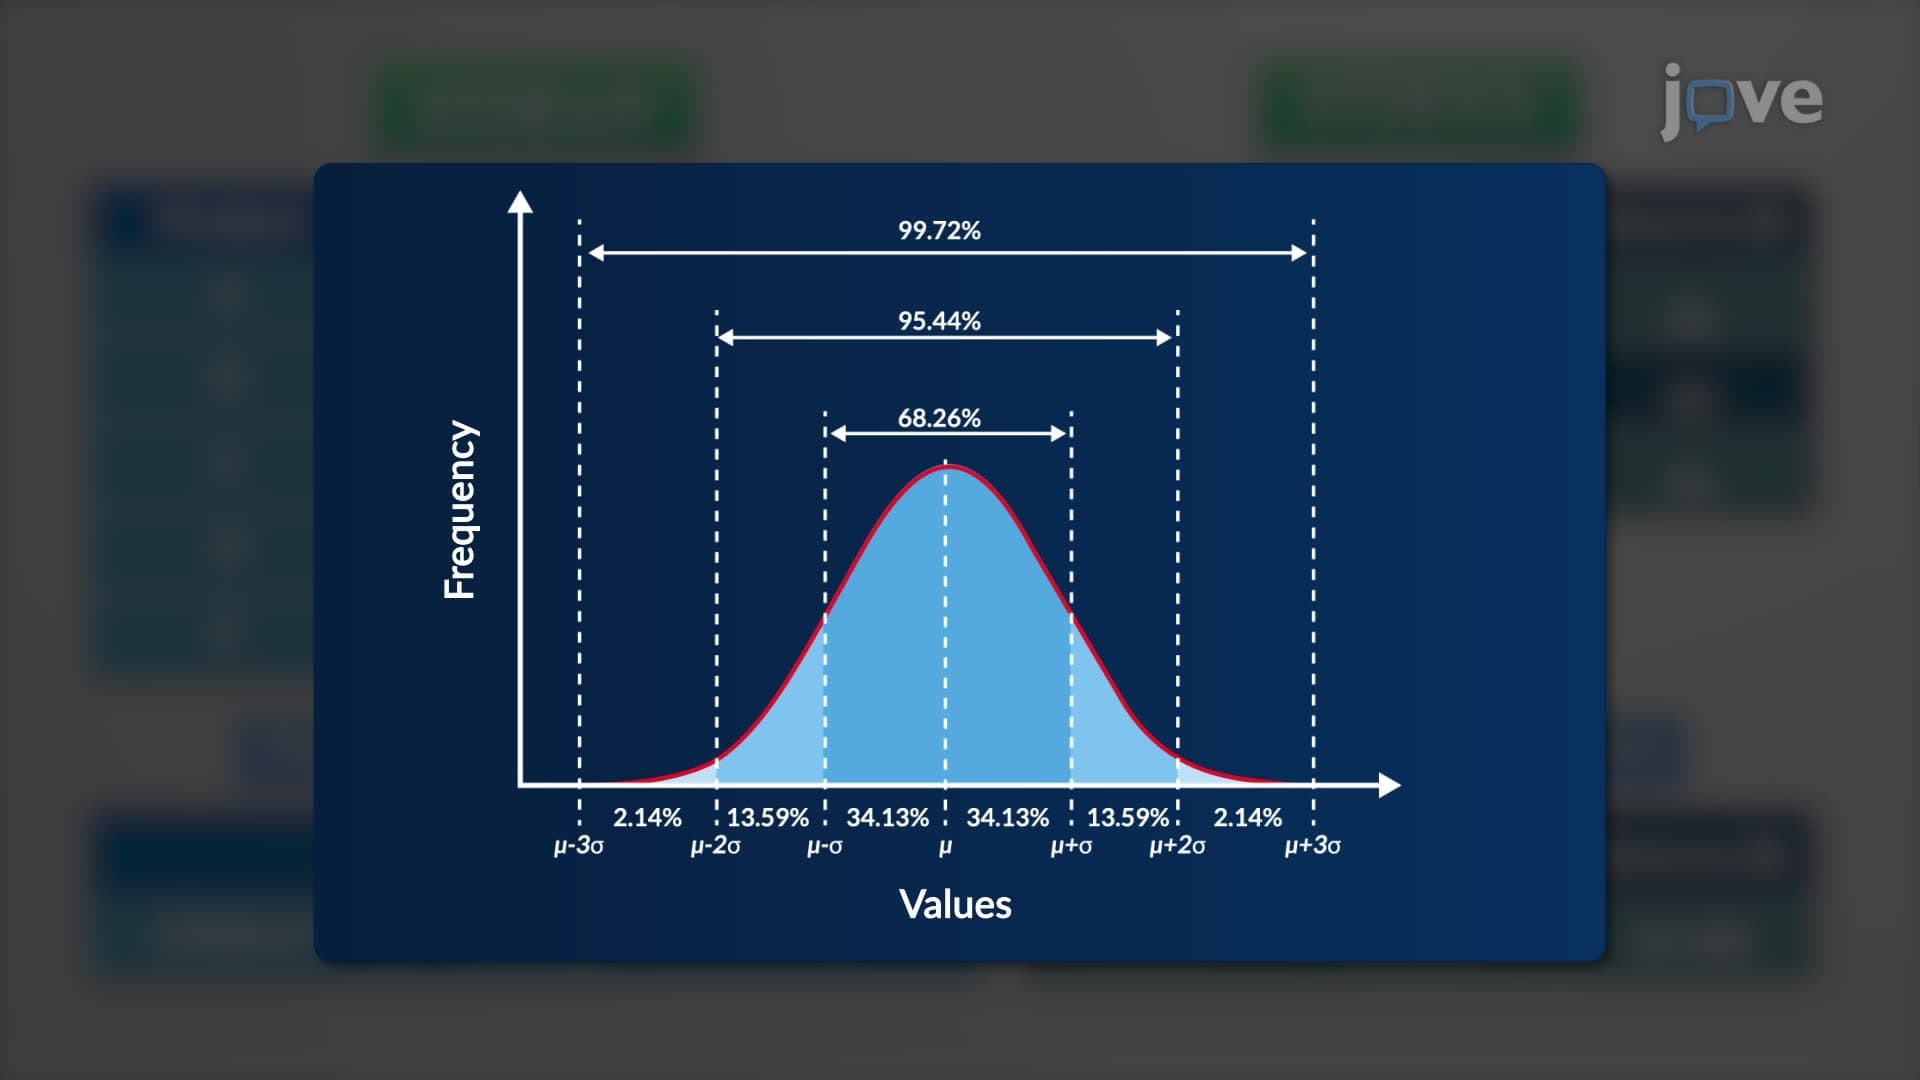
Performing a Simple Data Analysis using MS-Excel Function
SUM: This function calculates the total sum of a range of values. It's the foundation for aggregating data, essential for determining overall trends and totals in datasets.
AVERAGE: It computes the mean value of a given set of numbers, providing a quick insight into the central...
 00:59
Model-Independent Approaches for Pharmacokinetic Data: Noncompartmental Analysis
One important characteristic of noncompartmental analyses is that drug exposure increases proportionally with increasing doses. This...
 03:46
Qualitative Analysis
For instance, group IV...