Related Experiment Video
Updated: Feb 8, 2026

Basics of Multivariate Analysis in Neuroimaging Data
Published on: July 24, 2010
Using multivariate mixed-effects selection models for analyzing batch-processed proteomics data with non-ignorable
Jiebiao Wang1, Pei Wang2, Donald Hedeker1
1Department of Public Health Sciences, University of Chicago, 5841 S. Maryland Ave., Chicago, IL, USA.

Abstract:
In quantitative proteomics, mass tag labeling techniques have been widely adopted in mass spectrometry experiments. These techniques allow peptides (short amino acid sequences) and proteins from multiple samples of a batch being detected and quantified in a single experiment, and as such greatly improve the efficiency of protein profiling. However, the batch-processing of samples also results in severe batch effects and non-ignorable missing data occurring at the batch level. Motivated by the breast cancer proteomic data from the Clinical Proteomic Tumor Analysis Consortium, in this work, we developed two tailored multivariate MIxed-effects SElection models (mvMISE) to jointly analyze multiple correlated peptides/proteins in labeled proteomics data, considering the batch effects and the non-ignorable missingness. By taking a multivariate approach, we can borrow information across multiple peptides of the same protein or multiple proteins from the same biological pathway, and thus achieve better statistical efficiency and biological interpretation. These two different models account for different correlation structures among a group of peptides or proteins. Specifically, to model multiple peptides from the same protein, we employed a factor-analytic random effects structure to characterize the high and similar correlations among peptides. To model biological dependence among multiple proteins in a functional pathway, we introduced a graphical lasso penalty on the error precision matrix, and implemented an efficient algorithm based on the alternating direction method of multipliers. Simulations demonstrated the advantages of the proposed models. Applying the proposed methods to the motivating data set, we identified phosphoproteins and biological pathways that showed different activity patterns in triple negative breast tumors versus other breast tumors. The proposed methods can also be applied to other high-dimensional multivariate analyses based on clustered data with or without non-ignorable missingness.

Related Concept Videos
 01:25
Selected Data About Geographic Locations
 01:25
Statistical Methods for Analyzing Epidemiological Data
 01:12
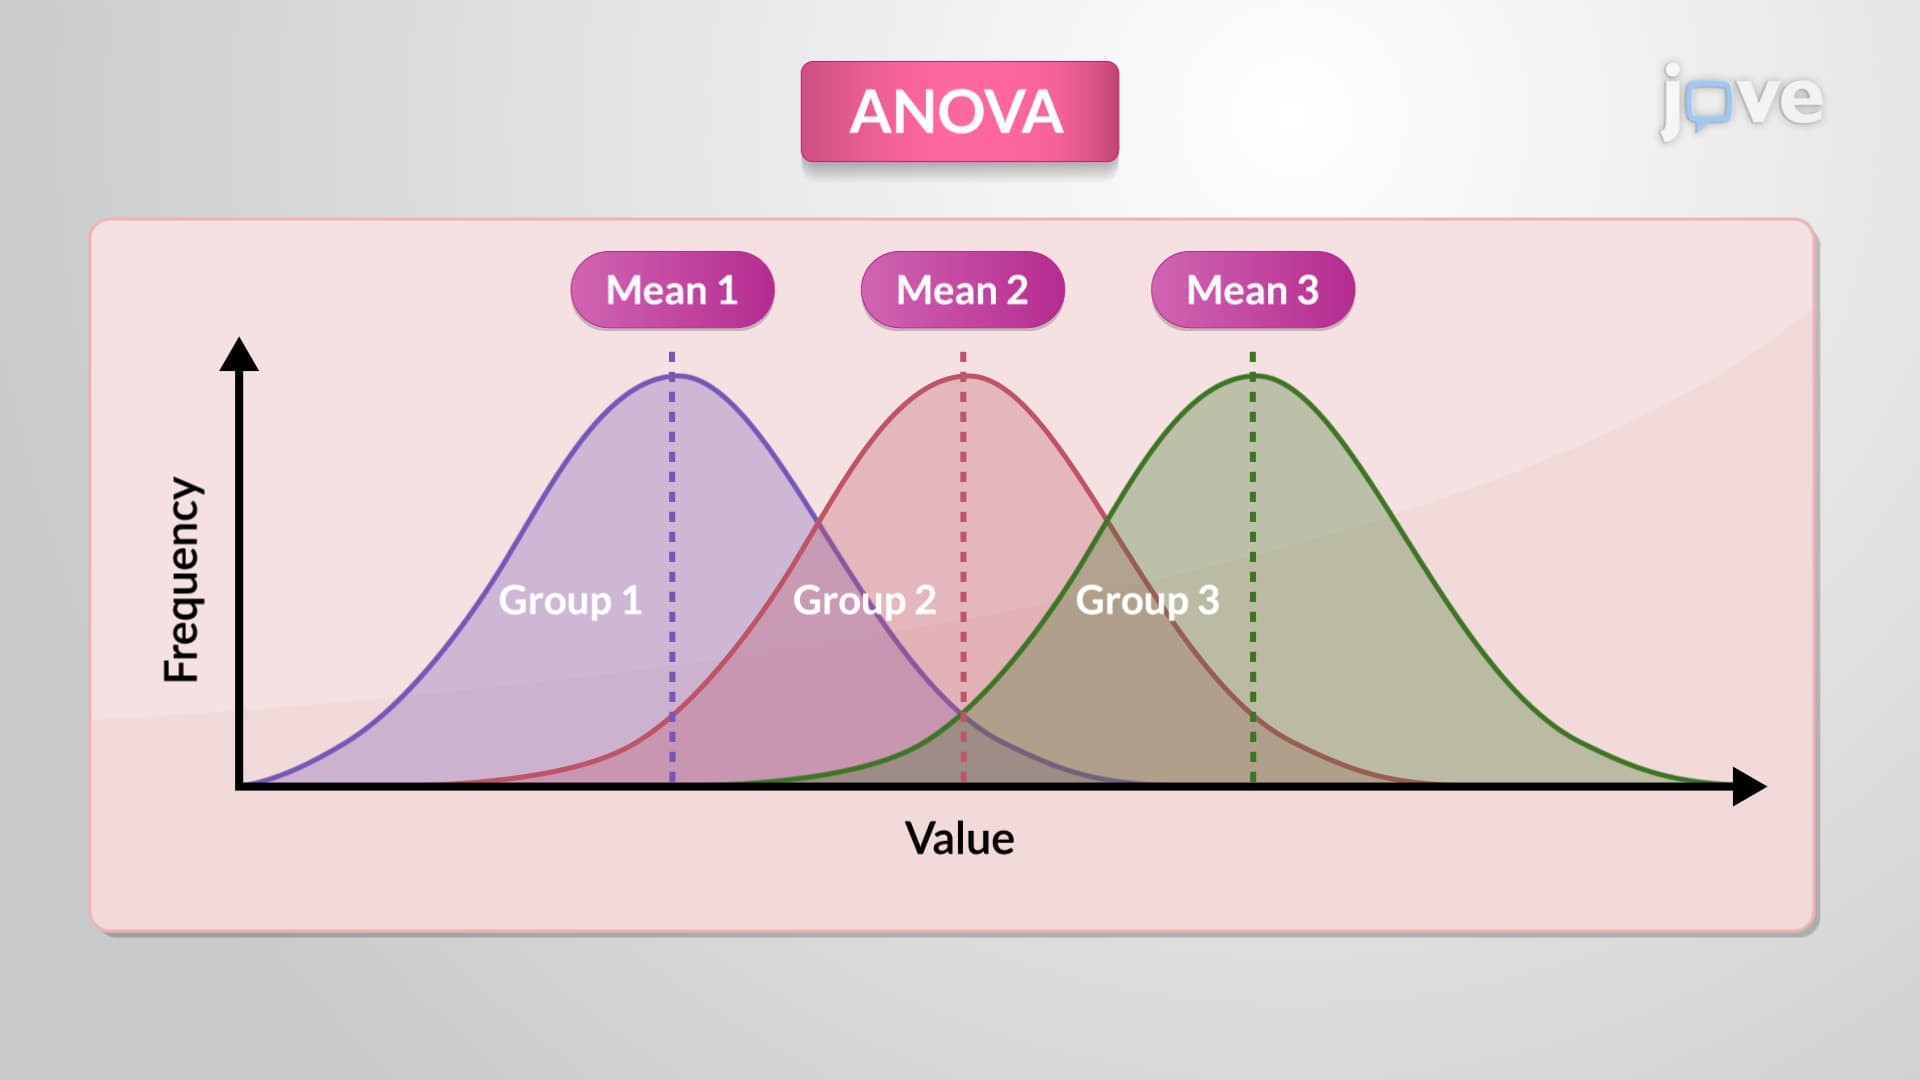
Statistical Methods to Analyze Parametric Data: ANOVA
One-way ANOVA is applied when a single independent variable or factor is scrutinized. It compares...
 01:14
Steps in the Modeling Process
Attention is the first necessary component for observational learning. It involves focusing on what the model is doing and saying. For example, if you decide to take a drawing class to enhance your skills, you need to pay close attention to the instructor's words and hand movements. The characteristics of the model significantly...
 01:09
Statistical Methods to Analyze Parametric Data: Student t-Test and Goodness-of-Fit Test
The Student's t-test is a statistical test that examines if there is a statistically significant difference between the means of two groups. This test is instrumental when dealing with...
 01:33
Proteomics
Proteomics is the study of proteomes' function. It involves the large-scale systematic study of the proteome to denote the protein complement expressed by a genome. Scientist Mark Wilkins coined the term...