BAMSI: a multi-cloud service for scalable distributed filtering of massive genome data
Related Experiment Video
Updated: Feb 8, 2026

Heuristic Mining of Hierarchical Genotypes and Accessory Genome Loci in Bacterial Populations
Published on: December 7, 2021
Kristiina Ausmees1, Aji John2, Salman Z Toor1
1Department of Information Technology, Uppsala University, Box 377, Uppsala, Sweden.

Background:
The advent of next-generation sequencing (NGS) has made whole-genome sequencing of cohorts of individuals a reality. Primary datasets of raw or aligned reads of this sort can get very large. For scientific questions where curated called variants are not sufficient, the sheer size of the datasets makes analysis prohibitively expensive. In order to make re-analysis of such data feasible without the need to have access to a large-scale computing facility, we have developed a highly scalable, storage-agnostic framework, an associated API and an easy-to-use web user interface to execute custom filters on large genomic datasets.
Results:
We present BAMSI, a Software as-a Service (SaaS) solution for filtering of the 1000 Genomes phase 3 set of aligned reads, with the possibility of extension and customization to other sets of files. Unique to our solution is the capability of simultaneously utilizing many different mirrors of the data to increase the speed of the analysis. In particular, if the data is available in private or public clouds - an increasingly common scenario for both academic and commercial cloud providers - our framework allows for seamless deployment of filtering workers close to data. We show results indicating that such a setup improves the horizontal scalability of the system, and present a possible use case of the framework by performing an analysis of structural variation in the 1000 Genomes data set.
Conclusions:
BAMSI constitutes a framework for efficient filtering of large genomic data sets that is flexible in the use of compute as well as storage resources. The data resulting from the filter is assumed to be greatly reduced in size, and can easily be downloaded or routed into e.g. a Hadoop cluster for subsequent interactive analysis using Hive, Spark or similar tools. In this respect, our framework also suggests a general model for making very large datasets of high scientific value more accessible by offering the possibility for organizations to share the cost of hosting data on hot storage, without compromising the scalability of downstream analysis.
More Related Videos
 07:49
Automated Deployment of an Internet Protocol Telephony Service on Unmanned Aerial Vehicles Using Network Functions Virtualization
Published on: November 26, 2019
 12:39
A Novel Bayesian Change-point Algorithm for Genome-wide Analysis of Diverse ChIPseq Data Types
Published on: December 10, 2012
Related Concept Videos
 01:19
Data: Types and Distribution
Distributions in...
 02:02
Genomics
 01:27
Passive Filters
Low-Pass Filters
Low-pass filters are designed to transmit signals with frequencies lower than the cutoff frequency, ωc, and attenuate those above it. The cutoff...
 01:06
Model Approaches for Pharmacokinetic Data: Distributed Parameter Models
The distributed parameter models are specifically designed to account for variations and differences in some drug classes. This model is particularly useful for assessing regional concentrations of anticancer or...
 01:25
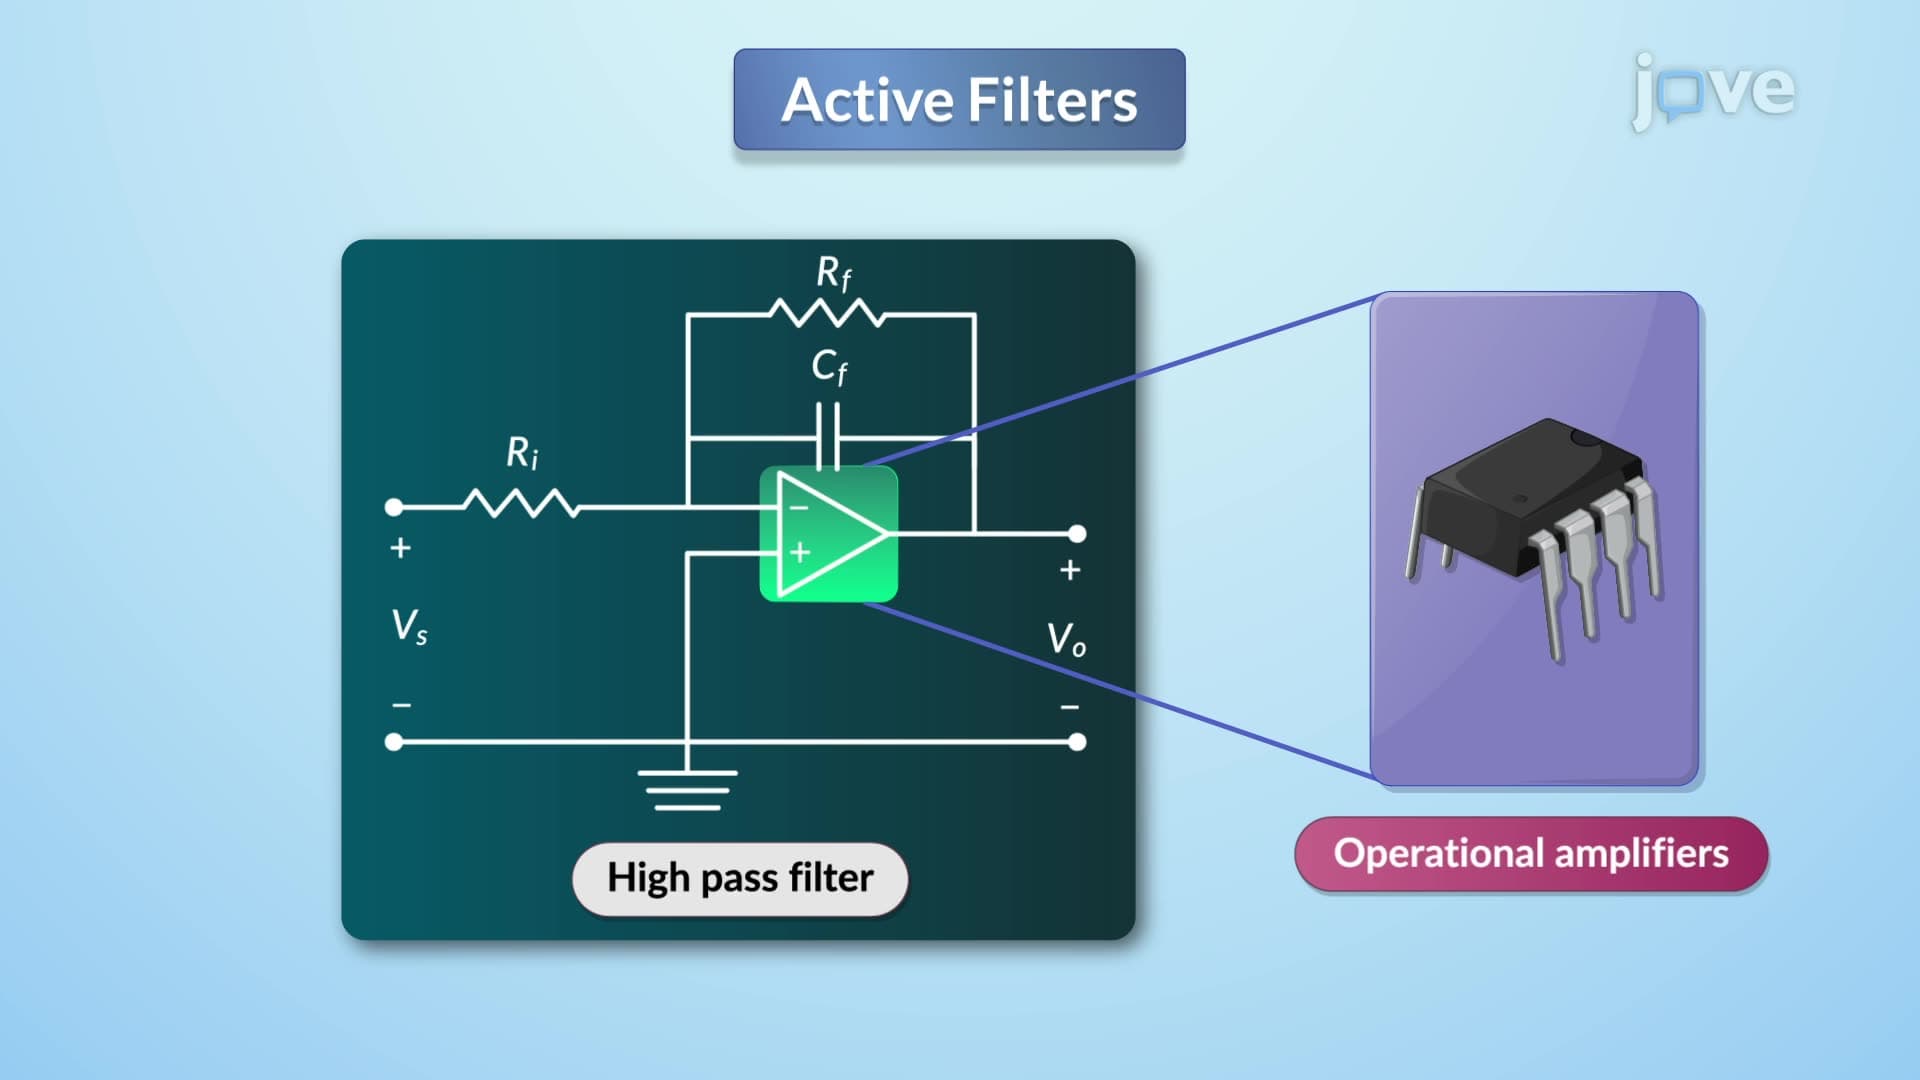
Active Filters
 01:30
Primary Healthcare Services
In 1978, international leaders convened in Alma-Ata, Kazakhstan, for what would be a pivotal event in global health. The Alma-Ata Declaration was the first to call...