Related Experiment Video
Updated: Feb 8, 2026
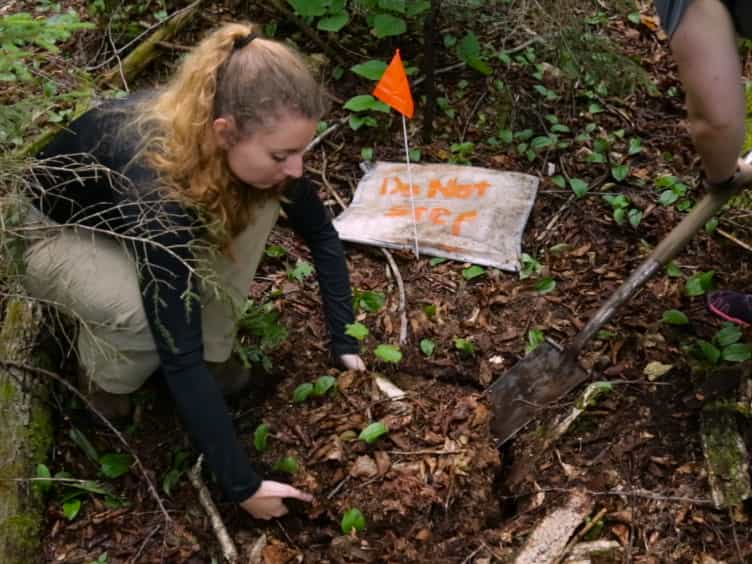

Methods of Soil Resampling to Monitor Changes in the Chemical Concentrations of Forest Soils
Published on: November 25, 2016
Predicting reference soil groups using legacy data: A data pruning and Random Forest approach for tropical
Kpade O L Hounkpatin1, Karsten Schmidt2, Felix Stumpf3
1University of Bonn, Institute of Crop Science and Resource Conservation (INRES), Soil Science and Soil Ecology, Nussallee 13, D-53115, Bonn, Germany. hozias@uni-bonn.de.

Abstract:
Predicting taxonomic classes can be challenging with dataset subject to substantial irregularities due to the involvement of many surveyors. A data pruning approach was used in the present study to reduce such source errors by exploring whether different data pruning methods, which result in different subsets of a major reference soil groups (RSG) - the Plinthosols - would lead to an increase in prediction accuracy of the minor soil groups by using Random Forest (RF). This method was compared to the random oversampling approach. Four datasets were used, including the entire dataset and the pruned dataset, which consisted of 80% and 90% respectively, and standard deviation core range of the Plinthosols data while cutting off all data points belonging to the outer range. The best prediction was achieved when RF was used with recursive feature elimination along with the non-oversampled 90% core range dataset. This model provided a substantial agreement to observation, with a kappa value of 0.57 along with 7% to 35% increase in prediction accuracy for smaller RSG. The reference soil groups in the Dano catchment appeared to be mainly influenced by the wetness index, a proxy for soil moisture distribution.
More Related Videos
Related Concept Videos
 01:24
Data Reporting and Recording
 01:11
How Data are Classified: Categorical Data
Data are classified based on whether they are measurable or not. Categorical data cannot be measured; instead, it can be divided into categories. For example, if Y denotes a person's party affiliation, some examples of Y include...
 00:59
How Data are Classified: Numerical Data
Quantitative data may be either discrete or continuous. All quantitative data that take on only specific numerical...
 01:14
Model Approaches for Pharmacokinetic Data: Compartment Models
Two primary types of compartment models are recognized: mammillary and catenary. The more...
 01:15
Model Approaches for Pharmacokinetic Data: Physiological Models
 00:59
Model-Independent Approaches for Pharmacokinetic Data: Noncompartmental Analysis
One important characteristic of noncompartmental analyses is that drug exposure increases proportionally with increasing doses. This...