Related Experiment Video
Updated: Feb 7, 2026


Targeted Next-generation Sequencing and Bioinformatics Pipeline to Evaluate Genetic Determinants of Constitutional Disease
Published on: April 4, 2018
SECAPR-a bioinformatics pipeline for the rapid and user-friendly processing of targeted enriched Illumina sequences,
Tobias Andermann1,2, Ángela Cano2,3, Alexander Zizka1,2
1Department of Biological and Environmental Sciences, University of Gothenburg, Gothenburg, Sweden.

Abstract:
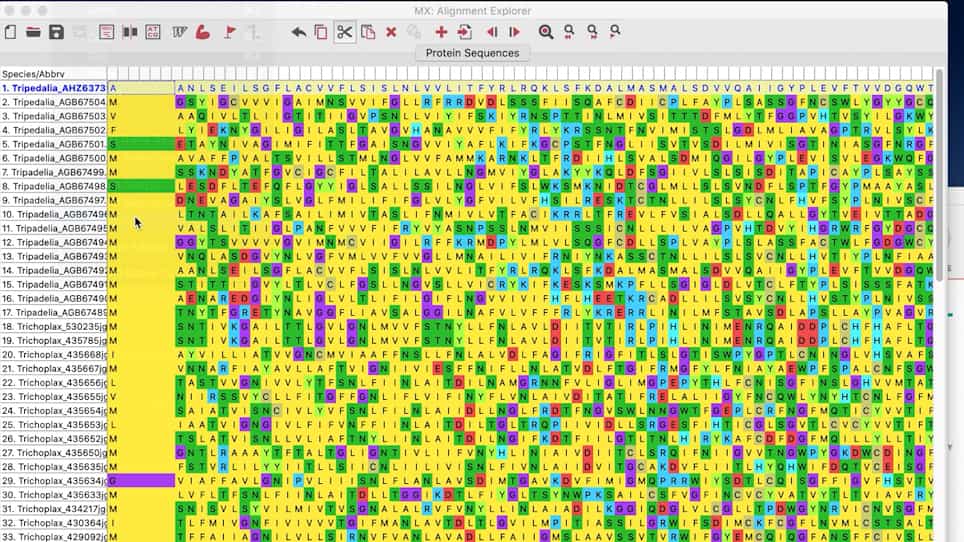
Evolutionary biology has entered an era of unprecedented amounts of DNA sequence data, as new sequencing technologies such as Massive Parallel Sequencing (MPS) can generate billions of nucleotides within less than a day. The current bottleneck is how to efficiently handle, process, and analyze such large amounts of data in an automated and reproducible way. To tackle these challenges we introduce the Sequence Capture Processor (SECAPR) pipeline for processing raw sequencing data into multiple sequence alignments for downstream phylogenetic and phylogeographic analyses. SECAPR is user-friendly and we provide an exhaustive empirical data tutorial intended for users with no prior experience with analyzing MPS output. SECAPR is particularly useful for the processing of sequence capture (synonyms: target or hybrid enrichment) datasets for non-model organisms, as we demonstrate using an empirical sequence capture dataset of the palm genus Geonoma (Arecaceae). Various quality control and plotting functions help the user to decide on the most suitable settings for even challenging datasets. SECAPR is an easy-to-use, free, and versatile pipeline, aimed to enable efficient and reproducible processing of MPS data for many samples in parallel.
Related Concept Videos
 02:46
Uncertainty in Measurement: Reading Instruments
 01:17
Design Example: Alignment of a Road Line Using GIS
 02:02
Cis-regulatory Sequences
 01:29
Sequences
 01:57
Sanger Sequencing
 01:30
Arithmetic Sequences