Related Experiment Video
Updated: Feb 4, 2026

Ultrasound Images of the Tongue: A Tutorial for Assessment and Remediation of Speech Sound Errors
Published on: January 3, 2017
Multi-resolution speech analysis for automatic speech recognition using deep neural networks: Experiments on TIMIT
Doroteo T Toledano1, María Pilar Fernández-Gallego1, Alicia Lozano-Diez1
1AuDIaS - Audio, Data Intelligence and Speech, Universidad Autónoma de Madrid, Madrid, Spain.

Abstract:
Speech Analysis for Automatic Speech Recognition (ASR) systems typically starts with a Short-Time Fourier Transform (STFT) that implies selecting a fixed point in the time-frequency resolution trade-off. This approach, combined with a Mel-frequency scaled filterbank and a Discrete Cosine Transform give rise to the Mel-Frequency Cepstral Coefficients (MFCC), which have been the most common speech features in speech processing for the last decades. These features were particularly well suited for the previous Hidden Markov Models/Gaussian Mixture Models (HMM/GMM) state of the art in ASR. In particular they produced highly uncorrelated features of small dimensionality (typically 13 coefficients plus deltas and double deltas), which was very convenient for diagonal covariance GMMs, for dealing with the curse of dimensionality and for the limited computing resources of a decade ago. Currently most ASR systems use Deep Neural Networks (DNN) instead of the GMMs for modeling the acoustic features, which provides more flexibility regarding the definition of the features. In particular, acoustic features can be highly correlated and can be much larger in size because the DNNs are very powerful at processing high-dimensionality inputs. Also, the computing hardware has reached a level of evolution that makes computational cost in speech processing a less relevant issue. In this context we have decided to revisit the problem of the time-frequency resolution in speech analysis, and in particular to check if multi-resolution speech analysis (both in time and frequency) can be helpful in improving acoustic modeling using DNNs. Our experiments start with several Kaldi baseline system for the well known TIMIT corpus and modify them by adding multi-resolution speech representations by concatenating different spectra computed using different time-frequency resolutions and different post-processed and speaker-adapted features using different time-frequency resolutions. Our experiments show that using a multi-resolution speech representation tends to improve over results using the baseline single resolution speech representation, which seems to confirm our main hypothesis. However, results combining multi-resolution with the highly post-processed and speaker-adapted features, which provide the best results in Kaldi for TIMIT, yield only very modest improvements.
Related Concept Videos
 01:28
Automatic Processing and Automatic Social Behavior
 02:26
Protein Networks
These interactions can be represented through maps depicting protein-protein interaction networks, represented as nodes and edges. Nodes are circles that are representative of a protein,...
 02:18
Network Covalent Solids
To break or to melt a covalent network solid, covalent bonds must be broken. Because covalent bonds are relatively strong, covalent network solids are typically...
 01:12
What is an Experiment?
 01:37
Neural Regulation
 01:19
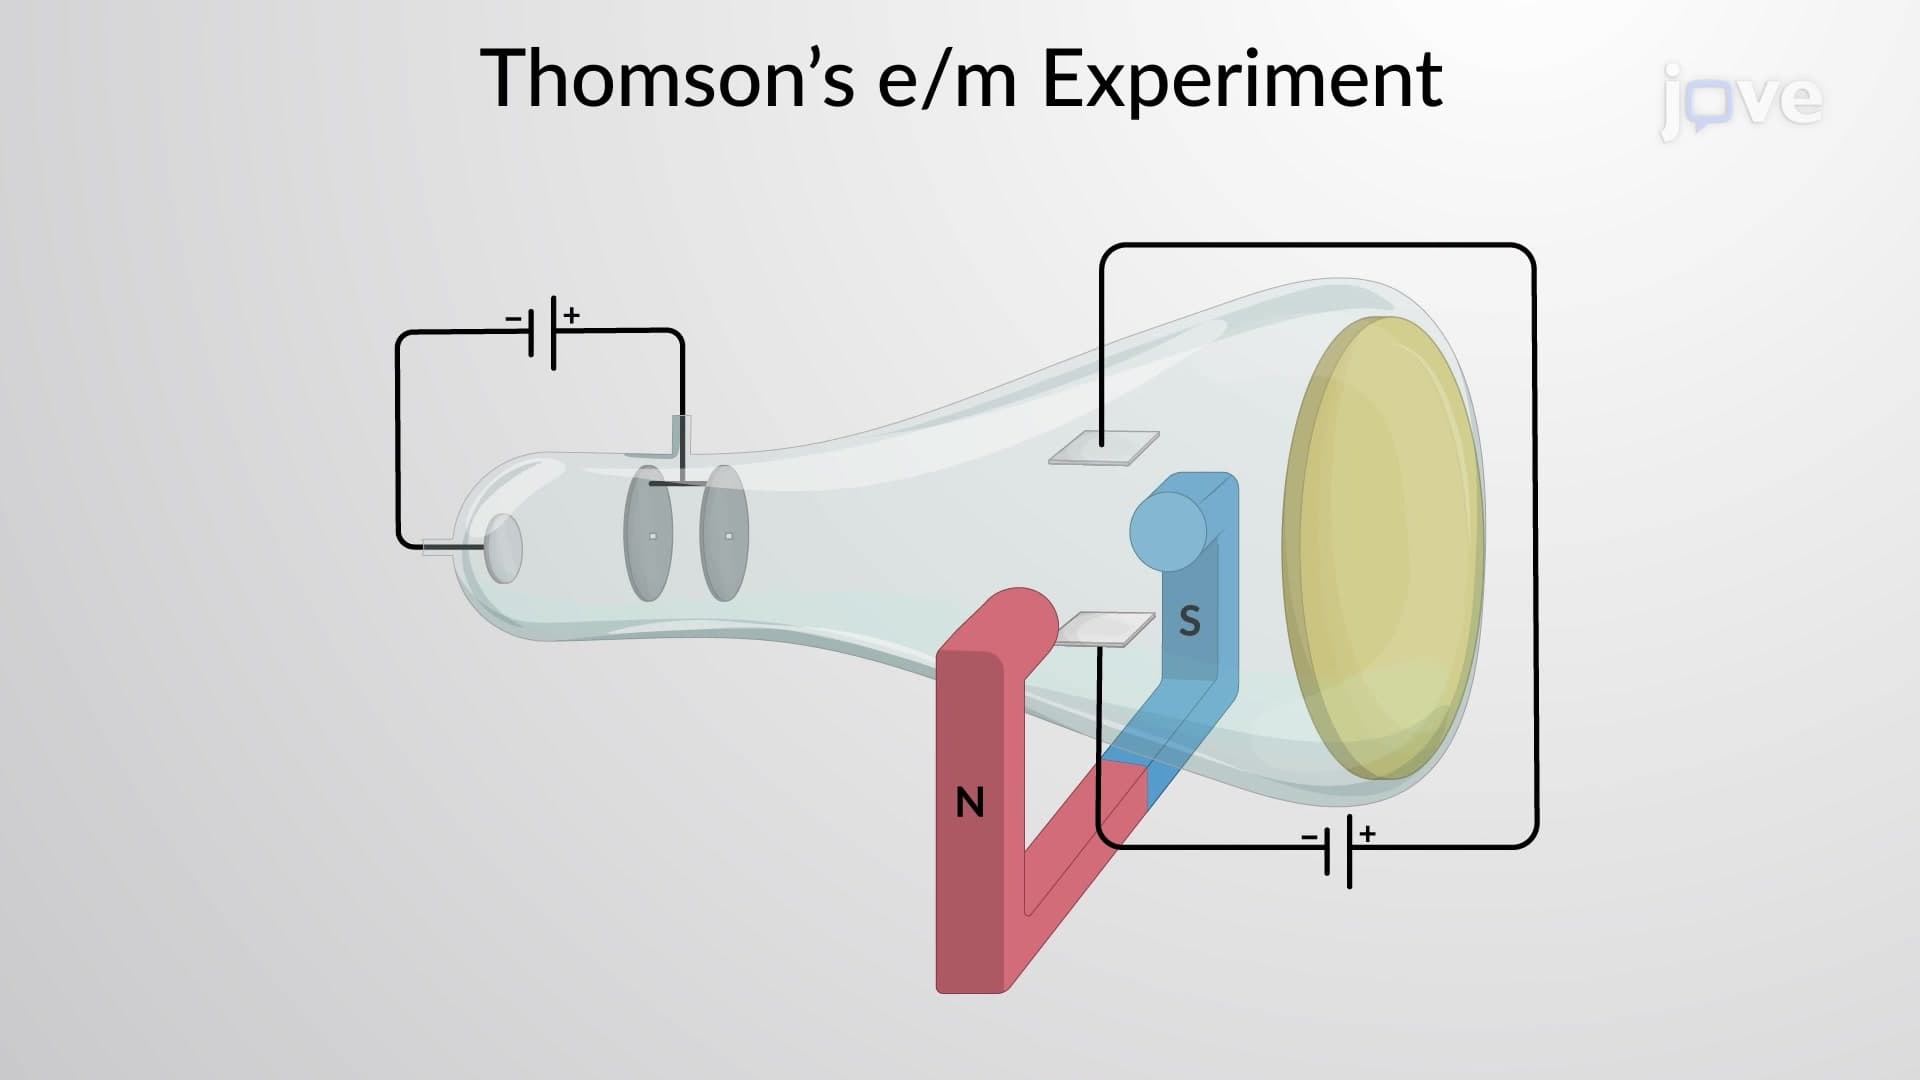
Thomson's e/m Experiment
A particle with charge q, speed v, and mass m enters an area from the top, where the magnetic and electric fields are perpendicular both to the particle's motion and to one another. The magnetic...