Related Experiment Video
Updated: Feb 3, 2026

Optimization for Sequencing and Analysis of Degraded FFPE-RNA Samples
Published on: June 8, 2020
Modified SureSelectQXT Target Enrichment Protocol for Illumina Multiplexed Sequencing of FFPE Samples
J M Rosa-Rosa1, T Caniego-Casas2, S Leskela1,2
11CIBER-ONC, Instituto de Salud Carlos III, Madrid, Spain.

Background:
Personalised medicine is nowadays a major objective in oncology. Molecular characterization of tumours through NGS offers the possibility to find possible therapeutic targets in a time- and cost-effective way. However, the low quality and complexity of FFPE DNA samples bring a series of disadvantages for massive parallel sequencing techniques compared to high-quality DNA samples (from blood cells, cell cultures, etc.).
Results:
We performed several experiments to understand the behaviour of FFPE DNA samples during the construction of SureSelectQXT libraries. First, we designed a quality checkpoint for FFPE DNA samples based on the quantification of their amplification capability (qcPCR). We observed that FFPE DNA samples can be classified according to DIN value and qcPCR concentration into unusable, or low-quality (LQ) and good-quality (GQ) DNA. For GQ samples, we increased the amount of input DNA to 150 ng and the digestion time to 30 min, whereas for LQ samples, we used 50 ng of DNA as input but we decreased the digestion time to 1 min. In all cases, we increased the cycles of the pre-hyb PCR to 10 but decreased the cycles of the post-hyb PCR to 8. In addition, we confirmed that using half of the volume of reagents can be beneficial. Finally, in order to obtain better results, we designed a decision flow-chart to achieve a seeding concentration of 12-14 pM for MiSeq Reagent Kit v2.
Conclusions:
Our experiments allowed us to unveil the behaviour of low-quality FFPE DNA samples during the construction of SureSelectQXT libraries. Sequencing results showed that, using our modified SureSelectQXT protocol, the final percentage of usable reads for low-quality samples was increased more than three times allowing to reach median depth/million reads values of 76.35. This value is equivalent to ~ 0.9 and ~ 0.7 of the values obtained for good-quality FFPE and high-quality DNA respectively.
Insights
Optimized protocols significantly improve next-generation sequencing (NGS) of low-quality FFPE DNA. This advancement enhances the utility of FFPE samples for personalized oncology, increasing usable reads over threefold.
Area of Science:
- Oncology
- Genomics
- Molecular Biology
Background:
- Personalized medicine in oncology relies on molecular tumor characterization.
- Next-generation sequencing (NGS) enables efficient identification of therapeutic targets.
- Low-quality DNA from FFPE samples poses challenges for NGS library preparation.
Purpose of the Study:
- To investigate the behavior of FFPE DNA during SureSelect QXT library construction.
- To develop optimized protocols for FFPE DNA library preparation and sequencing.
- To improve the yield of usable sequencing reads from low-quality FFPE samples.
Main Methods:
- Development of a quality checkpoint (qcPCR) for FFPE DNA samples.
- Classification of FFPE DNA into unusable, low-quality (LQ), and good-quality (GQ) categories.
- Modification of input DNA amounts, digestion times, PCR cycles, and reagent volumes for SureSelect QXT library preparation.
- Design of a decision flowchart for achieving optimal seeding concentration for MiSeq sequencing.
Main Results:
- FFPE DNA samples can be reliably classified using DIN value and qcPCR concentration.
- Optimized SureSelect QXT protocol parameters were determined for both GQ and LQ FFPE DNA.
- Reduced reagent volumes were found to be beneficial for library preparation.
Conclusions:
- The modified SureSelect QXT protocol significantly enhances sequencing of low-quality FFPE DNA.
- Usable sequencing reads from LQ FFPE samples increased more than threefold.
- Achieved median depth/million reads values approach those of high-quality DNA samples, enabling better molecular profiling for personalized medicine.
Related Concept Videos
 02:02
Cis-regulatory Sequences
 01:29
Sequences
 01:57
Sanger Sequencing
 01:30
Arithmetic Sequences
 00:57
Modified Boxplots
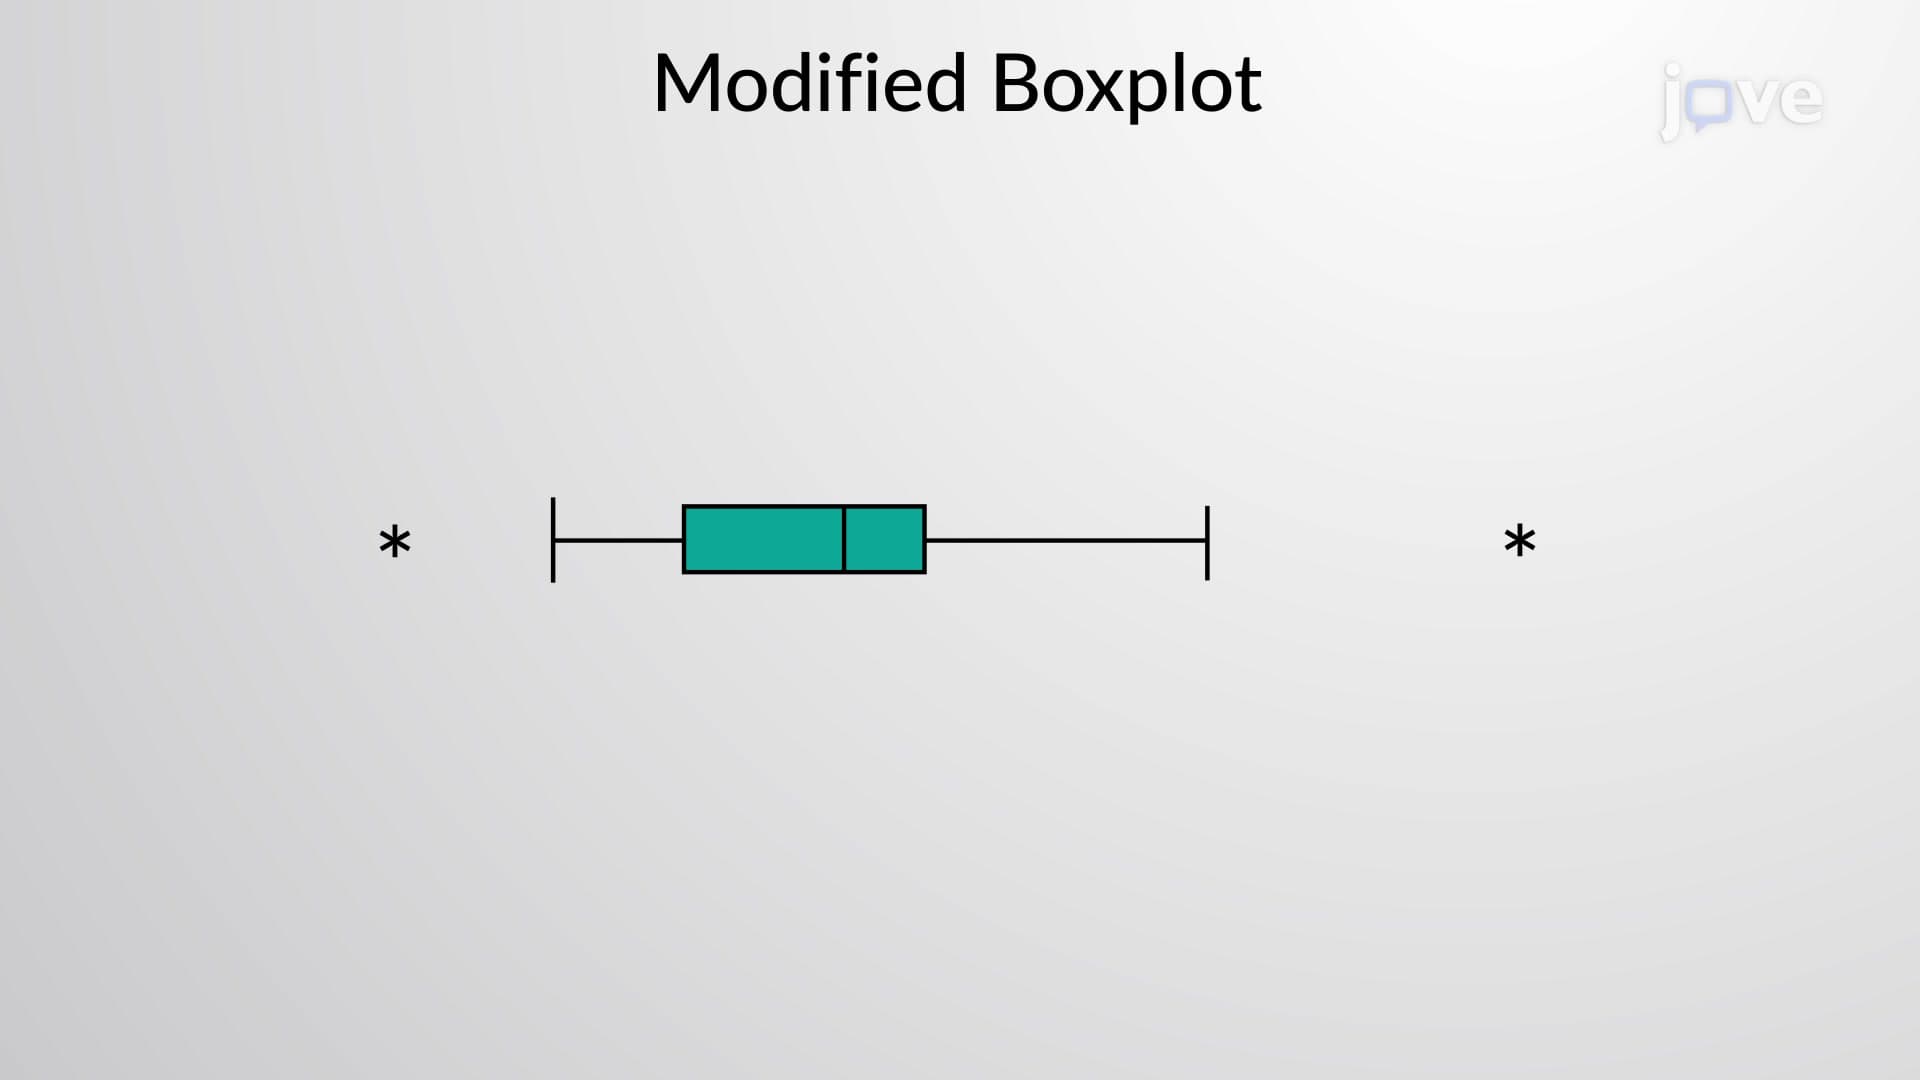
However, the box plot does not tell the reader about outliers - values that lie far from the center of the data. We can modify the standard box and whisker plot to identify the outliers and visualize the actual spread of the data in a sample.
Initially, we calculate the adjusted...
 03:00
Next-generation Sequencing
Next-Generation Sequencing Methods
Although all next-generation methods use different technologies, they all share a set of standard features....