Related Experiment Video
Updated: Feb 3, 2026

Design, Surface Treatment, Cellular Plating, and Culturing of Modular Neuronal Networks Composed of Functionally Inter-connected Circuits
Published on: April 15, 2015
A Scalable FPGA Architecture for Randomly Connected Networks of Hodgkin-Huxley Neurons
Kaveh Akbarzadeh-Sherbaf1, Behrooz Abdoli1, Saeed Safari1
1High Performance Embedded Architecture Lab., School of Electrical and Computer Engineering, College of Engineering, University of Tehran, Tehran, Iran.

Abstract:
Human intelligence relies on the vast number of neurons and their interconnections that form a parallel computing engine. If we tend to design a brain-like machine, we will have no choice but to employ many spiking neurons, each one has a large number of synapses. Such a neuronal network is not only compute-intensive but also memory-intensive. The performance and the configurability of the modern FPGAs make them suitable hardware solutions to deal with these challenges. This paper presents a scalable architecture to simulate a randomly connected network of Hodgkin-Huxley neurons. To demonstrate that our architecture eliminates the need to use a high-end device, we employ the XC7A200T, a member of the mid-range Xilinx Artix®-7 family, as our target device. A set of techniques are proposed to reduce the memory usage and computational requirements. Here we introduce a multi-core architecture in which each core can update the states of a group of neurons stored in its corresponding memory bank. The proposed system uses a novel method to generate the connectivity vectors on the fly instead of storing them in a huge memory. This technique is based on a cyclic permutation of a single prestored connectivity vector per core. Moreover, to reduce both the resource usage and the computational latency even more, a novel approximate two-level counter is introduced to count the number of the spikes at the synapse for the sparse network. The first level is a low cost saturated counter implemented on FPGA lookup tables that reduces the number of inputs to the second level exact adder tree. It, therefore, results in much lower hardware cost for the counter circuit. These techniques along with pipelining make it possible to have a high-performance, scalable architecture, which could be configured for either a real-time simulation of up to 5120 neurons or a large-scale simulation of up to 65536 neurons in an appropriate execution time on a cost-optimized FPGA.
Related Concept Videos
 02:26
Protein Networks
These interactions can be represented through maps depicting protein-protein interaction networks, represented as nodes and edges. Nodes are circles that are representative of a protein,...
 02:18
Network Covalent Solids
To break or to melt a covalent network solid, covalent bonds must be broken. Because covalent bonds are relatively strong, covalent network solids are typically...
 01:04
Random Error
 01:09
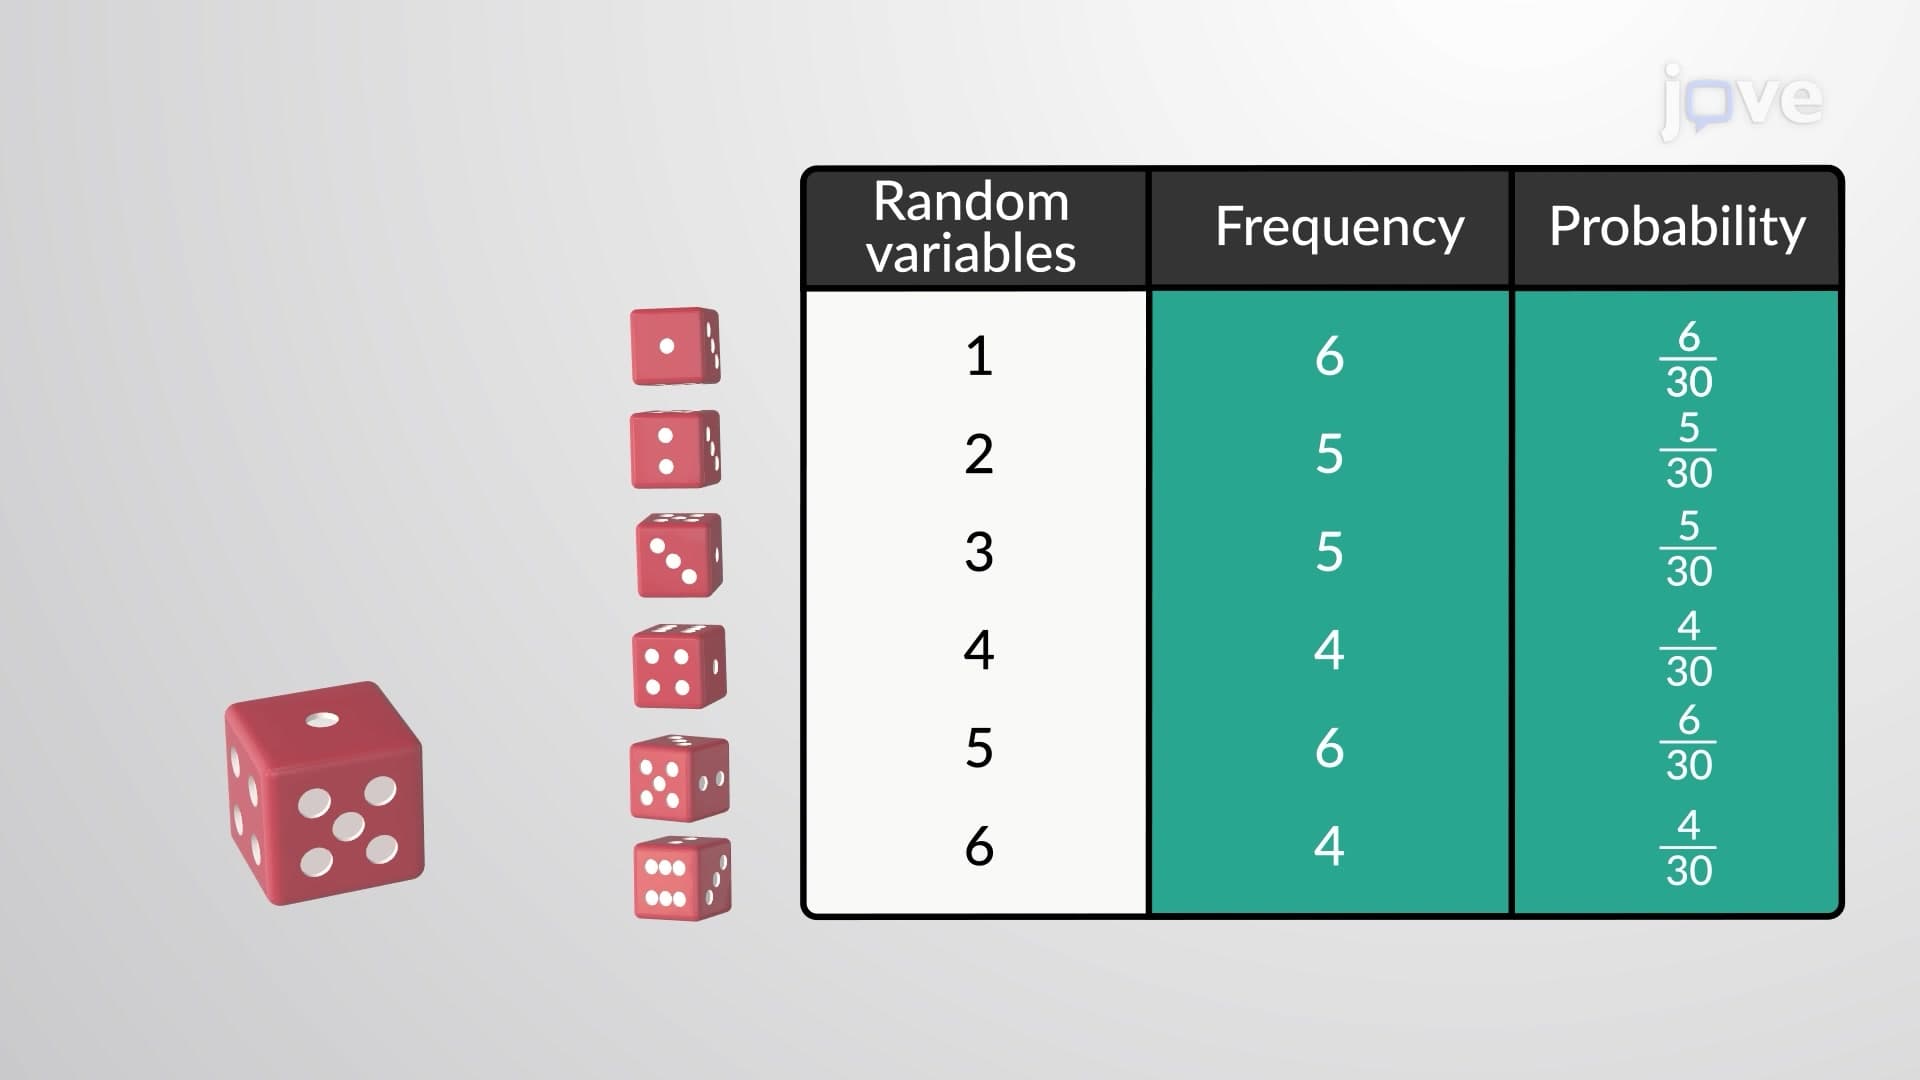
Random Variables
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
 01:13
Randomized Experiments
Simple randomization
Simple...
 01:20
Random and Systematic Errors