Related Experiment Video
Updated: Feb 3, 2026
Evaluation of Photosynthetic Efficiency in Photorespiratory Mutants by Chlorophyll Fluorescence Analysis
Published on: December 9, 2022
Stable and Efficient Policy Evaluation

Abstract:
Policy evaluation algorithms are essential to reinforcement learning due to their ability to predict the performance of a policy. However, there are two long-standing issues lying in this prediction problem that need to be tackled: off-policy stability and on-policy efficiency. The conventional temporal difference (TD) algorithm is known to perform very well in the on-policy setting, yet is not off-policy stable. On the other hand, the gradient TD and emphatic TD algorithms are off-policy stable, but are not on-policy efficient. This paper introduces novel algorithms that are both off-policy stable and on-policy efficient by using the oblique projection method. The empirical experimental results on various domains validate the effectiveness of the proposed approach.
Related Concept Videos
 03:00
Self-Evaluation: Self-Enhancement and Self-Verification
 01:01
Production Efficiency
 00:46
Trophic Efficiency
 01:16
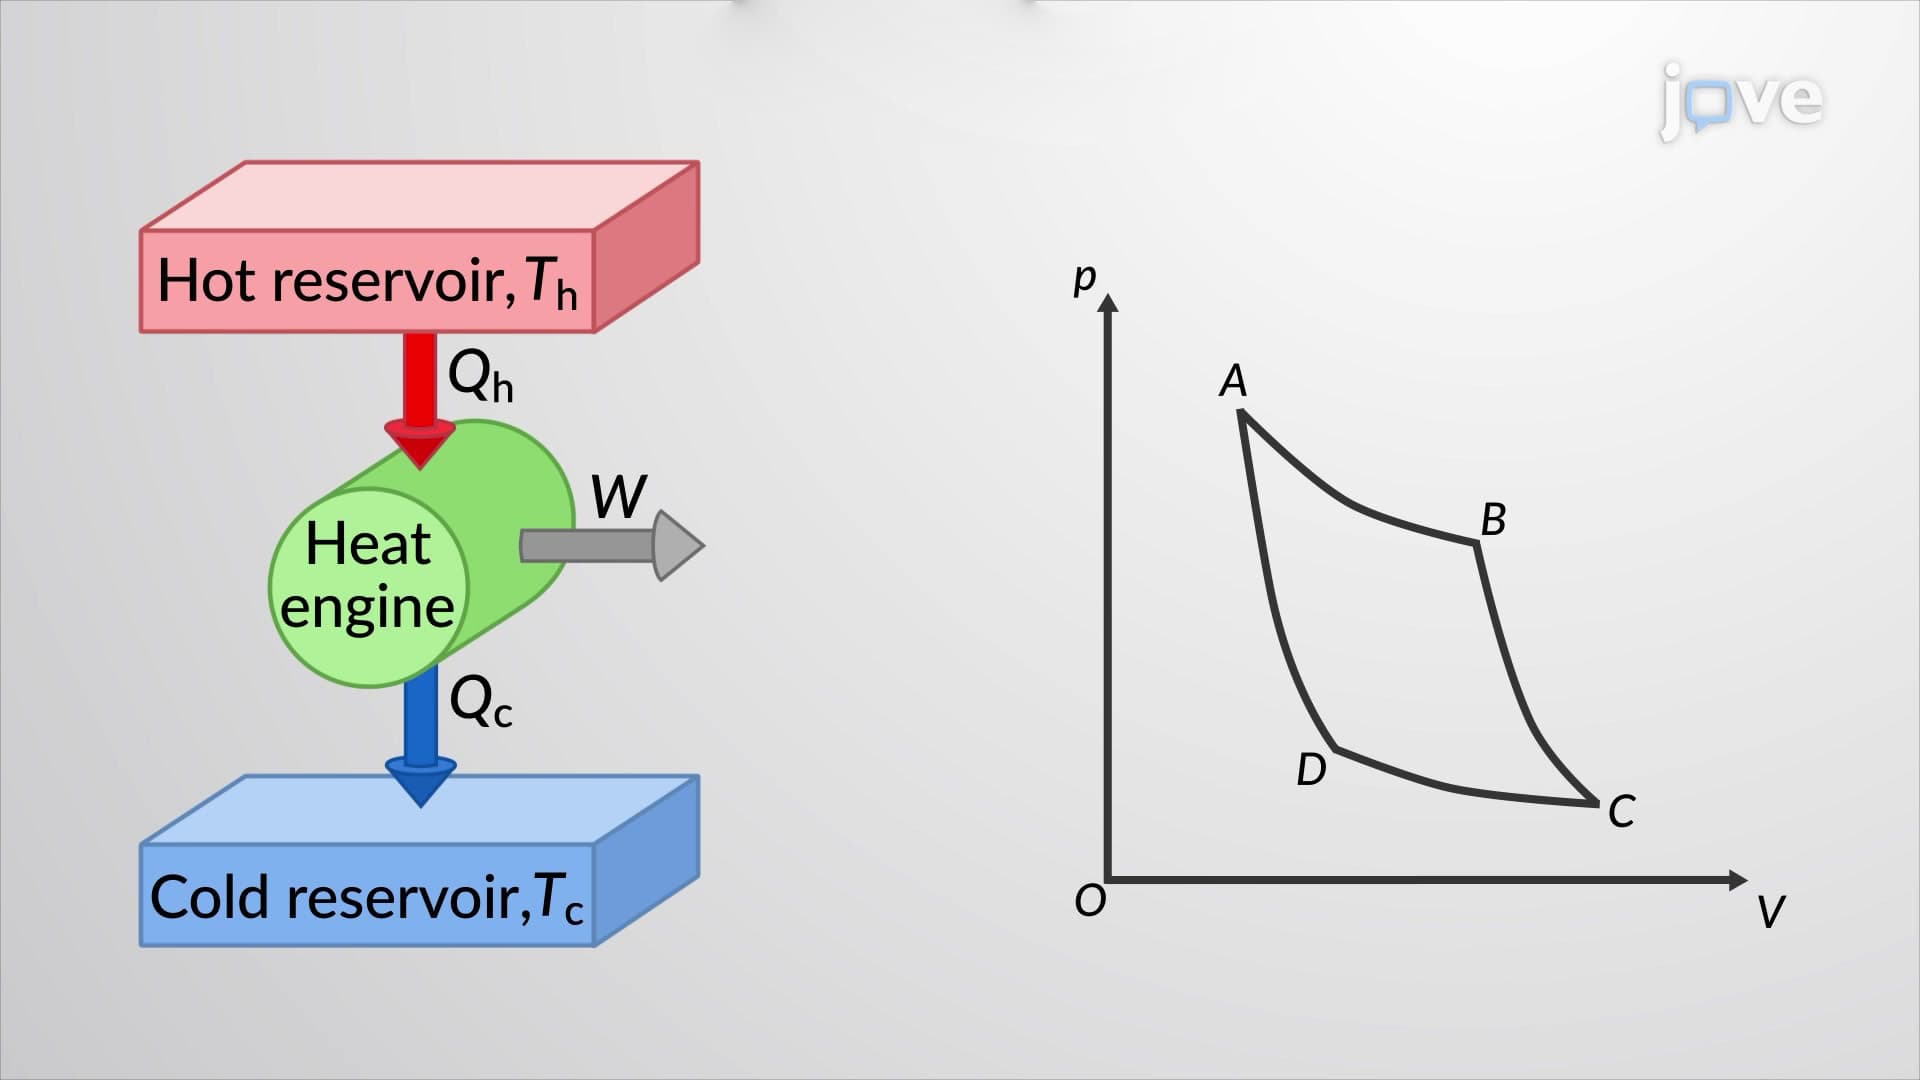
Efficiency of The Carnot Cycle
 01:19
Turnover Number and Catalytic Efficiency
Chymotrypsin is a pancreatic enzyme that breaks down proteins during digestion....
 01:10
Column Efficiency: Plate Theory
A higher number of theoretical plates signifies better column efficiency and improved separation capabilities. Plate height affects bandwidth and separation quality; it is inversely...