JPlogP: an improved logP predictor trained using predicted data
Related Experiment Video
Updated: Feb 1, 2026
A Real-World High-Intensity Interval Training Protocol for Cardiorespiratory Fitness Improvement
Published on: February 22, 2022
Jeffrey Plante1, Stephane Werner2
1Lhasa Limited, Granary Wharf House, 2 Canal Wharf, Leeds, LS11 5PS, UK. jeffrey.plante@lhasalimited.org.

Abstract:
The partition coefficient between octanol and water (logP) has been an important descriptor in QSAR predictions for many years and therefore the prediction of logP has been examined countless times. One of the best performing models is to predict the logP using multiple methods and average the result. We have used those averaged predictions to develop a training-set which was able to distil the information present across the disparate logP methods into one single model. Our model was built using extendable atom-types, where each atom is distilled down into a 6 digit number, and each individual atom is assumed to have a small additive effect on the overall logP of the molecule. Beyond the simple coefficient model a consensus model is evaluated, which uses known compounds as a starting point in the calculation and modifies the experimental logP using the same coefficients as in the first model. We then test the performance of our models against two different datasets, one where many different models routinely perform well against, and another designed to more represent pharmaceutical space. The true strength of the model is represented in the pharmaceutical benchmark set, where both models perform better than any previously developed models.
More Related Videos
 08:48
Adapted Resistance Training Improves Strength in Eight Weeks in Individuals with Multiple Sclerosis
Published on: January 29, 2016
 07:01
Working Memory Training for Older Participants: A Control Group Training Regimen and Initial Intellectual Functioning Assessment
Published on: September 20, 2020
Related Concept Videos
 02:27
Predicting Molecular Geometry
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
 01:07
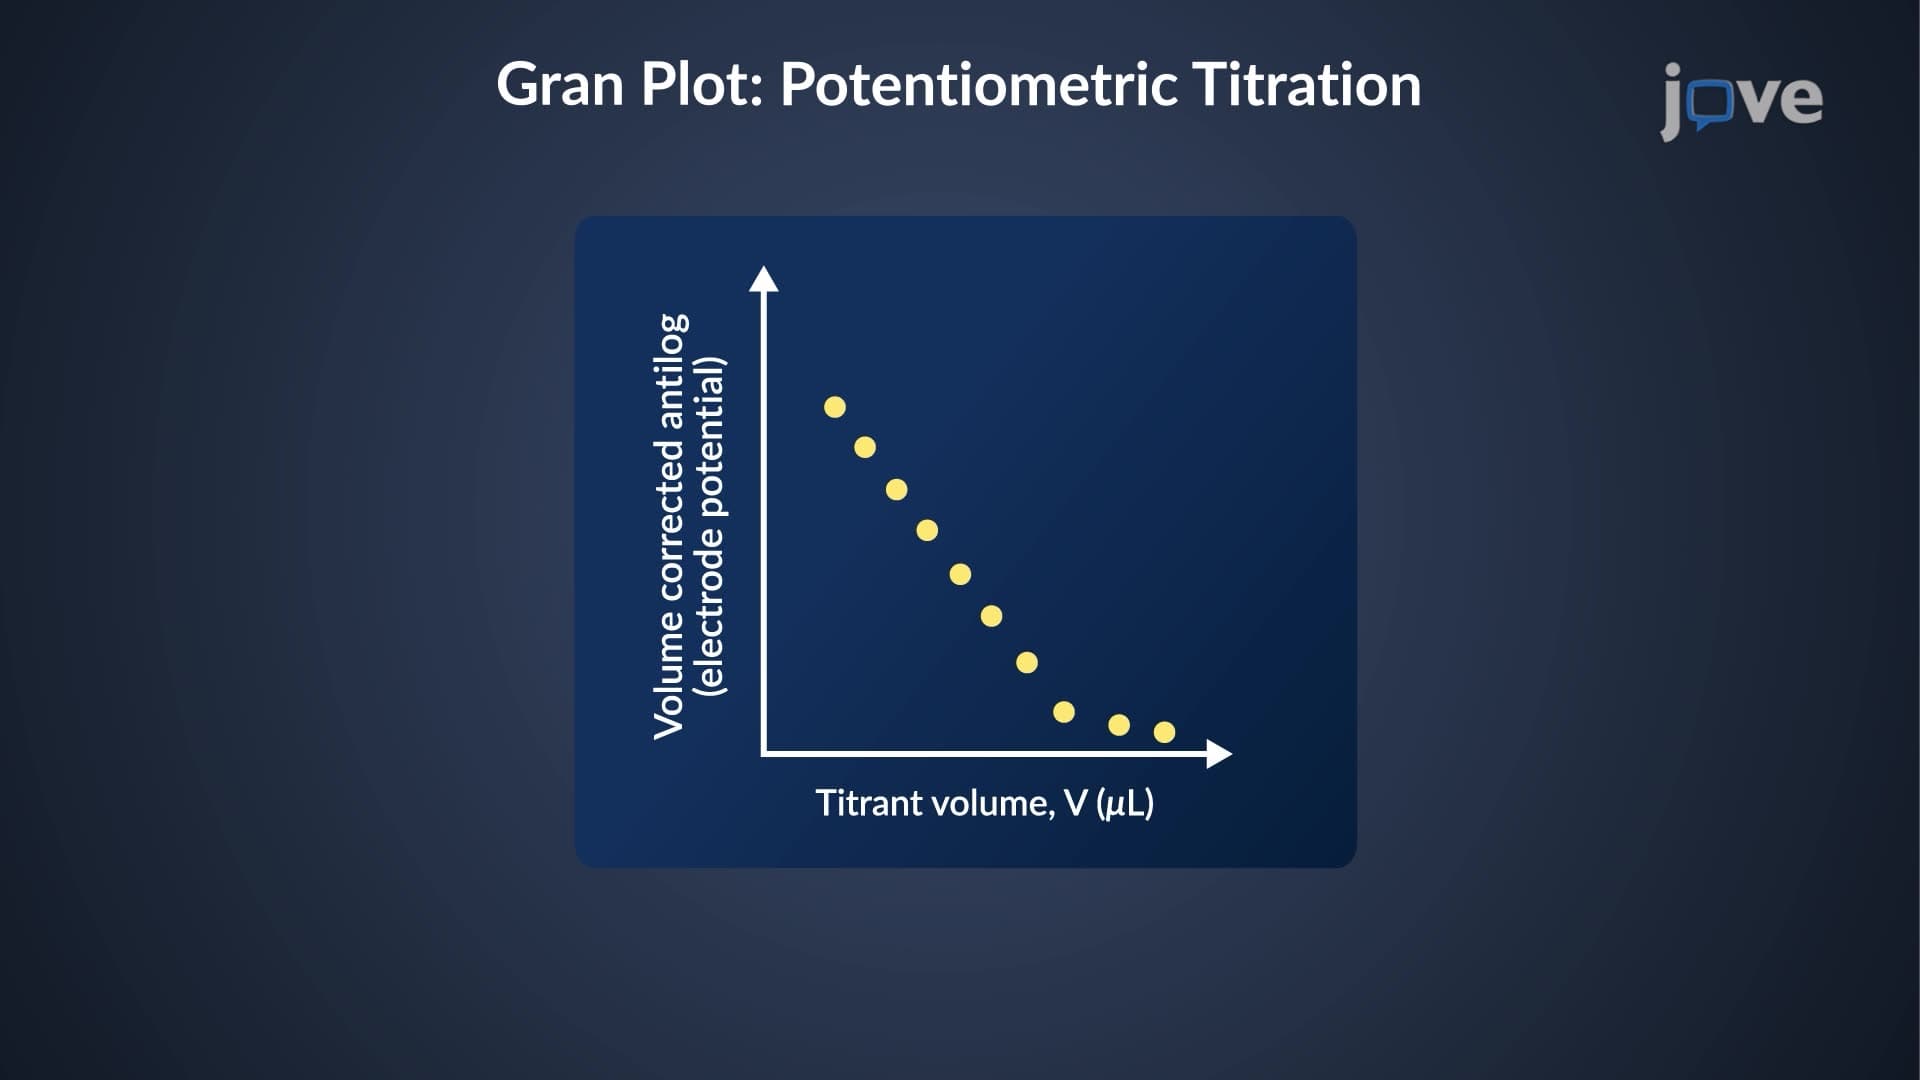
End Point Prediction: Gran Plot
For potentiometric titration, the Gran plot is created by plotting...
 01:13
Sensitivity, Specificity, and Predicted Value
Sensitivity is the...
 01:11
How Data are Classified: Categorical Data
Data are classified based on whether they are measurable or not. Categorical data cannot be measured; instead, it can be divided into categories. For example, if Y denotes a person's party affiliation, some examples of Y include...
 00:59
How Data are Classified: Numerical Data
Quantitative data may be either discrete or continuous. All quantitative data that take on only specific numerical...