Related Experiment Video
Updated: Jan 31, 2026

A Virtual Machine Platform for Non-Computer Professionals for Using Deep Learning to Classify Biological Sequences of Metagenomic Data
Published on: September 25, 2021
Simple statistical identification and removal of contaminant sequences in marker-gene and metagenomics data
Nicole M Davis1, Diana M Proctor2,3, Susan P Holmes4
1Department of Microbiology and Immunology, Stanford University School of Medicine, Stanford, CA, 94305, USA.

Background:
The accuracy of microbial community surveys based on marker-gene and metagenomic sequencing (MGS) suffers from the presence of contaminants-DNA sequences not truly present in the sample. Contaminants come from various sources, including reagents. Appropriate laboratory practices can reduce contamination, but do not eliminate it. Here we introduce decontam ( https://github.com/benjjneb/decontam ), an open-source R package that implements a statistical classification procedure that identifies contaminants in MGS data based on two widely reproduced patterns: contaminants appear at higher frequencies in low-concentration samples and are often found in negative controls.
Results:
Decontam classified amplicon sequence variants (ASVs) in a human oral dataset consistently with prior microscopic observations of the microbial taxa inhabiting that environment and previous reports of contaminant taxa. In metagenomics and marker-gene measurements of a dilution series, decontam substantially reduced technical variation arising from different sequencing protocols. The application of decontam to two recently published datasets corroborated and extended their conclusions that little evidence existed for an indigenous placenta microbiome and that some low-frequency taxa seemingly associated with preterm birth were contaminants.
Conclusions:
Decontam improves the quality of metagenomic and marker-gene sequencing by identifying and removing contaminant DNA sequences. Decontam integrates easily with existing MGS workflows and allows researchers to generate more accurate profiles of microbial communities at little to no additional cost.
Related Concept Videos
 01:16
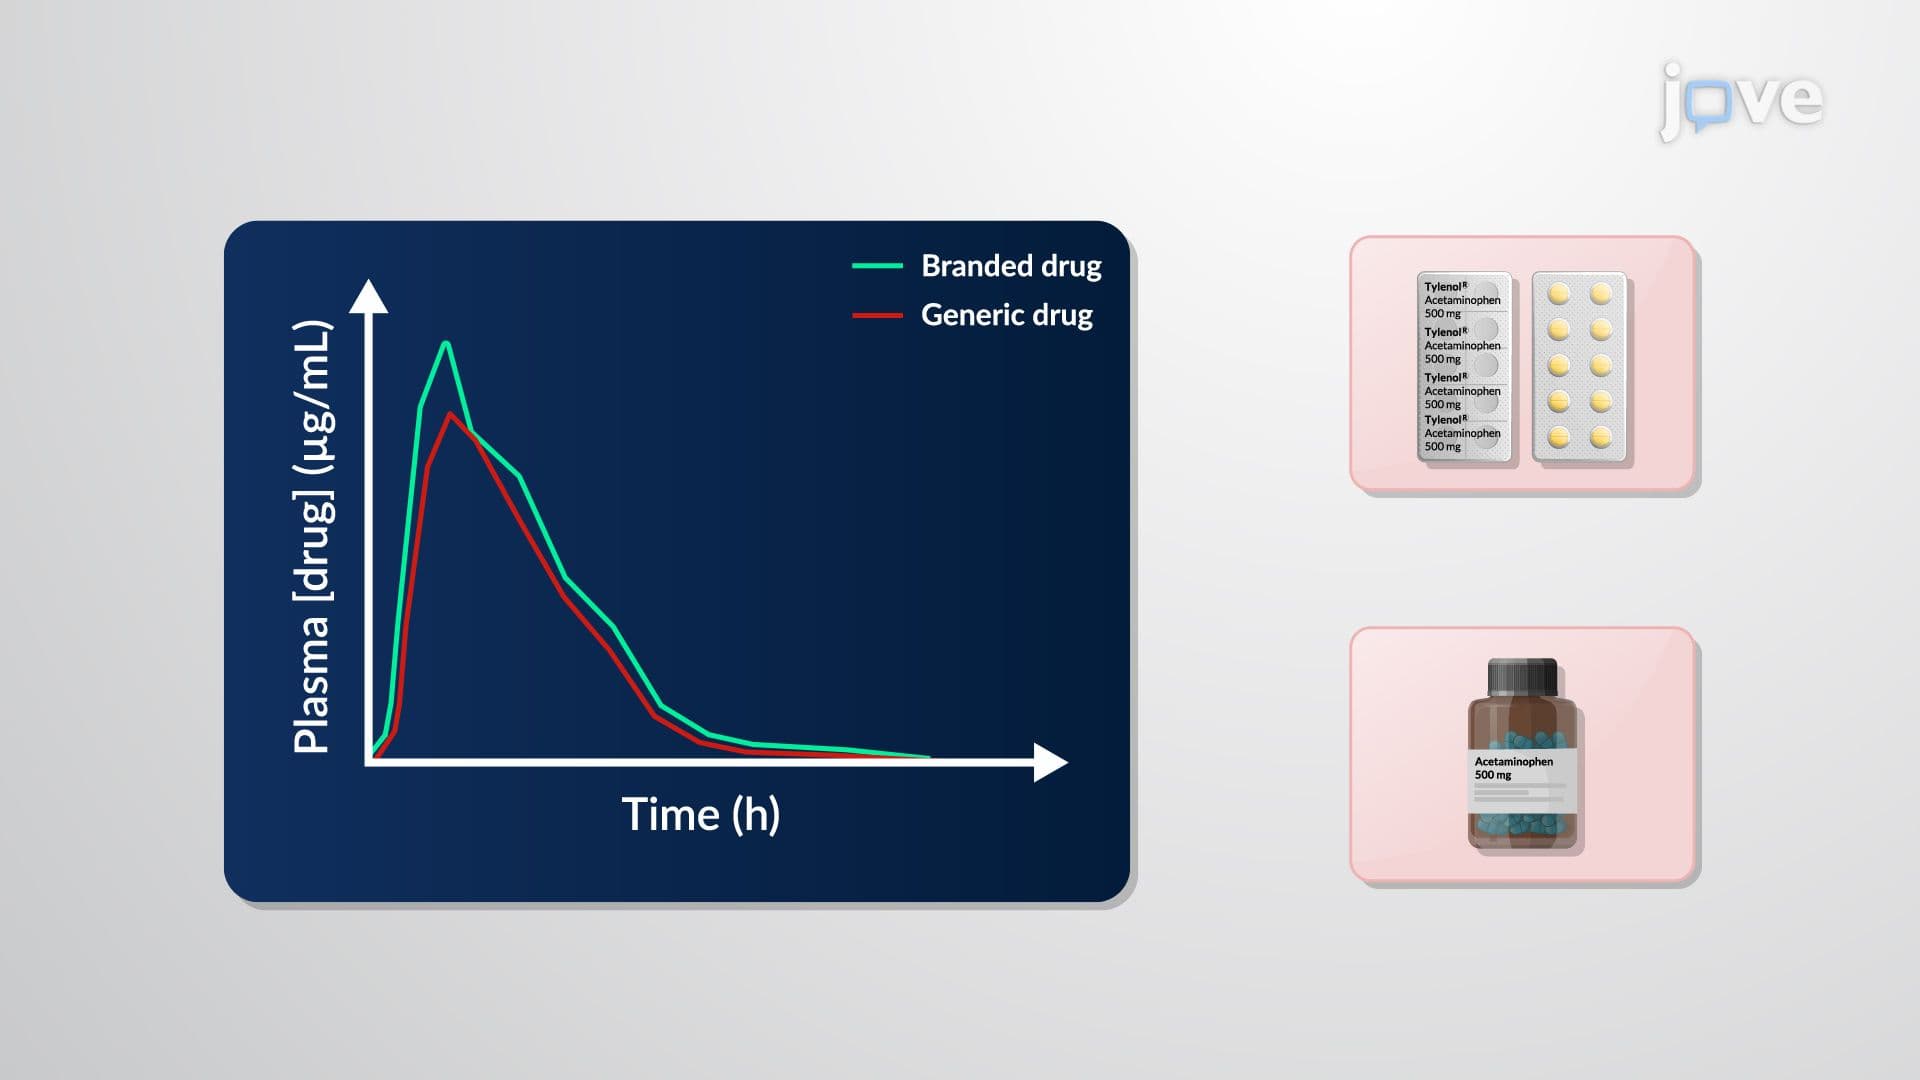
Bioequivalence Data: Statistical Interpretation
 01:25
Statistical Methods for Analyzing Epidemiological Data
 01:12
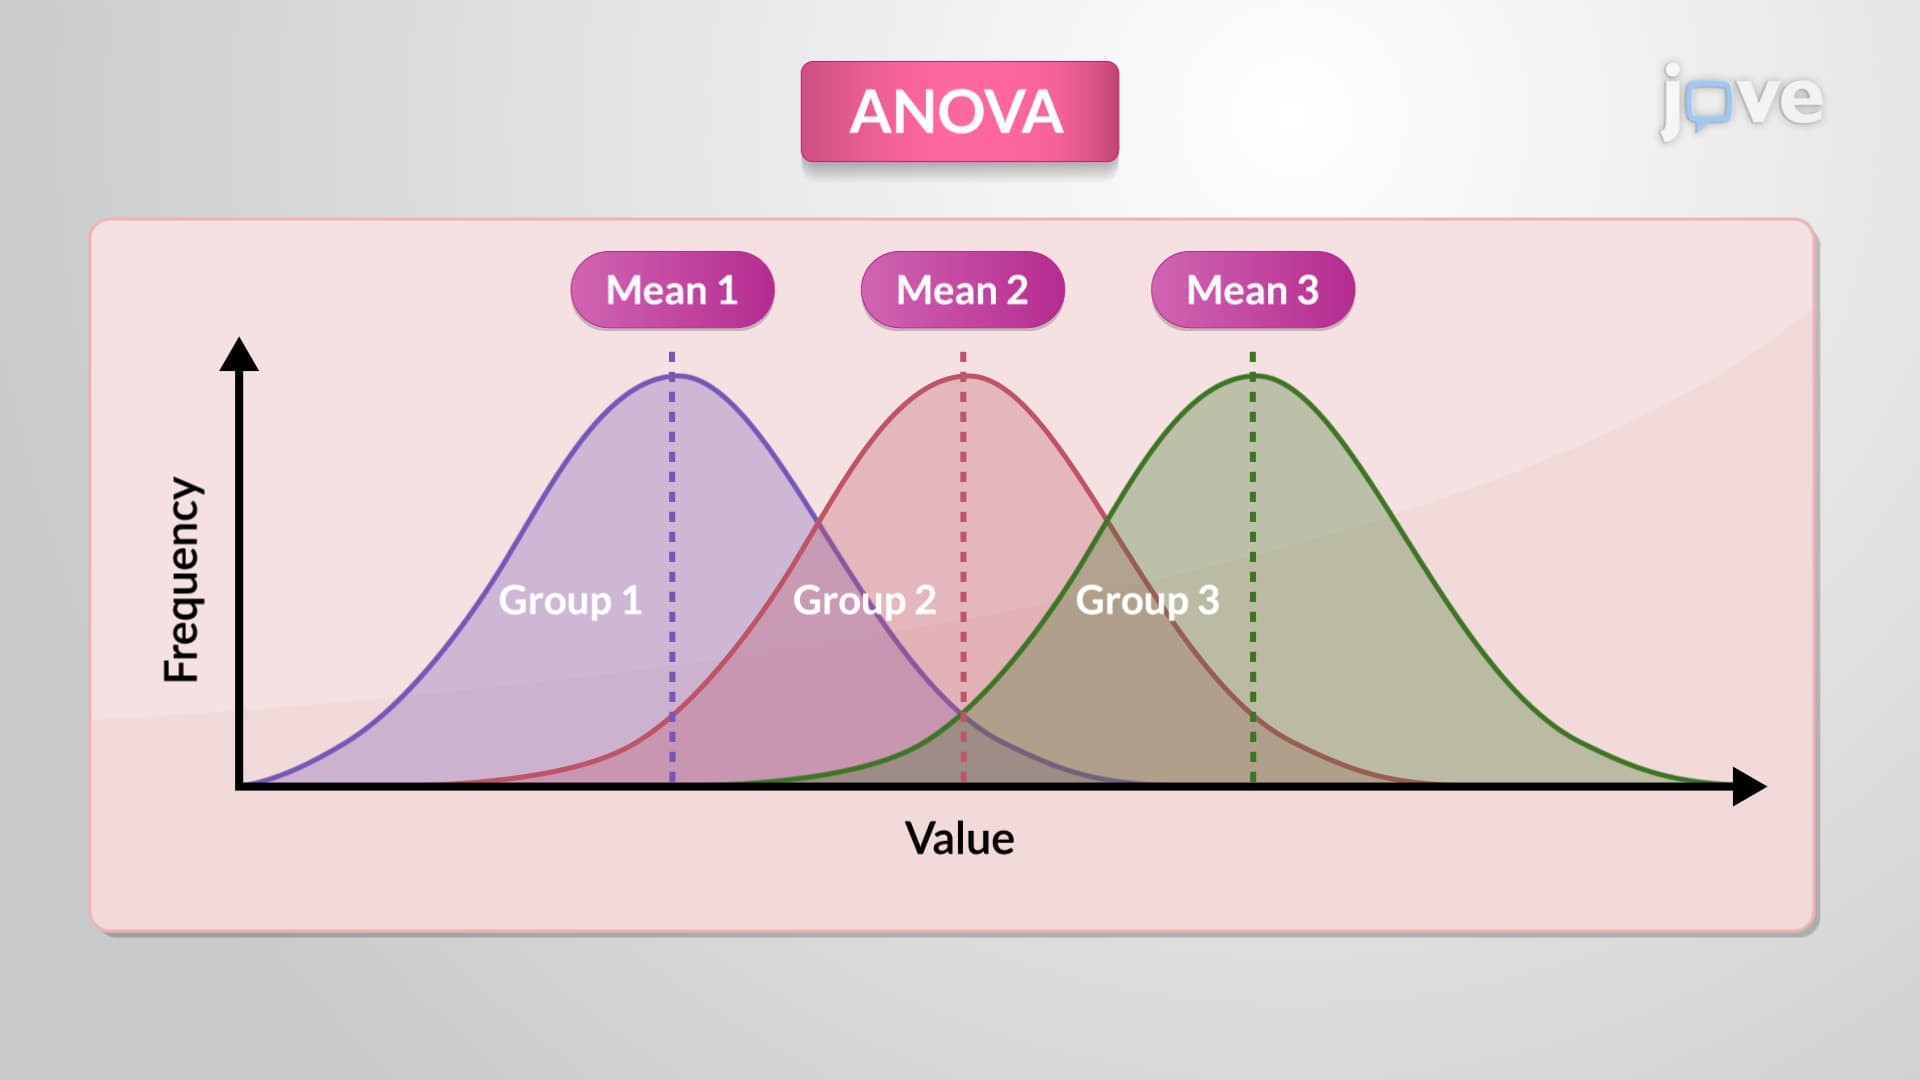
Statistical Methods to Analyze Parametric Data: ANOVA
One-way ANOVA is applied when a single independent variable or factor is scrutinized. It compares...
 01:12
Statistical Software for Data Analysis and Clinical Trials
 01:50
Statistical Significance
 01:09
Statistical Methods to Analyze Parametric Data: Student t-Test and Goodness-of-Fit Test
The Student's t-test is a statistical test that examines if there is a statistically significant difference between the means of two groups. This test is instrumental when dealing with...