Related Experiment Video
Updated: Jan 26, 2026

Using Continuous Data Tracking Technology to Study Exercise Adherence in Pulmonary Rehabilitation
Published on: November 8, 2013
Reproducible big data science: A case study in continuous FAIRness
Ravi Madduri1,2, Kyle Chard1,2, Mike D'Arcy3
1Globus, University of Chicago, Chicago, Illinois, United States of America.

Abstract:
Big biomedical data create exciting opportunities for discovery, but make it difficult to capture analyses and outputs in forms that are findable, accessible, interoperable, and reusable (FAIR). In response, we describe tools that make it easy to capture, and assign identifiers to, data and code throughout the data lifecycle. We illustrate the use of these tools via a case study involving a multi-step analysis that creates an atlas of putative transcription factor binding sites from terabytes of ENCODE DNase I hypersensitive sites sequencing data. We show how the tools automate routine but complex tasks, capture analysis algorithms in understandable and reusable forms, and harness fast networks and powerful cloud computers to process data rapidly, all without sacrificing usability or reproducibility-thus ensuring that big data are not hard-to-(re)use data. We evaluate our approach via a user study, and show that 91% of participants were able to replicate a complex analysis involving considerable data volumes.
Related Concept Videos
 01:13
Psychology as a Science
The scientific method in psychology involves six critical steps: making observations, formulating hypotheses, conducting tests, analyzing...
 01:19
Overview of Biostatistics in Health Sciences
 01:22
Statistical Package for the Social Sciences (SPSS)
SPSS streamlines the process from data preparation to analysis and reporting. It is characterized by its user-friendly interface, which conceals...
 01:25
Continuing Care
 01:28
Continuity Equation
The mass flow rate is expressed as:
 01:20
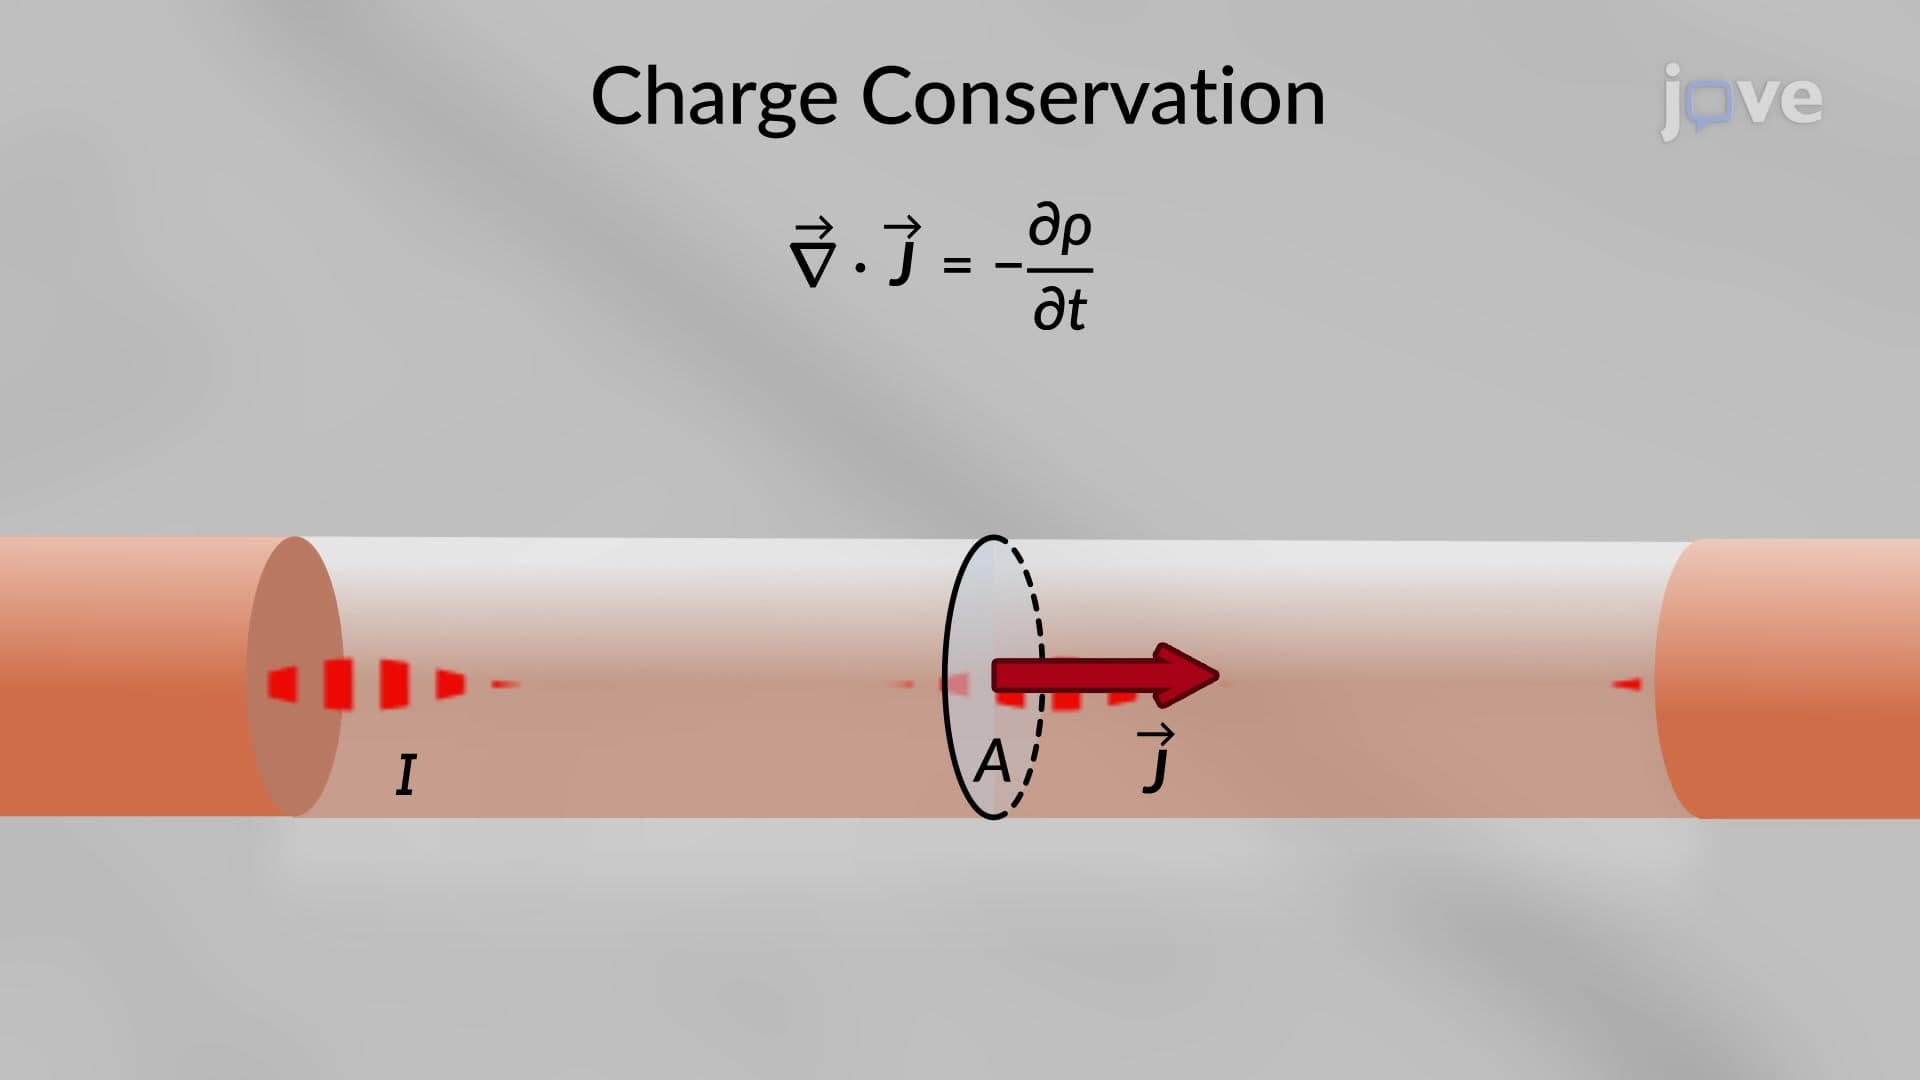
Continuity Equation