Prediction analysis for microbiome sequencing data
Related Experiment Video
Updated: Jan 26, 2026
Tick Microbiome Characterization by Next-Generation 16S rRNA Amplicon Sequencing
Published on: August 25, 2018
Tao Wang1,2,3, Can Yang4, Hongyu Zhao3,5
1Department of Bioinformatics and Biostatistics, Shanghai Jiao Tong University, Shanghai, China.

Abstract:
One goal of human microbiome studies is to relate host traits with human microbiome compositions. The analysis of microbial community sequencing data presents great statistical challenges, especially when the samples have different library sizes and the data are overdispersed with many zeros. To address these challenges, we introduce a new statistical framework, called predictive analysis in metagenomics via inverse regression (PAMIR), to analyze microbiome sequencing data. Within this framework, an inverse regression model is developed for overdispersed microbiota counts given the trait, and then a prediction rule is constructed by taking advantage of the dimension-reduction structure in the model. An efficient Monte Carlo expectation-maximization algorithm is proposed for maximum likelihood estimation. The method is further generalized to accommodate other types of covariates. We demonstrate the advantages of PAMIR through simulations and two real data examples.
More Related Videos
Related Concept Videos
 01:12
Analysis of Population Pharmacokinetic Data
 02:27
Predicting Molecular Geometry
 01:13
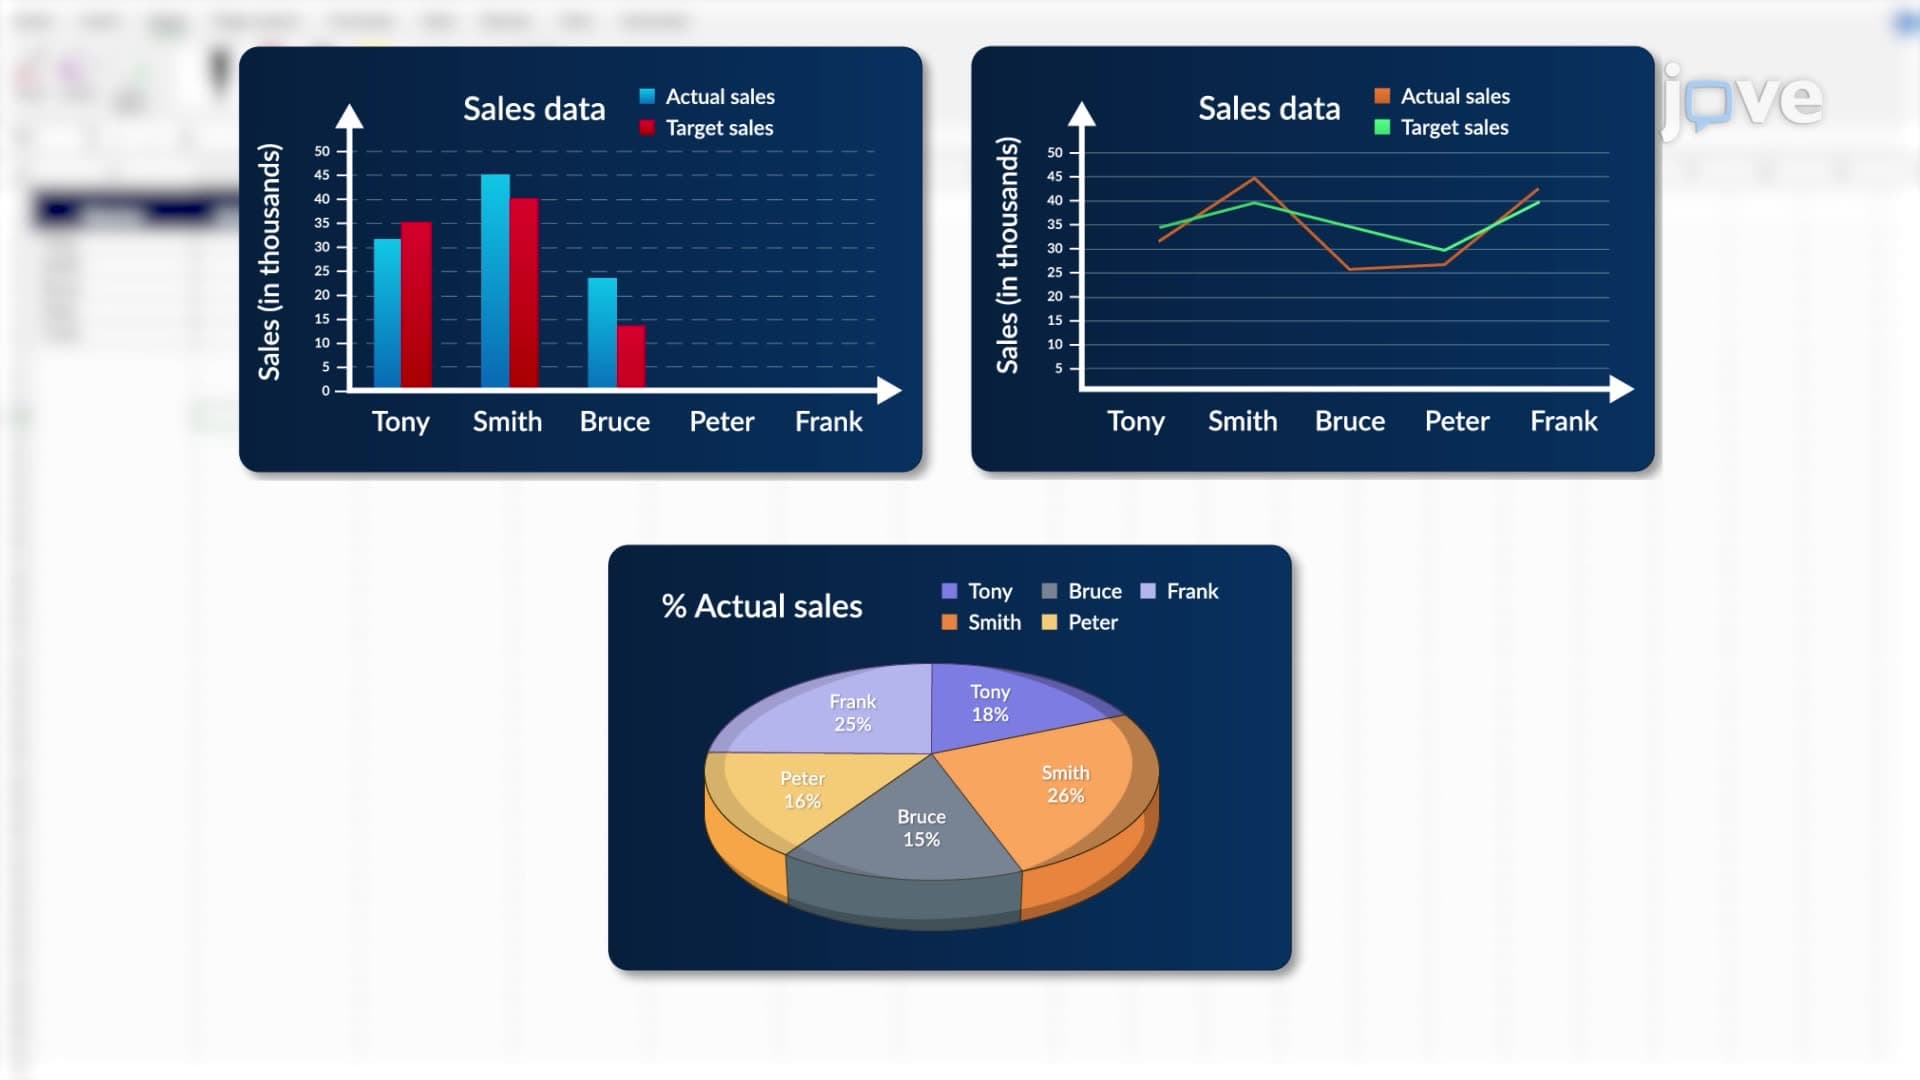
Overview of Microsoft Excel as a Data Analysis Tool
 01:12
Statistical Software for Data Analysis and Clinical Trials
 01:17
Performing a Simple Data Analysis using MS-Excel Function
SUM: This function calculates the total sum of a range of values. It's the foundation for aggregating data, essential for determining overall trends and totals in datasets.
AVERAGE: It computes the mean value of a given set of numbers, providing a quick insight into the central...
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.