Related Experiment Video
Updated: Jan 26, 2026

Novel Sequence Discovery by Subtractive Genomics
Published on: January 25, 2019
Analyzing big datasets of genomic sequences: fast and scalable collection of k-mer statistics
Umberto Ferraro Petrillo1, Mara Sorella2, Giuseppe Cattaneo3
1Dipartimento di Scienze Statistiche, Università di Roma - La Sapienza, Rome, 00185, Italy.

Background:
Distributed approaches based on the MapReduce programming paradigm have started to be proposed in the Bioinformatics domain, due to the large amount of data produced by the next-generation sequencing techniques. However, the use of MapReduce and related Big Data technologies and frameworks (e.g., Apache Hadoop and Spark) does not necessarily produce satisfactory results, in terms of both efficiency and effectiveness. We discuss how the development of distributed and Big Data management technologies has affected the analysis of large datasets of biological sequences. Moreover, we show how the choice of different parameter configurations and the careful engineering of the software with respect to the specific framework under consideration may be crucial in order to achieve good performance, especially on very large amounts of data. We choose k-mers counting as a case study for our analysis, and Spark as the framework to implement FastKmer, a novel approach for the extraction of k-mer statistics from large collection of biological sequences, with arbitrary values of k.
Results:
One of the most relevant contributions of FastKmer is the introduction of a module for balancing the statistics aggregation workload over the nodes of a computing cluster, in order to overcome data skew while allowing for a full exploitation of the underlying distributed architecture. We also present the results of a comparative experimental analysis showing that our approach is currently the fastest among the ones based on Big Data technologies, while exhibiting a very good scalability.
Conclusions:
We provide evidence that the usage of technologies such as Hadoop or Spark for the analysis of big datasets of biological sequences is productive only if the architectural details and the peculiar aspects of the considered framework are carefully taken into account for the algorithm design and implementation.
Related Concept Videos
 01:25
Statistical Methods for Analyzing Epidemiological Data
 01:12
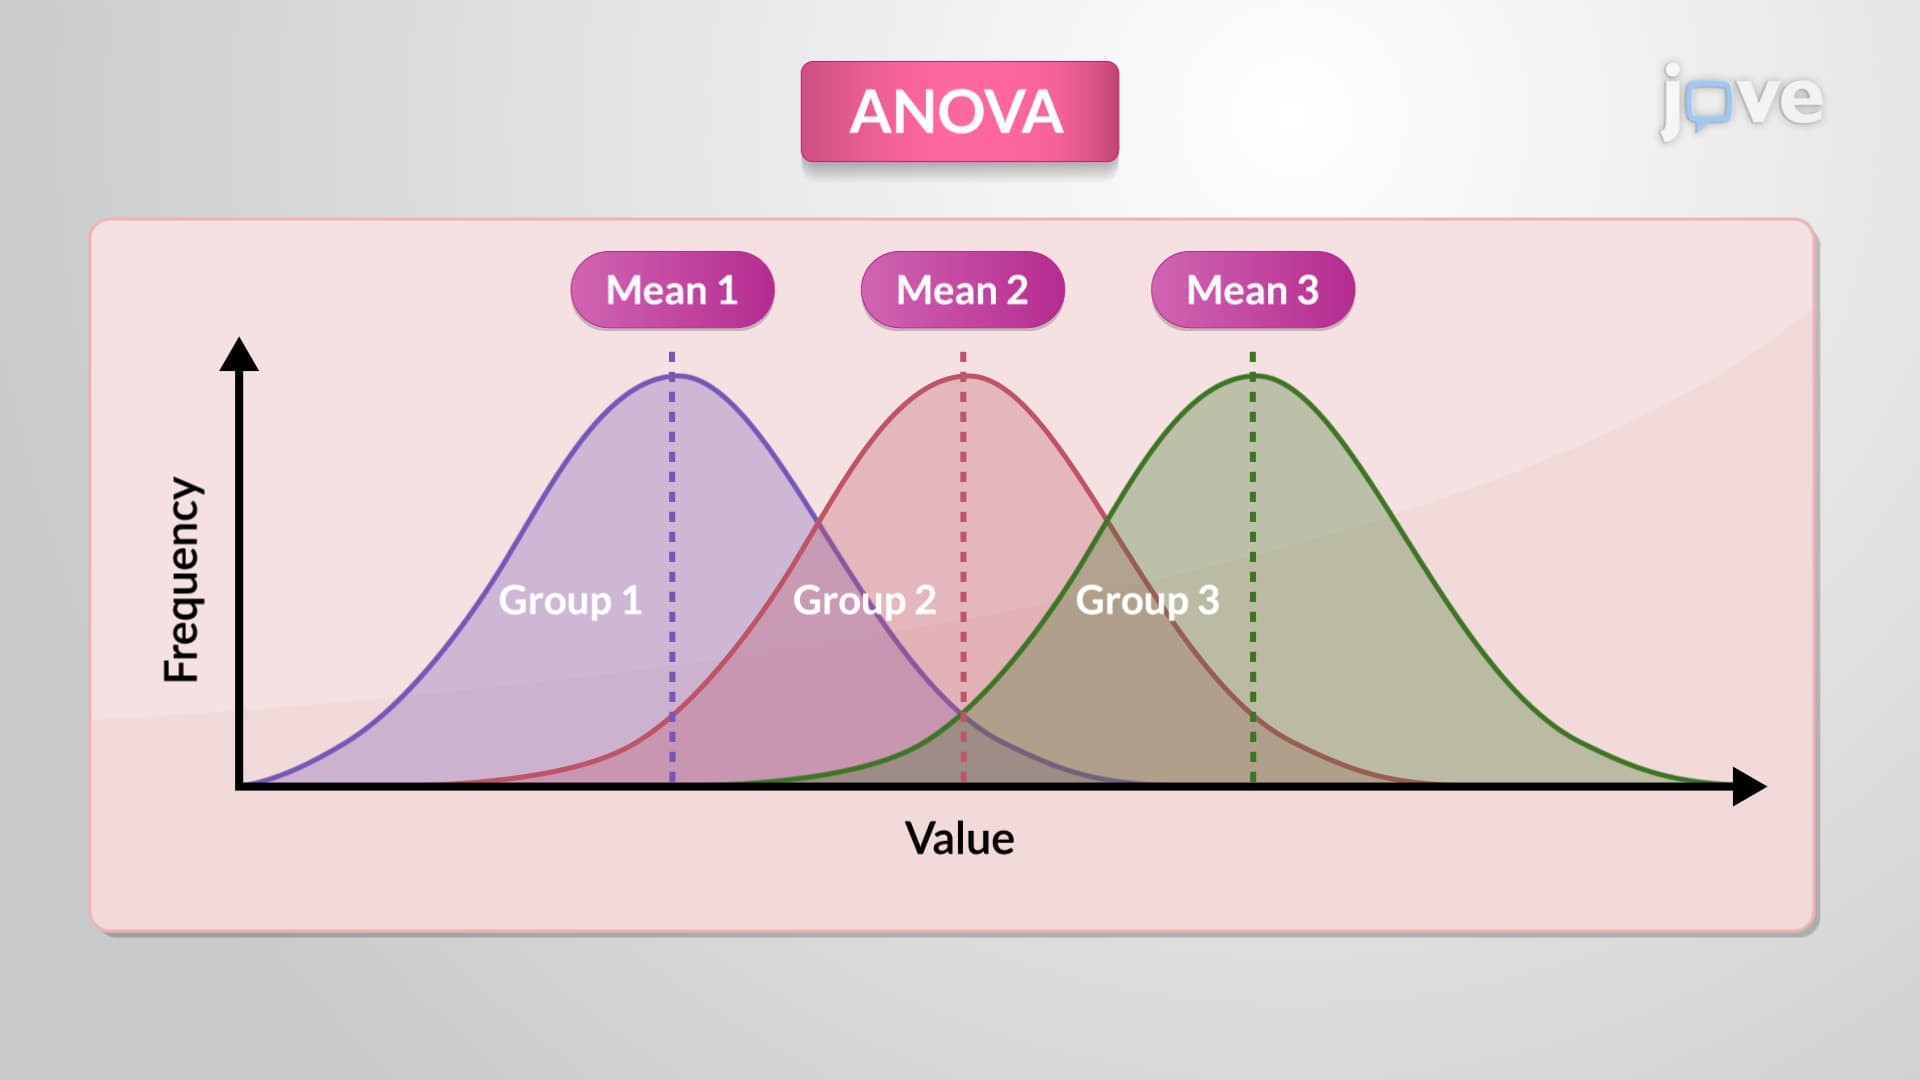
Statistical Methods to Analyze Parametric Data: ANOVA
One-way ANOVA is applied when a single independent variable or factor is scrutinized. It compares...
 01:50
Statistical Significance
 02:02
Genomics
 01:09
Statistical Methods to Analyze Parametric Data: Student t-Test and Goodness-of-Fit Test
The Student's t-test is a statistical test that examines if there is a statistically significant difference between the means of two groups. This test is instrumental when dealing with...
 03:21
Genome Size and the Evolution of New Genes