Related Experiment Video
Updated: Jan 24, 2026
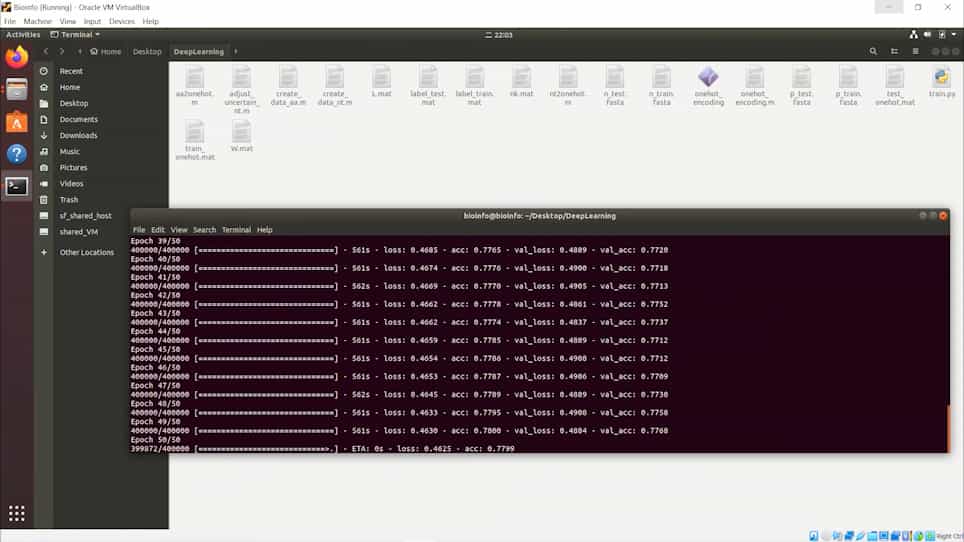

A Virtual Machine Platform for Non-Computer Professionals for Using Deep Learning to Classify Biological Sequences of Metagenomic Data
Published on: September 25, 2021
MLSeq: Machine learning interface for RNA-sequencing data
Dincer Goksuluk1, Gokmen Zararsiz2, Selcuk Korkmaz3
1Department of Biostatistics, School of Medicine, Hacettepe University, 06100, Ankara, Turkey; Turcosa Analytics Solutions Ltd. Co., Erciyes Teknopark 5, 38030, Kayseri, Turkey.

Background And Objective:
In the last decade, RNA-sequencing technology has become method-of-choice and prefered to microarray technology for gene expression based classification and differential expression analysis since it produces less noisy data. Although there are many algorithms proposed for microarray data, the number of available algorithms and programs are limited for classification of RNA-sequencing data. For this reason, we developed MLSeq, to bring not only frequently used classification algorithms but also novel approaches together and make them available to be used for classification of RNA sequencing data. This package is developed using R language environment and distributed through BIOCONDUCTOR network.
Methods:
Classification of RNA-sequencing data is not straightforward since raw data should be preprocessed before downstream analysis. With MLSeq package, researchers can easily preprocess (normalization, filtering, transformation etc.) and classify raw RNA-sequencing data using two strategies: (i) to perform algorithms which are directly proposed for RNA-sequencing data structure or (ii) to transform RNA-sequencing data in order to bring it distributionally closer to microarray data structure, and perform algorithms which are developed for microarray data. Moreover, we proposed novel algorithms such as voom (an acronym for variance modelling at observational level) based nearest shrunken centroids (voomNSC), diagonal linear discriminant analysis (voomDLDA), etc. through MLSeq.
Materials:
Three real RNA-sequencing datasets (i.e cervical cancer, lung cancer and aging datasets) were used to evalute model performances. Poisson linear discriminant analysis (PLDA) and negative binomial linear discriminant analysis (NBLDA) were selected as algorithms based on dicrete distributions, and voomNSC, nearest shrunken centroids (NSC) and support vector machines (SVM) were selected as algorithms based on continuous distributions for model comparisons. Each algorithm is compared using classification accuracies and sparsities on an independent test set.
Results:
The algorithms which are based on discrete distributions performed better in cervical cancer and aging data with accuracies above 0.92. In lung cancer data, the most of algorithms performed similar with accuracies of 0.88 except that SVM achieved 0.94 of accuracy. Our voomNSC algorithm was the most sparse algorithm, and able to select 2.2% and 6.6% of all features for cervical cancer and lung cancer datasets respectively. However, in aging data, sparse classifiers were not able to select an optimal subset of all features.
Conclusion:
MLSeq is comprehensive and easy-to-use interface for classification of gene expression data. It allows researchers perform both preprocessing and classification tasks through single platform. With this property, MLSeq can be considered as a pipeline for the classification of RNA-sequencing data.
Related Concept Videos
 01:24
Sequence Networks of Rotating Machines
Zero-sequence current induces a voltage drop across the generator's neutral impedance and other...
 02:04
Protein-protein Interfaces
 01:32
RNA Splicing
 01:19
Machines
A free-body diagram of the...
 01:23
RNA Interference
This process occurs naturally in cells, often through the activity of genomically-encoded microRNAs. Researchers can take advantage of this mechanism by introducing synthetic RNAs to deactivate specific genes for research or therapeutic purposes. For example, RNAi could be used...
 01:53
RNA Stability