Related Experiment Video
Updated: Jan 23, 2026


In Vivo Modeling of the Morbid Human Genome using Danio rerio
Published on: August 24, 2013
Statistical representation models for mutation information within genomic data
N Özlem Özcan Şimşek1, Arzucan Özgür2, Fikret Gürgen3
1Department of Computer Engineering, Boğaziçi University, İstanbul, Turkey.

Background:
As DNA sequencing technologies are improving and getting cheaper, genomic data can be utilized for diagnosis of many diseases such as cancer. Human raw genome data is huge in size for computational systems. Therefore, there is a need for a compact and accurate representation of the valuable information in DNA. The occurrence of complex genetic disorders often results from multiple gene mutations. The effect of each mutation is not equal for the development of a disease. Inspired from the field of information retrieval, we propose using the term frequency (tf) and BM25 term weighting measures with the inverse document frequency (idf) and relevance frequency (rf) measures to weight genes based on their mutations. The underlying assumption is that the more mutations a gene has in patients with a certain disease and the less mutations it has in other patients, the more discriminative that gene is.
Results:
We evaluated the proposed representations on the task of cancer type classification. We applied various machine learning techniques using the tf-idf and tf-rf schemes and their BM25 versions. Our results show that the BM25-tf-rf representation leads to improved classification accuracy and f-score values compared to the other representations. The highest accuracy (76.44%) and f-score (76.95%) are achieved with the BM25-tf-rf based data representation.
Conclusions:
As a result of our experiments, the BM25-tf-rf scheme and the proposed neural network model is shown to be the best performing classification system for our case study of cancer type classification. This system is further utilized for causal gene analysis. Examples from the most effective genes that are used for decision making are found to be in the literature as target or causal genes.
Related Concept Videos
 01:16
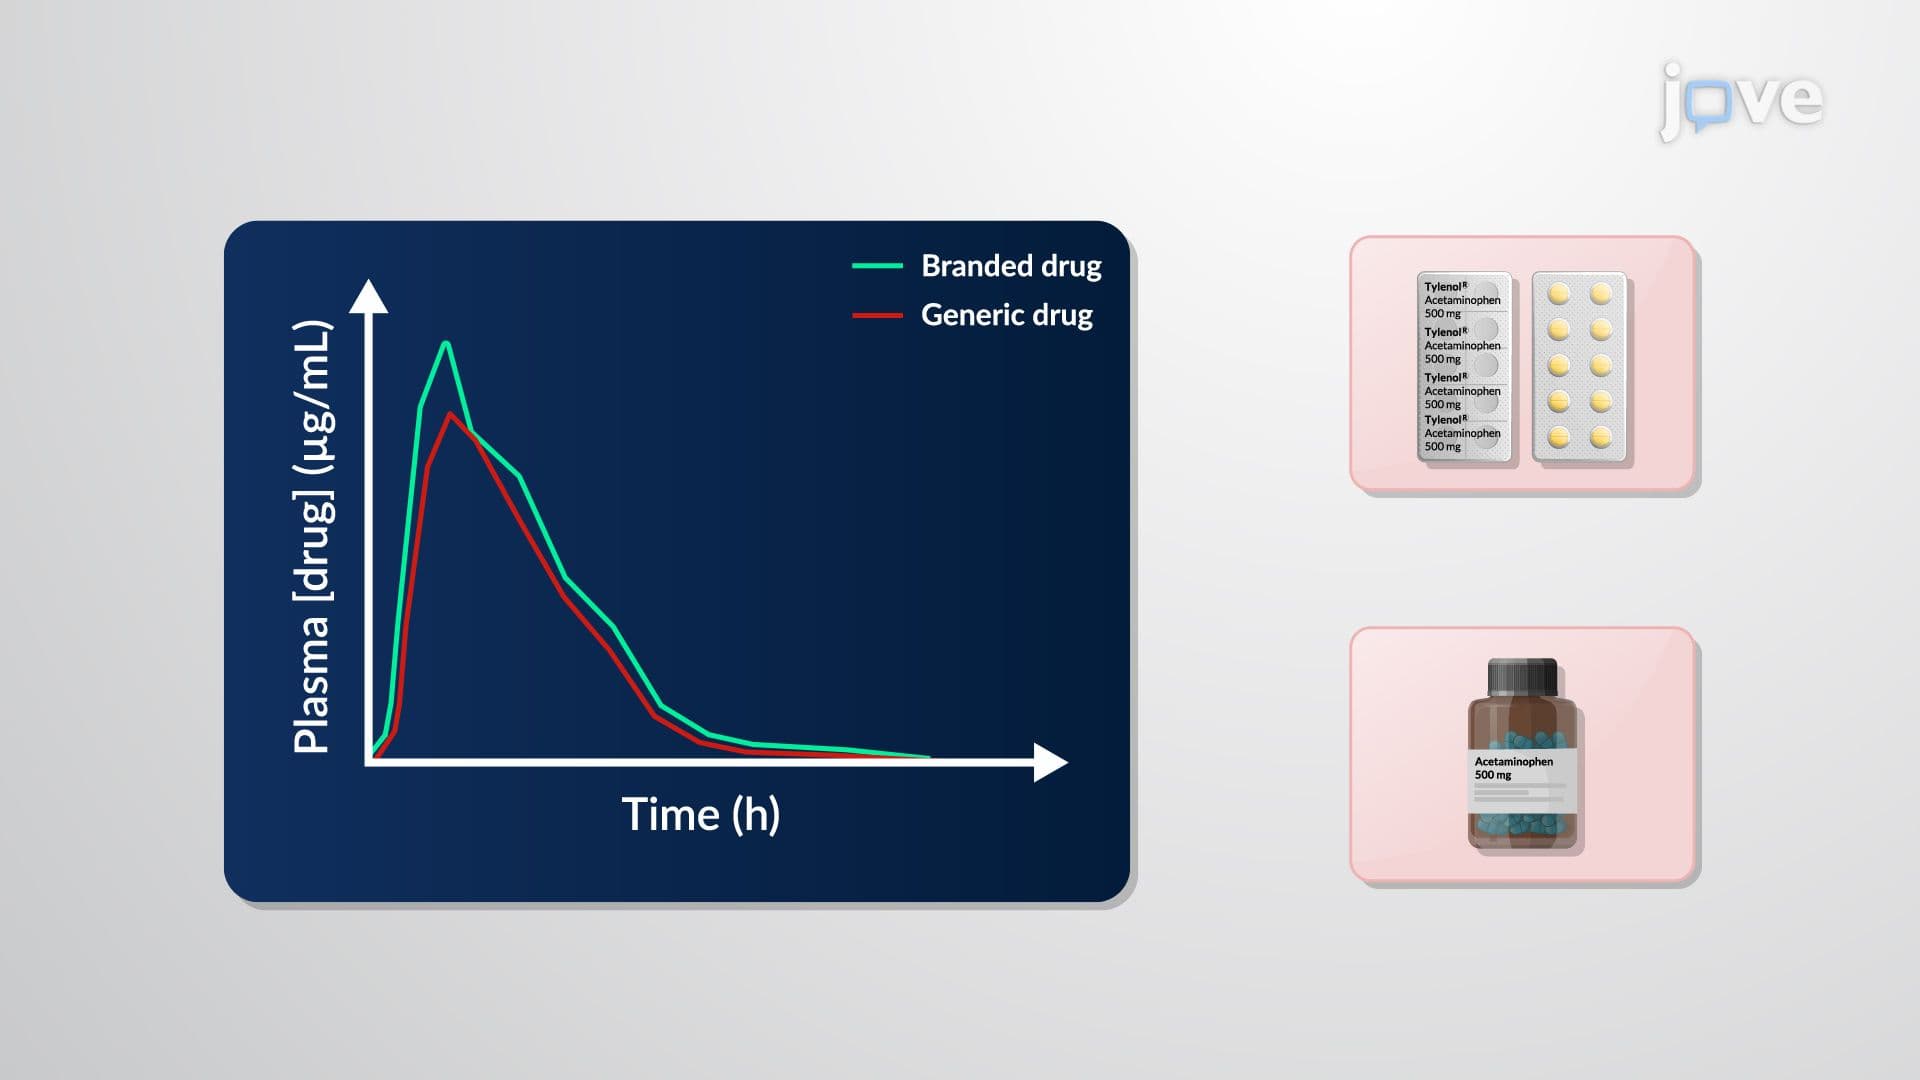
Bioequivalence Data: Statistical Interpretation
 01:25
Statistical Methods for Analyzing Epidemiological Data
 01:12
Statistical Software for Data Analysis and Clinical Trials
 01:12
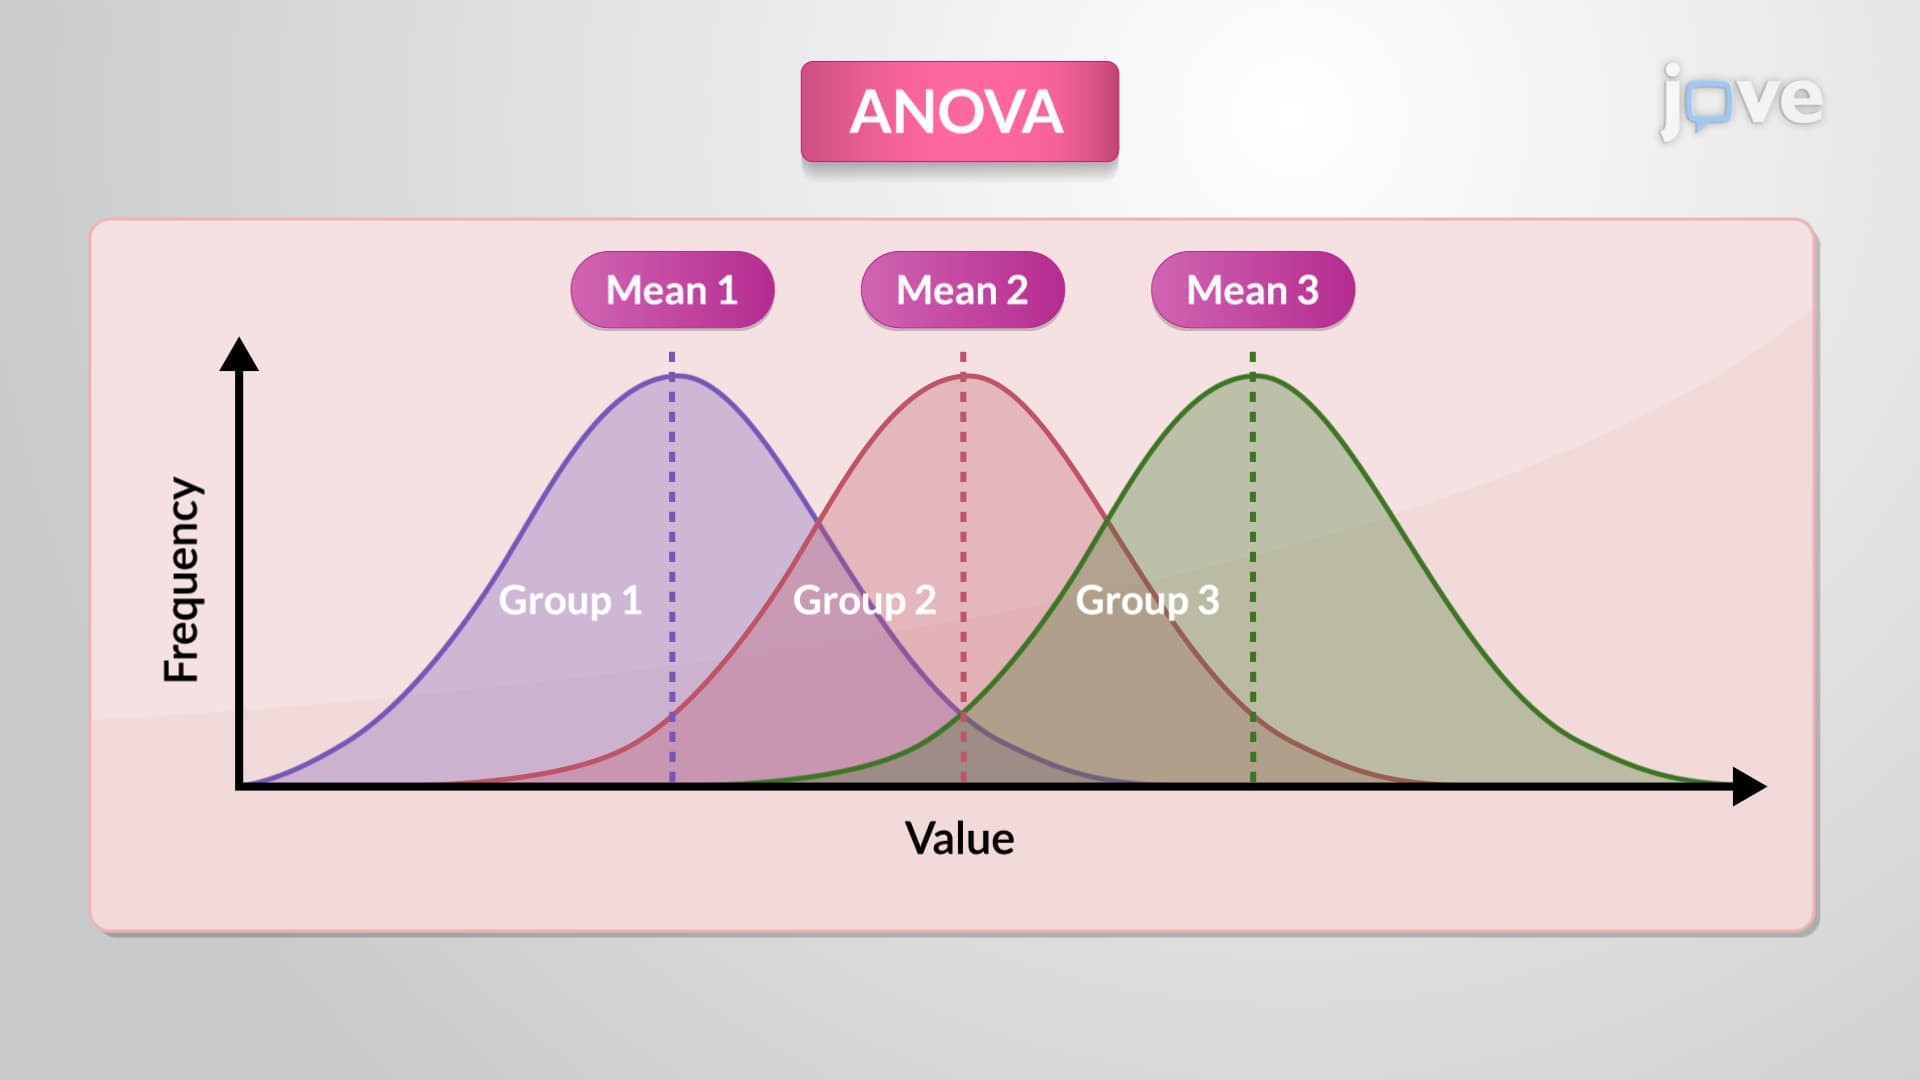
Statistical Methods to Analyze Parametric Data: ANOVA
One-way ANOVA is applied when a single independent variable or factor is scrutinized. It compares...
 01:50
Statistical Significance
 01:39
Mutations