Related Experiment Video
Updated: Jan 21, 2026
Project-Based Learning Guidelines for Health Sciences Students: An Analysis with Data Mining and Qualitative Techniques
Published on: December 9, 2022
Studies in the use of data mining, prediction algorithms, and a universal exchange and inference language in the
1Ingine Inc. Virginia, USA and the Dirac Foundation OxfordShire, UK.

Abstract:
While clinical and biomedical information in digital form has been escalating, it is socioeconomic factors that are important determinants of health on the national and global scale. We show how collective use of data mining and prediction algorithms to analyze socioeconomic population health data can stand beside classical correlation analysis in routine data analysis. The underlying theoretical basis is the Dirac notation and algebra that is a scientific standard but unusual outside of the physical sciences, combined with a theory of expected information first developed for analyzing sparse data but still largely confined to bioinformatics. The latter was important here because the records analyzed (which are for US counties and equivalents, not patients) are very few by contemporary data mining standards. The approach is very unlikely to be familiar to socioeconomic researchers, so the theory and the advantages of our inference nets over the Bayes Net are reviewed here, mostly using socioeconomic examples. While our expertise and focus is in regard to novel analytical methods rather than socioeconomics per se, a significant negative (countertrending) relationship between population health and equity was initially surprising, at least to the present authors. This encouraged deeper exploration including that of the relationship between our data mining methods and traditional Pearson's correlation. The latter is susceptible to giving wrong conclusions if a phenomenon called Simpson's paradox applies, so this is also investigated. Also discussed is that, even for very few records, associative data mining can still demand significant computational resources due to a combinatorial explosion.
More Related Videos
 10:43
Eye-tracking Technology and Data-mining Techniques used for a Behavioral Analysis of Adults engaged in Learning Processes
Published on: June 10, 2021
 07:41
Performing Data Mining And Integrative Analysis Of Biomarker in Breast Cancer Using Multiple Publicly Accessible Databases
Published on: May 17, 2019
Related Concept Videos
 01:24
Data Reporting and Recording
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...
 01:12
Analysis of Population Pharmacokinetic Data
 00:59
How Data are Classified: Numerical Data
Quantitative data may be either discrete or continuous. All quantitative data that take on only specific numerical...
 01:11
How Data are Classified: Categorical Data
Data are classified based on whether they are measurable or not. Categorical data cannot be measured; instead, it can be divided into categories. For example, if Y denotes a person's party affiliation, some examples of Y include...
 01:13
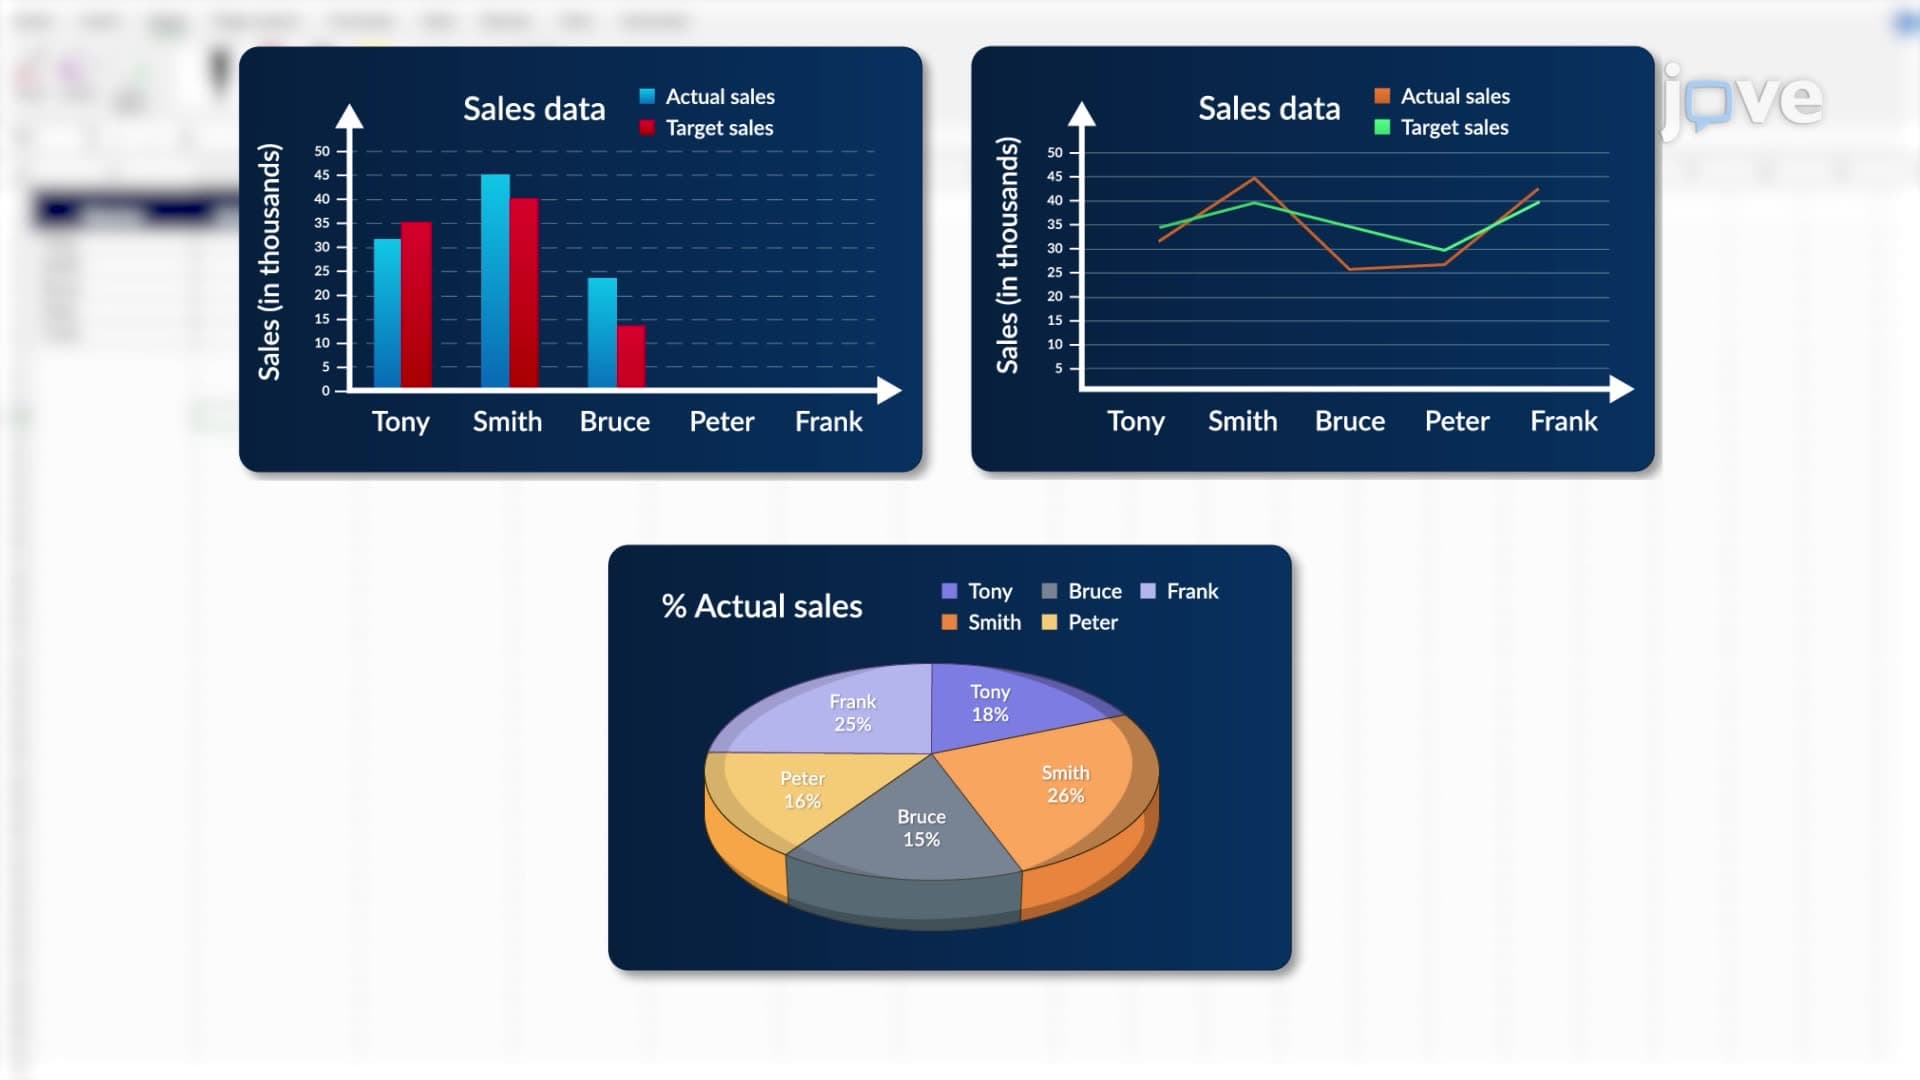
Overview of Microsoft Excel as a Data Analysis Tool