Related Experiment Video
Updated: Jan 5, 2026
Inverse Probability of Treatment Weighting Propensity Score using the Military Health System Data Repository and National Death Index
Published on: January 8, 2020
Big data, observational research and P-value: a recipe for false-positive findings? A study of simulated and real
Giovanni Veronesi1, Guido Grassi2, Giordano Savelli3
1Research Center in Epidemiology and Preventive Medicine, Department of Medicine and Surgery, University of Insubria, Varese, Italy.

Background:
An increasing number of observational studies combine large sample sizes with low participation rates, which could lead to standard inference failing to control the false-discovery rate. We investigated if the 'empirical calibration of P-value' method (EPCV), reliant on negative controls, can preserve type I error in the context of survival analysis.
Methods:
We used simulated cohort studies with 50% participation rate and two different selection bias mechanisms, and a real-life application on predictors of cancer mortality using data from four population-based cohorts in Northern Italy (n = 6976 men and women aged 25-74 years at baseline and 17 years of median follow-up).
Results:
Type I error for the standard Cox model was above the 5% nominal level in 15 out of 16 simulated settings; for n = 10 000, the chances of a null association with hazard ratio = 1.05 having a P-value < 0.05 were 42.5%. Conversely, EPCV with 10 negative controls preserved the 5% nominal level in all the simulation settings, reducing bias in the point estimate by 80-90% when its main assumption was verified. In the real case, 15 out of 21 (71%) blood markers with no association with cancer mortality according to literature had a P-value < 0.05 in age- and gender-adjusted Cox models. After calibration, only 1 (4.8%) remained statistically significant.
Conclusions:
In the analyses of large observational studies prone to selection bias, the use of empirical distribution to calibrate P-values can substantially reduce the number of trivial results needing further screening for relevance and external validity.

Related Concept Videos
 01:09
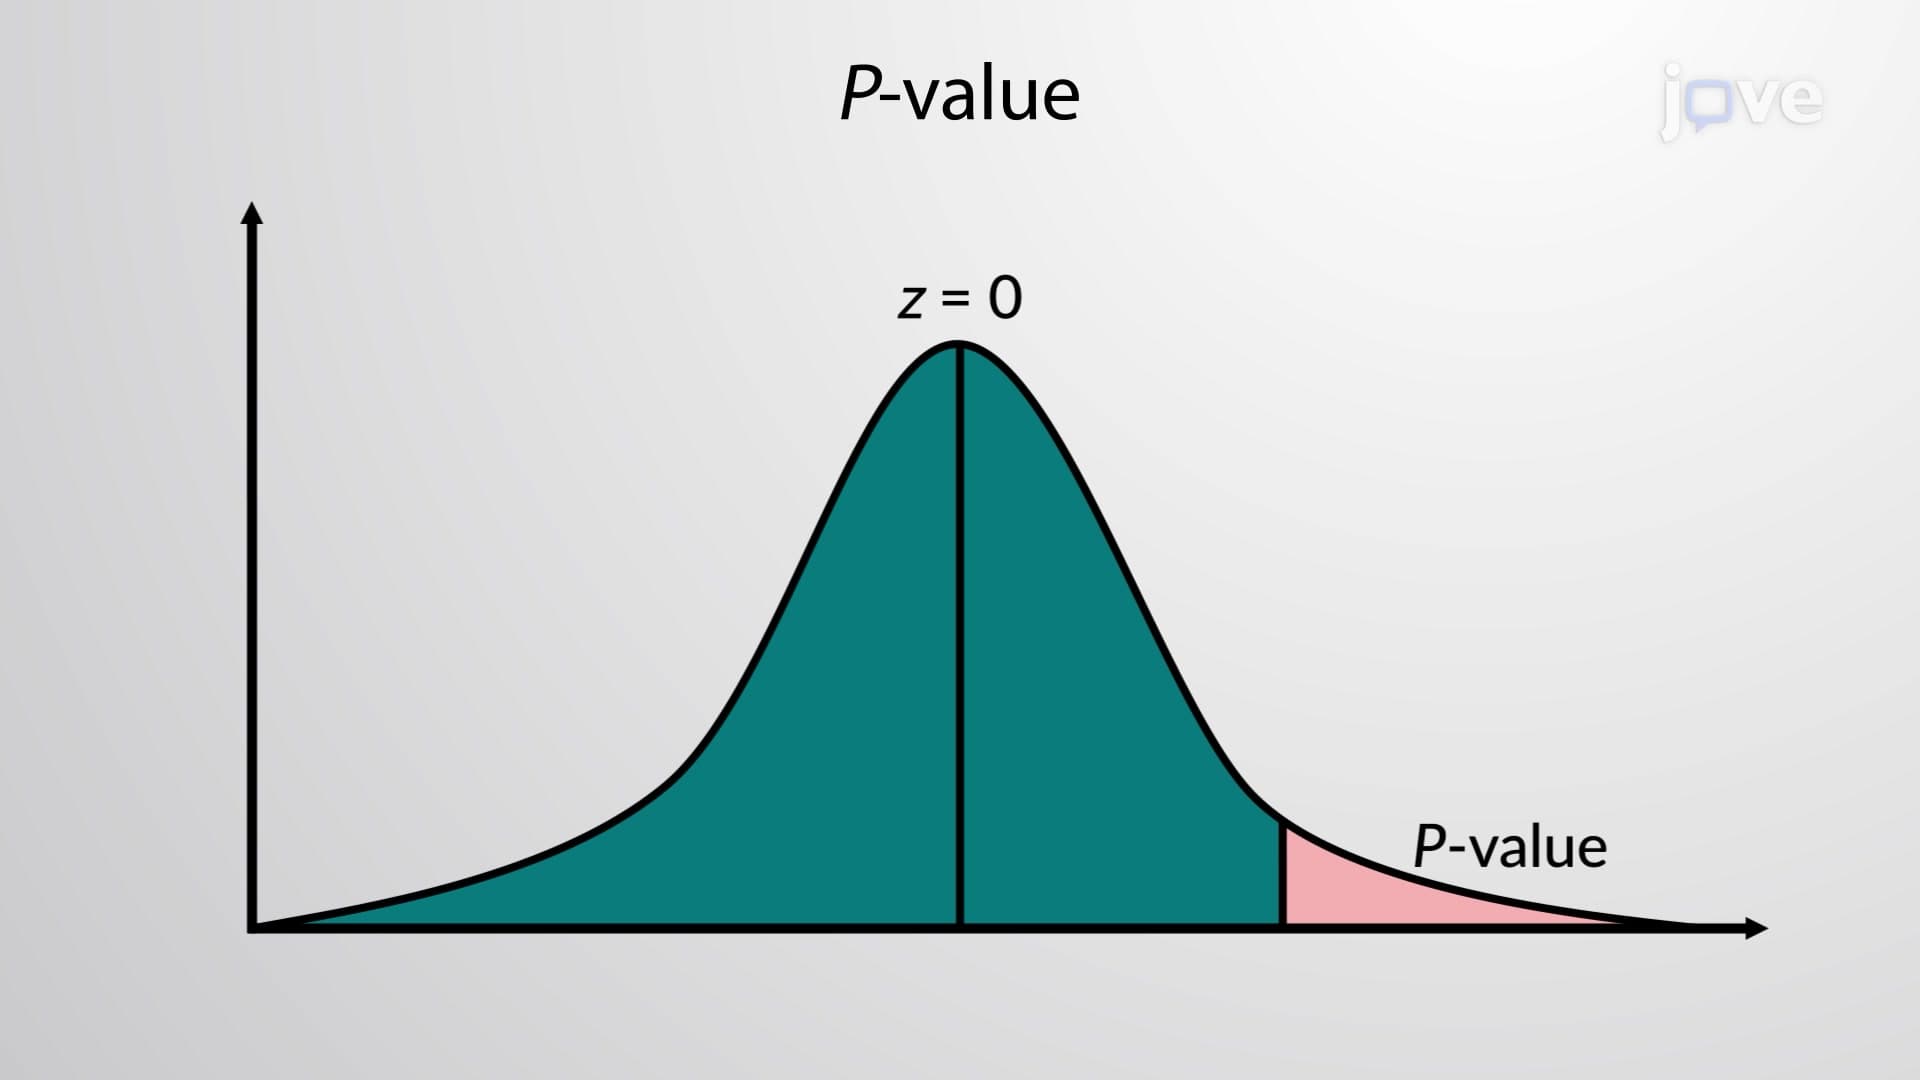
Decision Making: P-value Method
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
 01:24
Testing a Claim about Population Proportion
There are two methods of testing a claim about a population proportion: (1) Using the sample proportion from the data where a binomial distribution is approximated to the normal distribution and (2) Using the binomial probabilities calculated from the data.
The first method uses normal distribution as an approximation to the binomial distribution. The requirements are as follows: sample size is large...
 01:23
Types of Biopharmaceutical Studies: Controlled and Non-Controlled Approaches
Non-controlled studies, commonly employed for initial exploration, lack a control group, rendering them susceptible to biases and external influences. In contrast,...
 01:10
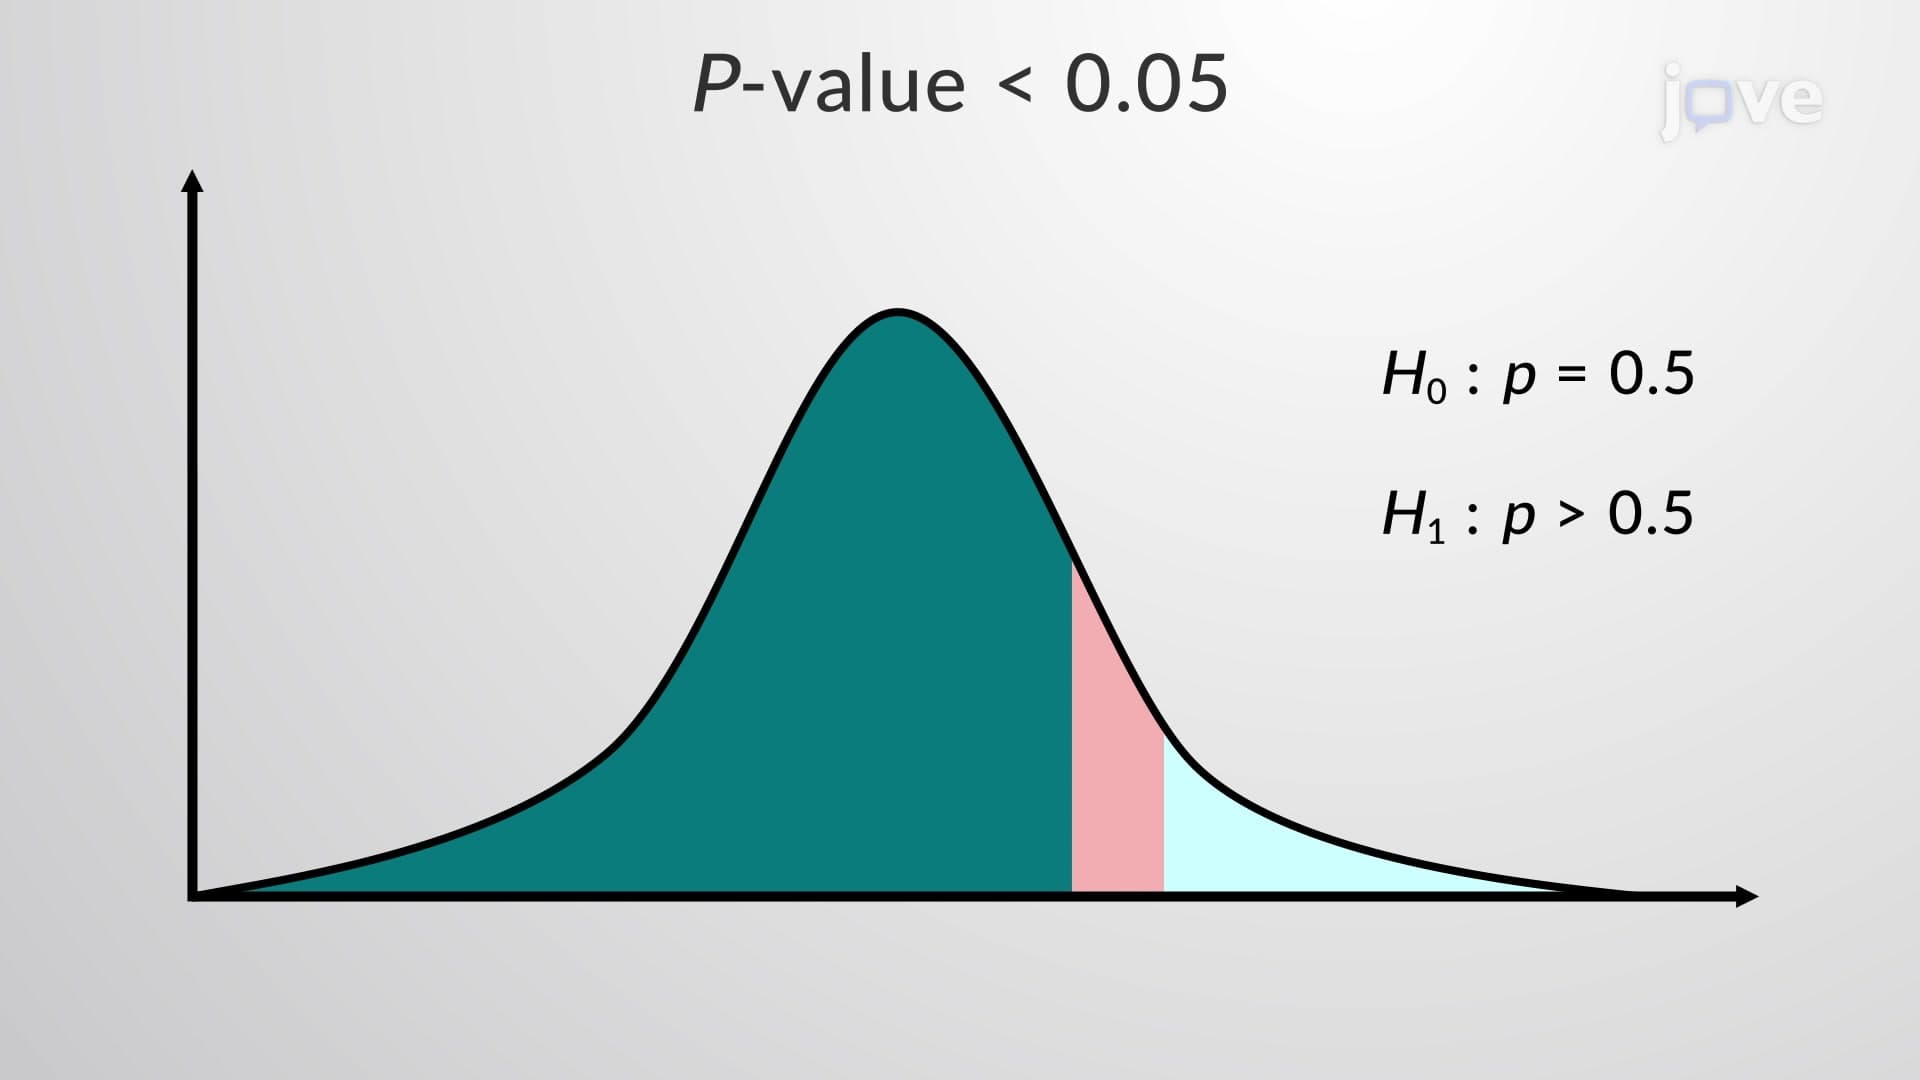
P-value
P-value stands for the probability value. P-value is the probability that, if the null hypothesis is true, the results from another randomly selected sample will be as extreme or more extreme as the results obtained from the given sample.
A large P-value calculated from the data indicates to not reject the null hypothesis. But a higher P-value does not mean that the null hypothesis is true. The smaller the P-value, the more...
 01:22
Bias
In statistics, a sampling bias is created when a sample is collected from a population, and some members of the population are not as likely to be chosen as others (remember, each member...
 01:11
Observational Studies
There are three types of observational studies – Prospective, retrospective, and cross-sectional.
Prospective Study
Prospective studies, also known as longitudinal or cohort studies, are carried out by collecting future data from groups sharing similar characteristics. One...