TopModel: Template-Based Protein Structure Prediction at Low Sequence Identity Using Top-Down Consensus and Deep Neural Networks
Related Experiment Video
Updated: Dec 30, 2025

A Protocol for Computer-Based Protein Structure and Function Prediction
Published on: November 3, 2011
Daniel Mulnaes1, Nicola Porta1, Rebecca Clemens2
1Institut für Pharmazeutische und Medizinische Chemie, Heinrich-Heine-Universität Düsseldorf, 40225 Düsseldorf, Germany.

Abstract:
Knowledge of protein structures is essential to understand proteins' functions, evolution, dynamics, stabilities, and interactions and for data-driven protein- or drug design. Yet, experimental structure determination rates are far exceeded by that of next-generation sequencing, resulting in less than 1/1000th of proteins having an experimentally known 3D structure. Computational structure prediction seeks to alleviate this problem, and the Critical Assessment of Protein Structure Prediction (CASP) has shown the value of consensus and meta-methods that utilize complementary algorithms. However, traditionally, such methods employ majority voting during template selection and model averaging during refinement, which can drive the model away from the native fold if it is underrepresented in the ensemble. Here, we present TopModel, a fully automated meta-method for protein structure prediction. In contrast to traditional consensus and meta-methods, TopModel uses top-down consensus and deep neural networks to select templates and identify and correct wrongly modeled regions. TopModel combines a broad range of state-of-the-art methods for threading, alignment, and model quality estimation and provides a versatile workflow and toolbox for template-based structure prediction. TopModel shows a superior template selection, alignment accuracy, and model quality for template-based structure prediction on the CASP10-12 datasets compared to 12 state-of-the-art stand-alone primary predictors. TopModel was validated by prospective predictions of the nisin resistance protein (NSR) protein from Streptococcus agalactiae and LipoP from Clostridium difficile, showing far better agreement with experimental data than any of its constituent primary predictors. These results, in general, demonstrate the utility of TopModel for protein structure prediction and, in particular, show how combining computational structure prediction with sparse or low-resolution experimental data can improve the final model.

Related Concept Videos
 02:26
Conservation of Protein Domains Over Different Proteins
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to...
 01:49
Conserved Binding Sites
Binding sites are often located in large pockets, and if their location on a protein’s surface is unknown, it can be predicted using various approaches. The energetic method computationally...
02:26Conservation of Protein Domains
 02:04
Protein-protein Interfaces
 02:15
Protein and Protein Structure
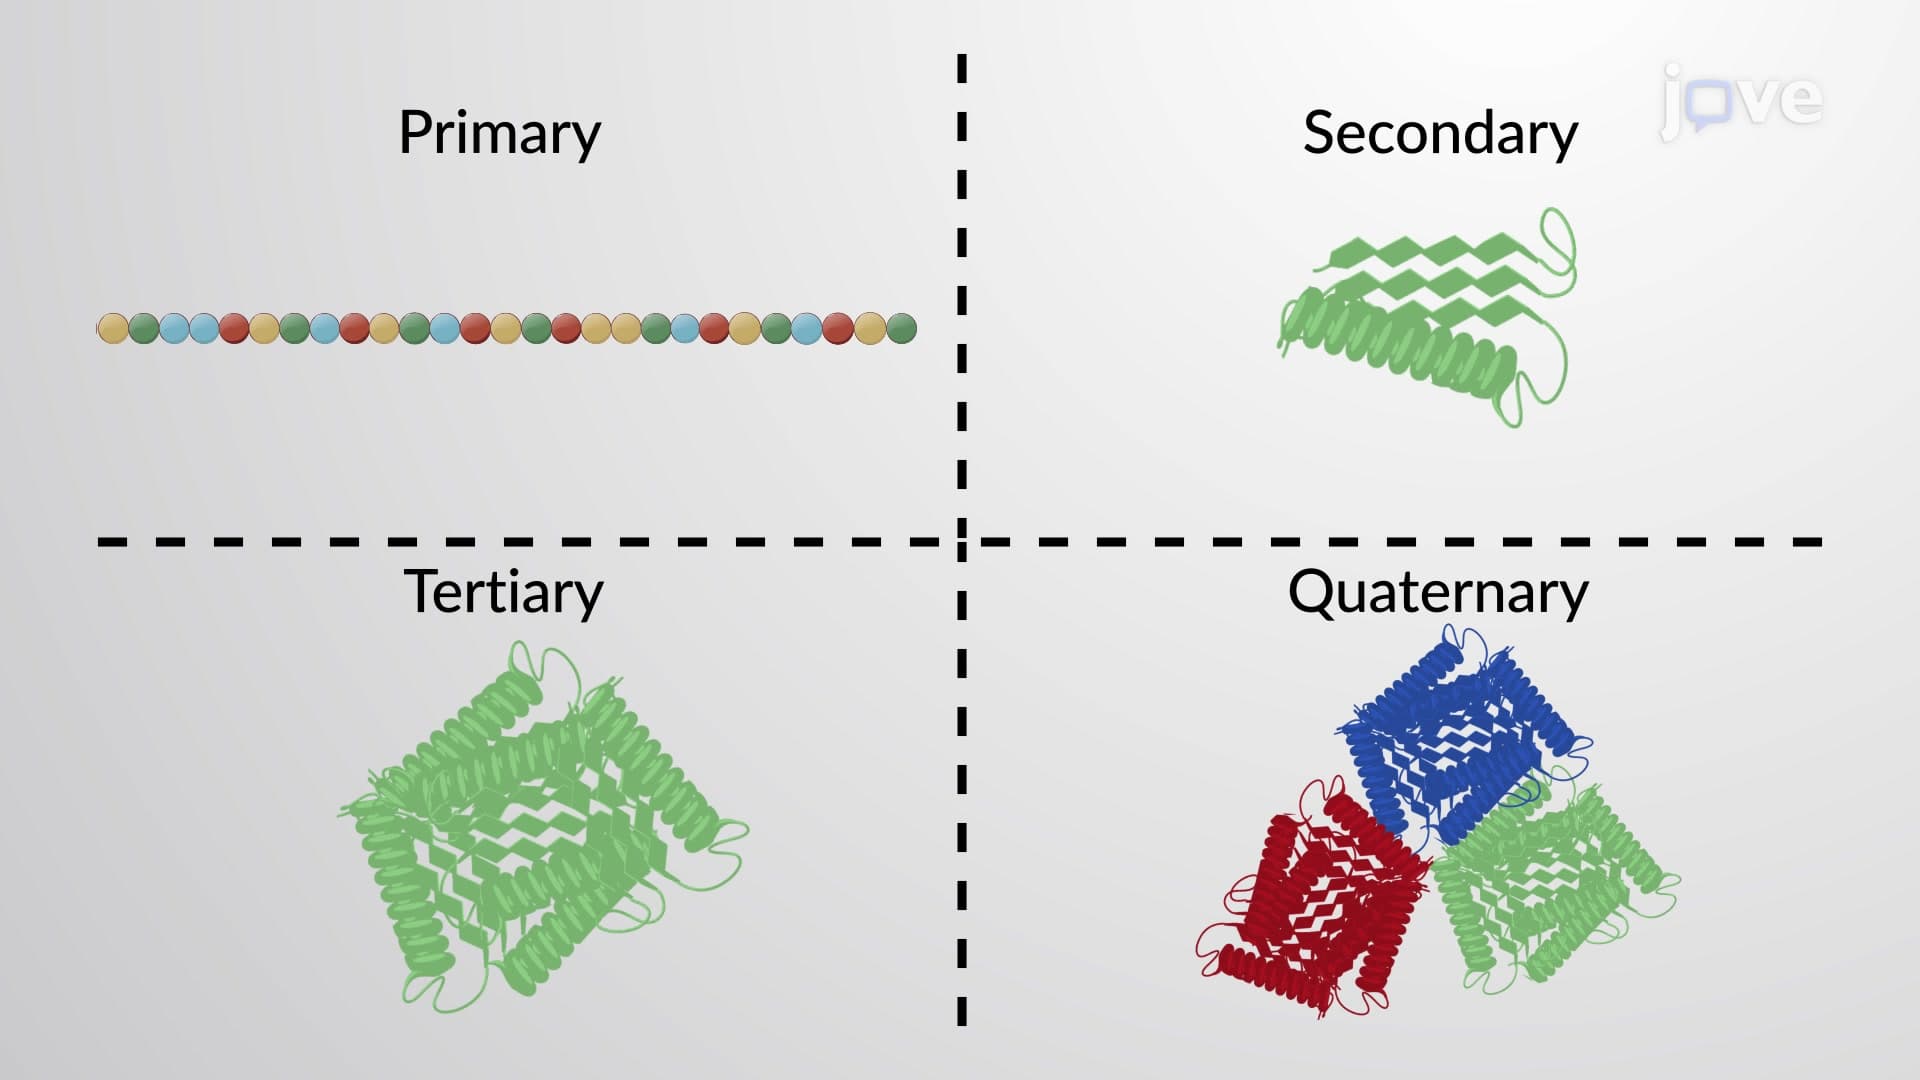
A protein's shape is critical to its function. For example, an enzyme...
 02:26
Protein Networks
These interactions can be represented through maps depicting protein-protein interaction networks, represented as nodes and edges. Nodes are circles that are representative of a protein,...