SibNet: Sibling Convolutional Encoder for Video Captioning
Related Experiment Video
Updated: Dec 26, 2025

Application of Deep Learning-Based Medical Image Segmentation via Orbital Computed Tomography
Published on: November 30, 2022

Abstract:
Visual captioning, the task of describing an image or a video using one or few sentences, is a challenging task owing to the complexity of understanding the copious visual information and describing it using natural language. Motivated by the success of applying neural networks for machine translation, previous work applies sequence to sequence learning to translate videos into sentences. In this work, different from previous work that encodes visual information using a single flow, we introduce a novel Sibling Convolutional Encoder (SibNet) for visual captioning, which employs a dual-branch architecture to collaboratively encode videos. The first content branch encodes visual content information of the video with an autoencoder, capturing the visual appearance information of the video as other networks often do. While the second semantic branch encodes semantic information of the video via visual-semantic joint embedding, which brings complementary representation by considering the semantics when extracting features from videos. Then both branches are effectively combined with soft-attention mechanism and finally fed into a RNN decoder to generate captions. With our SibNet explicitly capturing both content and semantic information, the proposed model can better represent the rich information in videos. To validate the advantages of the proposed model, we conduct experiments on two benchmarks for video captioning, YouTube2Text and MSR-VTT. Our results demonstrate that the proposed SibNet consistently outperforms existing methods across different evaluation metrics.

Related Concept Videos
 01:17
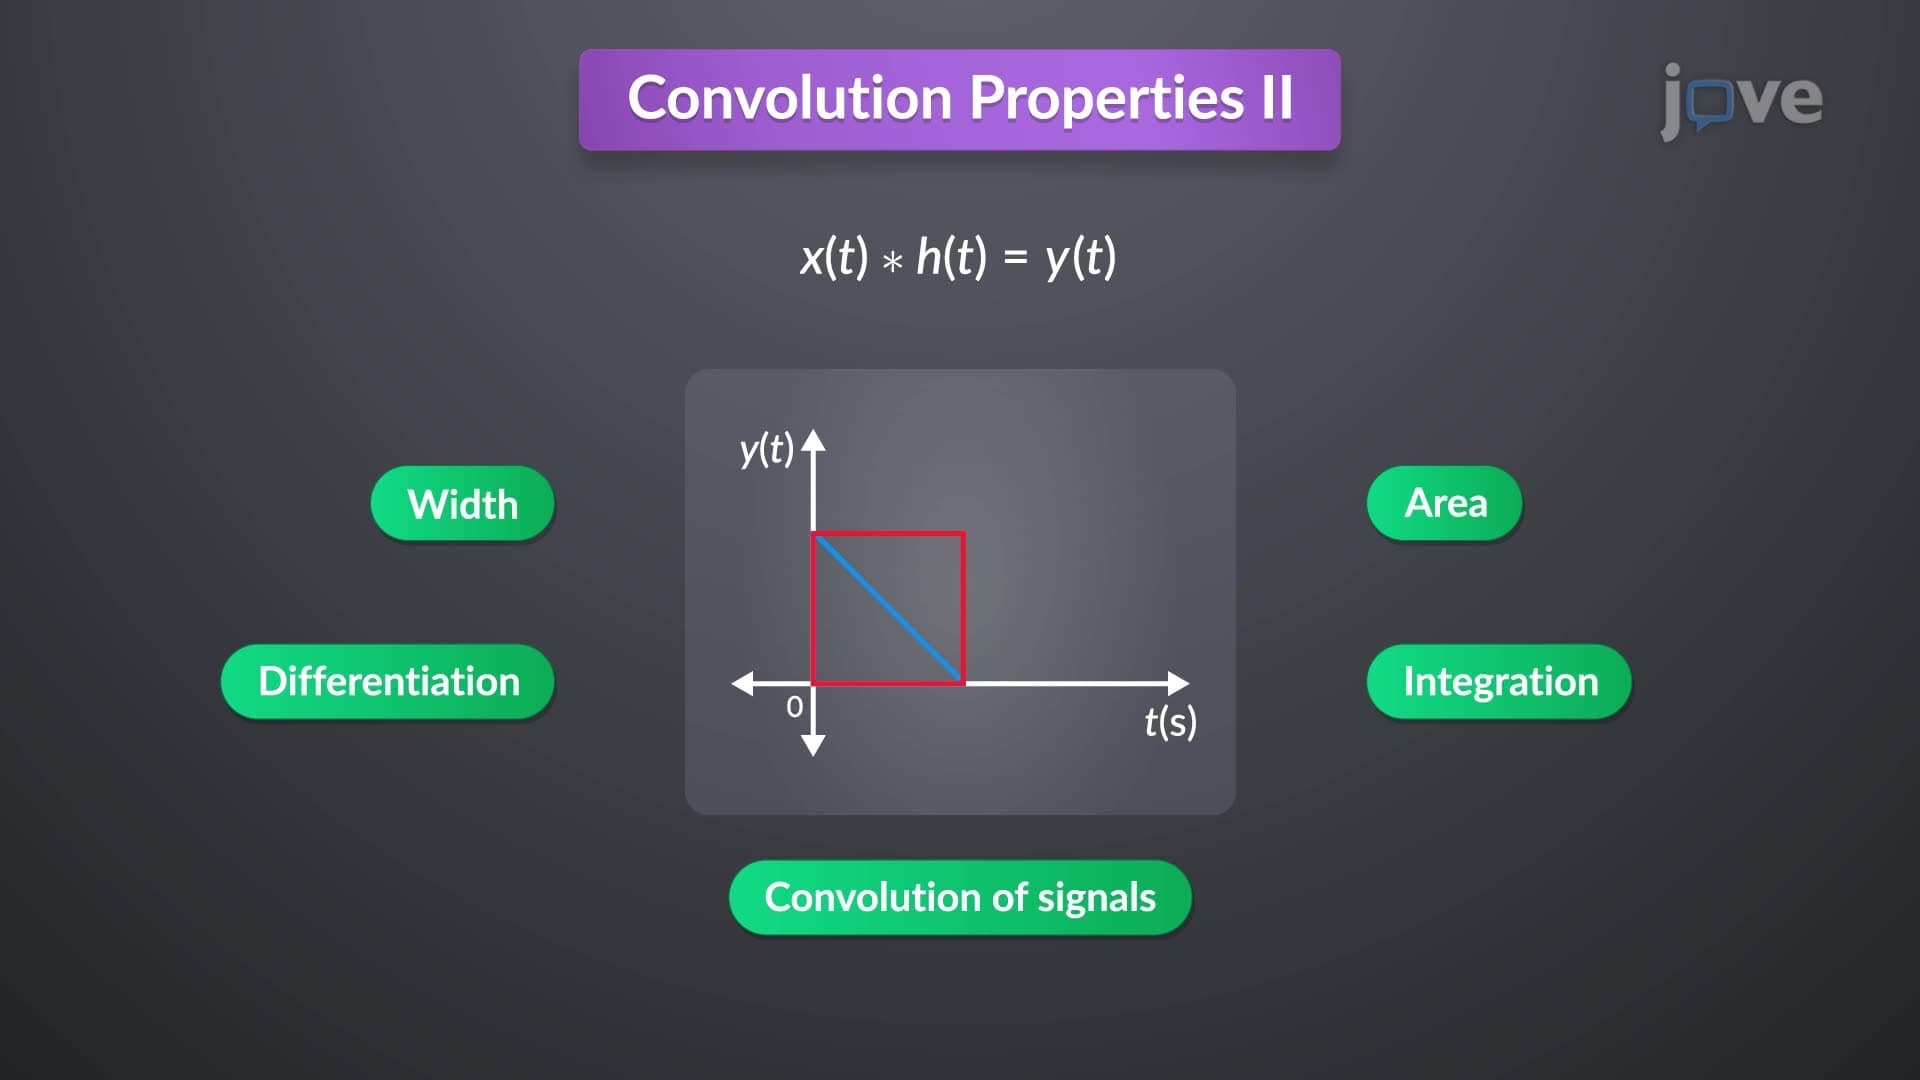
Convolution Properties II
The width property indicates that if the durations of input signals are T1 and T2, then the width of the output response equals the sum of both durations, irrespective of the shapes of the two functions. For instance, convolving two rectangular pulses with durations of 2 seconds and 1 second results in a function with a width of 3 seconds.
The area property asserts that the area under the...
 01:20
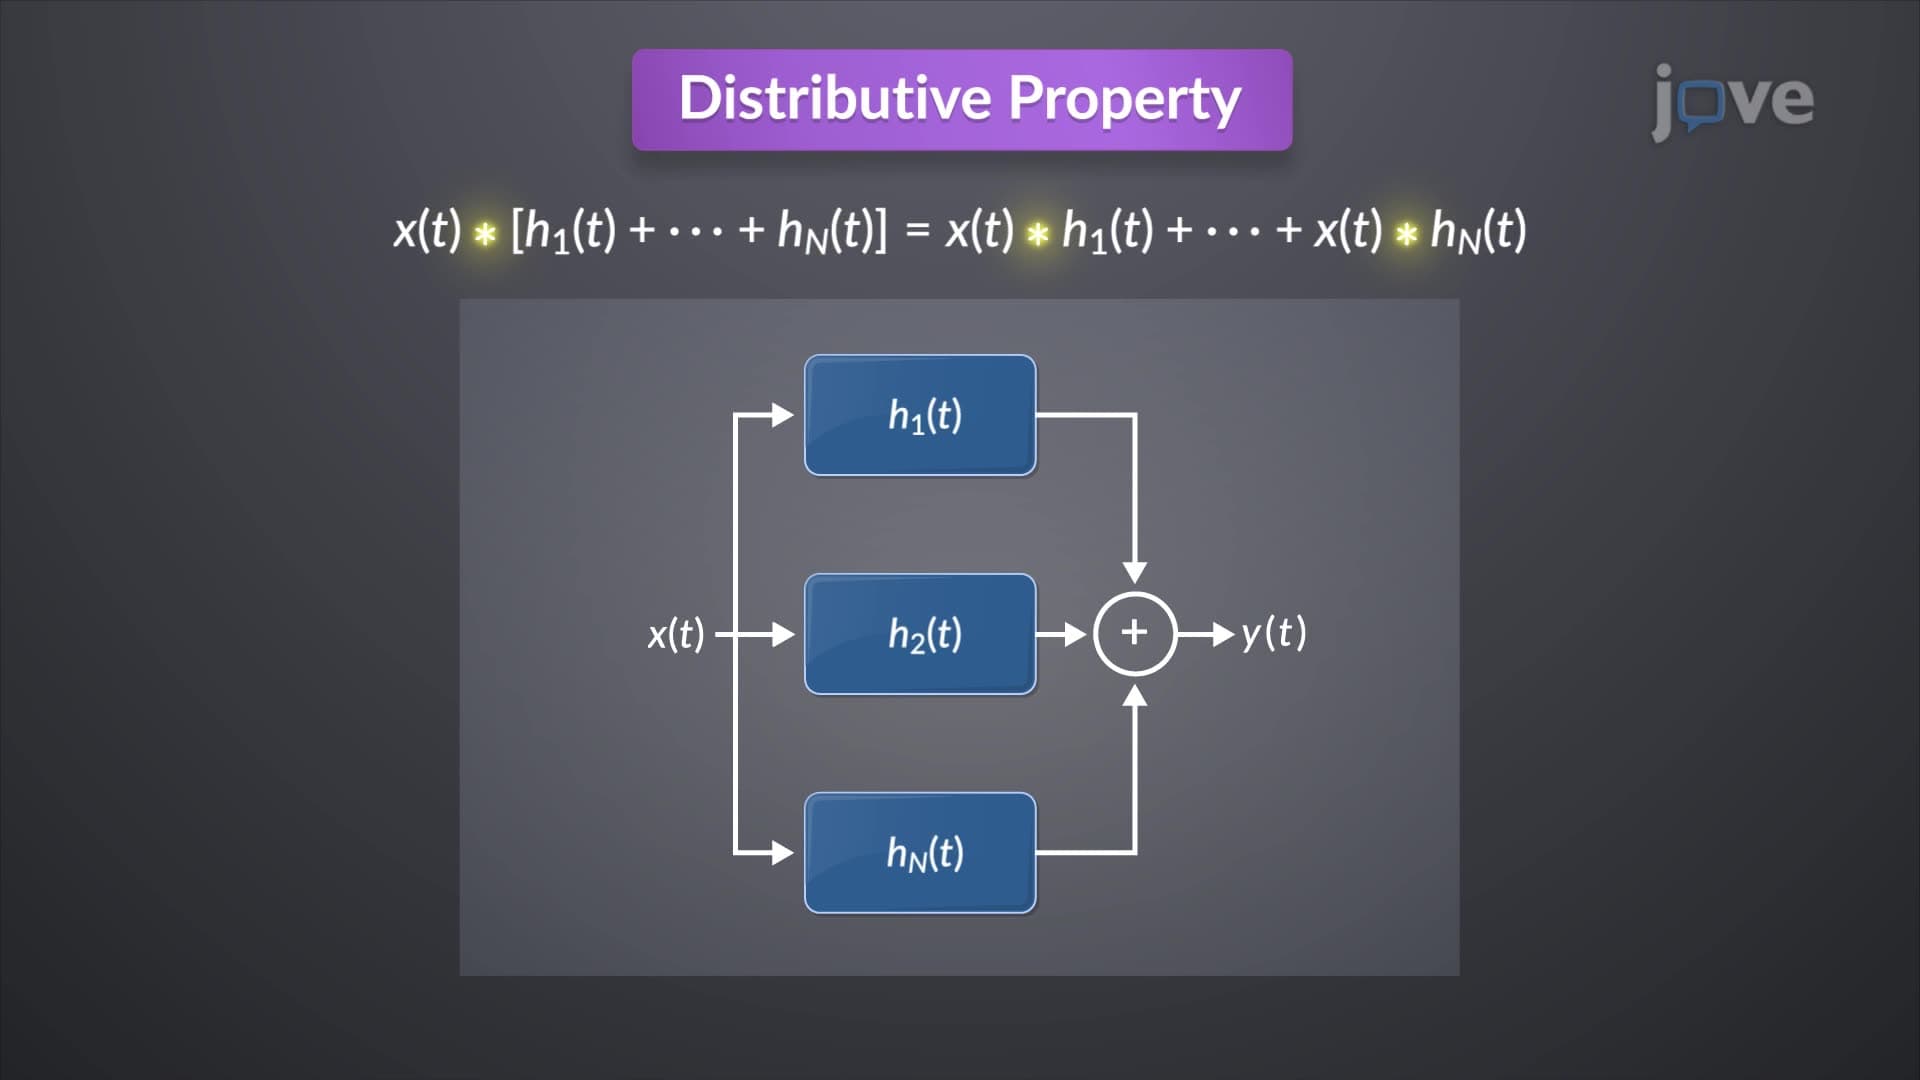
Convolution Properties I
The commutative property reveals that the input and the impulse response of an LTI (Linear Time-Invariant) system can be interchanged without affecting the output:
 01:24
Convolution: Math, Graphics, and Discrete Signals
To simplify the convolution integral, it is assumed that both the input signal and impulse response are zero for negative time values. The graphical convolution process...
 01:20
Deconvolution
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
 01:22
Upsampling
 01:19
Encoding
Automatic processing involves the encoding of details like time, space, frequency, and the meaning of words, usually done without conscious...