Related Experiment Video
Updated: Dec 25, 2025


Inverse Probability of Treatment Weighting Propensity Score using the Military Health System Data Repository and National Death Index
Published on: January 8, 2020
Automatic variable selection for exposure-driven propensity score matching with unmeasured confounders
Daniela Zöller1,2, Leesa F Wockner3, Harald Binder1,2
1Institute of Medical Biometry and Statistics, Faculty of Medicine and Medical Center - University of Freiburg, Freiburg, Germany.

Abstract:
Multivariable model building for propensity score modeling approaches is challenging. A common propensity score approach is exposure-driven propensity score matching, where the best model selection strategy is still unclear. In particular, the situation may require variable selection, while it is still unclear if variables included in the propensity score should be associated with the exposure and the outcome, with either the exposure or the outcome, with at least the exposure or with at least the outcome. Unmeasured confounders, complex correlation structures, and non-normal covariate distributions further complicate matters. We consider the performance of different modeling strategies in a simulation design with a complex but realistic structure and effects on a binary outcome. We compare the strategies in terms of bias and variance in estimated marginal exposure effects. Considering the bias in estimated marginal exposure effects, the most reliable results for estimating the propensity score are obtained by selecting variables related to the exposure. On average this results in the least bias and does not greatly increase variances. Although our results cannot be generalized, this provides a counterexample to existing recommendations in the literature based on simple simulation settings. This highlights that recommendations obtained in simple simulation settings cannot always be generalized to more complex, but realistic settings and that more complex simulation studies are needed.
More Related Videos
 03:05
Influence of Emotional Factors on the Efficacy of Acupuncture Treatment for Overweight Complicated with Hyperlipidemia: A Retrospective Cohort Study
Published on: November 21, 2025
 09:38
Generalized Psychophysiological Interaction PPI Analysis of Memory Related Connectivity in Individuals at Genetic Risk for Alzheimer's Disease
Published on: November 14, 2017
Related Concept Videos
 01:25
Strategies for Assessing and Addressing Confounding
Confounding can be addressed at both the design phase of a study and through analytical methods after data...
 01:13
Randomized Experiments
Simple randomization
Simple...
 01:27
Confounding in Epidemiological Studies
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
 01:19
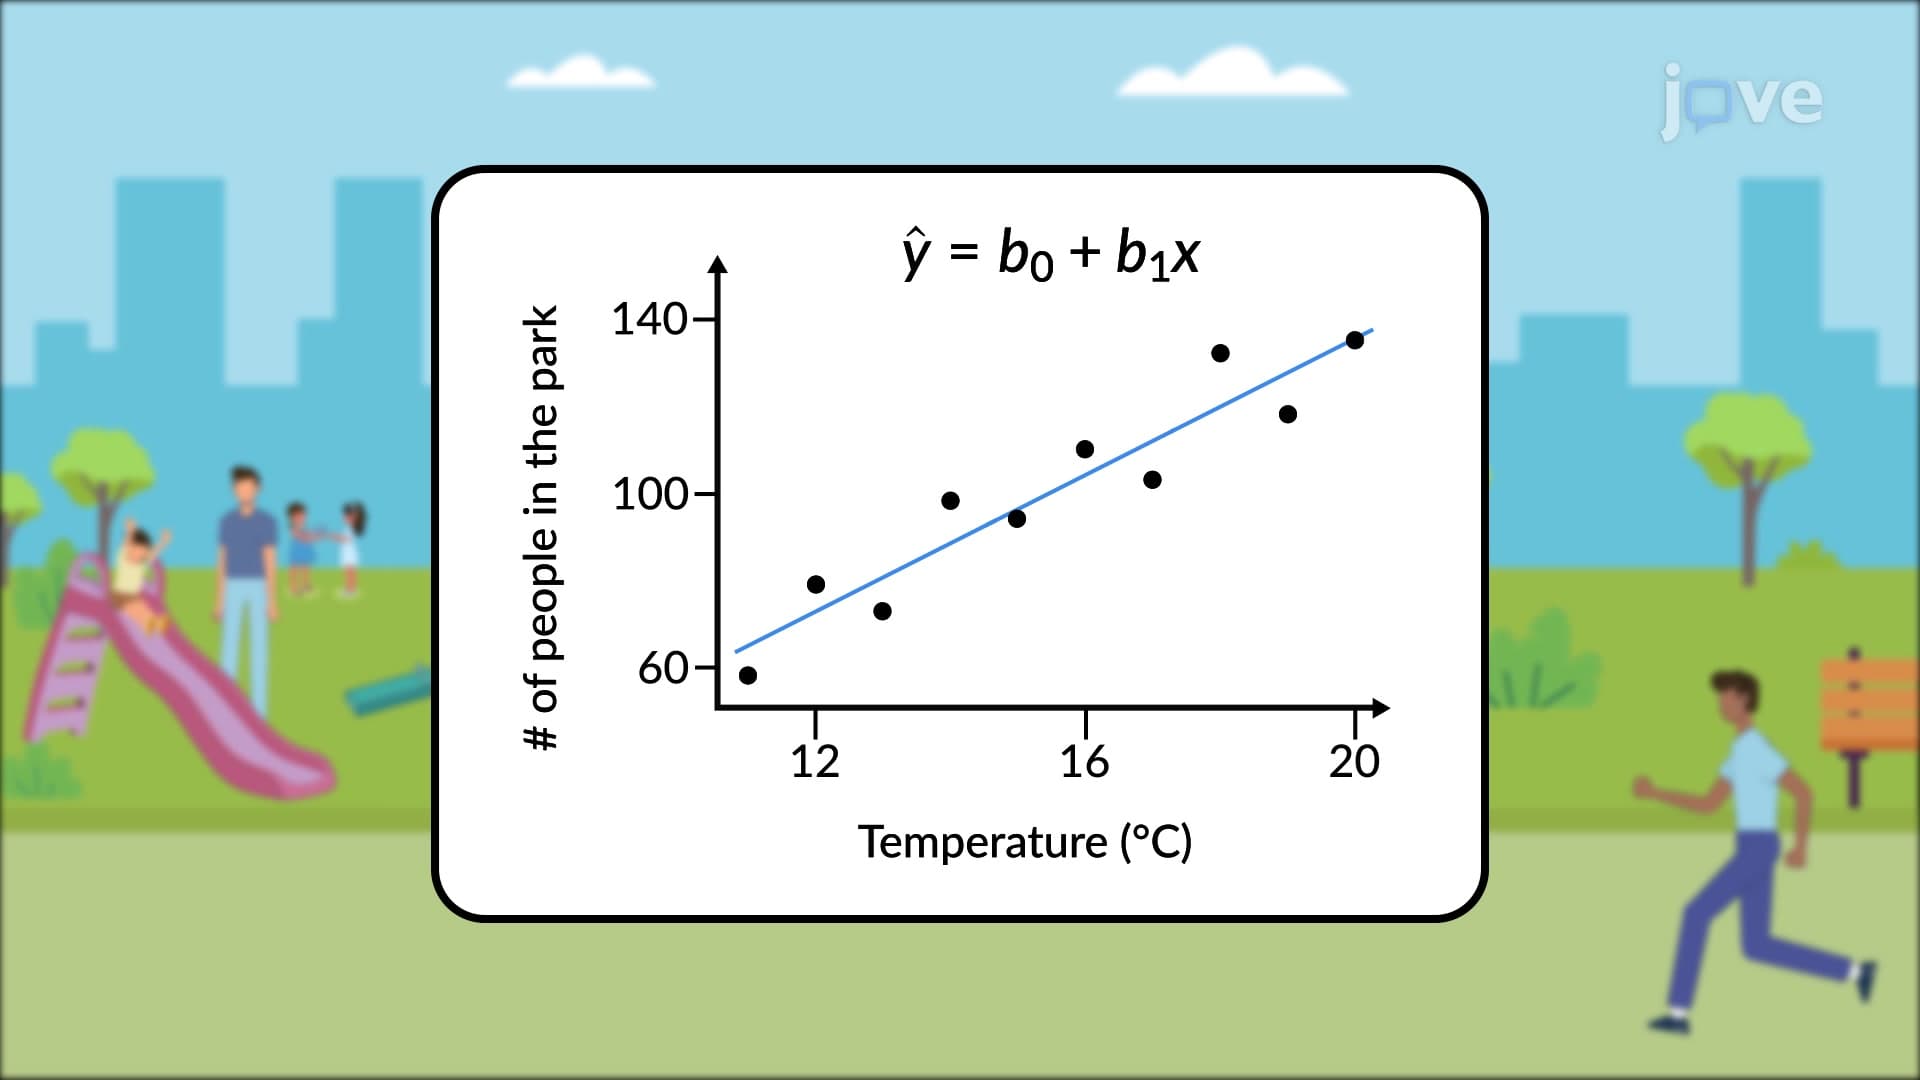
Variation
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
On...