Related Experiment Video
Updated: Dec 22, 2025

Tick Microbiome Characterization by Next-Generation 16S rRNA Amplicon Sequencing
Published on: August 25, 2018
Sequence count data are poorly fit by the negative binomial distribution
Stijn Hawinkel1, J C W Rayner2,3, Luc Bijnens4,5
1Department of Data Analysis and Mathematical Modelling, Ghent University, Ghent, Belgium.

Abstract:
Sequence count data are commonly modelled using the negative binomial (NB) distribution. Several empirical studies, however, have demonstrated that methods based on the NB-assumption do not always succeed in controlling the false discovery rate (FDR) at its nominal level. In this paper, we propose a dedicated statistical goodness of fit test for the NB distribution in regression models and demonstrate that the NB-assumption is violated in many publicly available RNA-Seq and 16S rRNA microbiome datasets. The zero-inflated NB distribution was not found to give a substantially better fit. We also show that the NB-based tests perform worse on the features for which the NB-assumption was violated than on the features for which no significant deviation was detected. This gives an explanation for the poor behaviour of NB-based tests in many published evaluation studies. We conclude that nonparametric tests should be preferred over parametric methods.

Related Concept Videos
 01:15
Binomial Probability Distribution
The outcomes of a binomial experiment fit a binomial probability distribution. A statistical experiment can be classified as a binomial experiment if the following conditions are met:
There are a fixed number of trials. Think of trials as repetitions of an experiment. The letter n denotes the number of trials.
There are only two possible outcomes,...
 01:09
Poisson Probability Distribution
The...
 01:17
Wald-Wolfowitz Runs Test II
For binary data, runs are identified using symbols such as + and −, or equivalently, 1s and 0s. In...
 01:19
Expected Frequencies in Goodness-of-Fit Tests
 01:10
Chi-square Distribution
 01:17
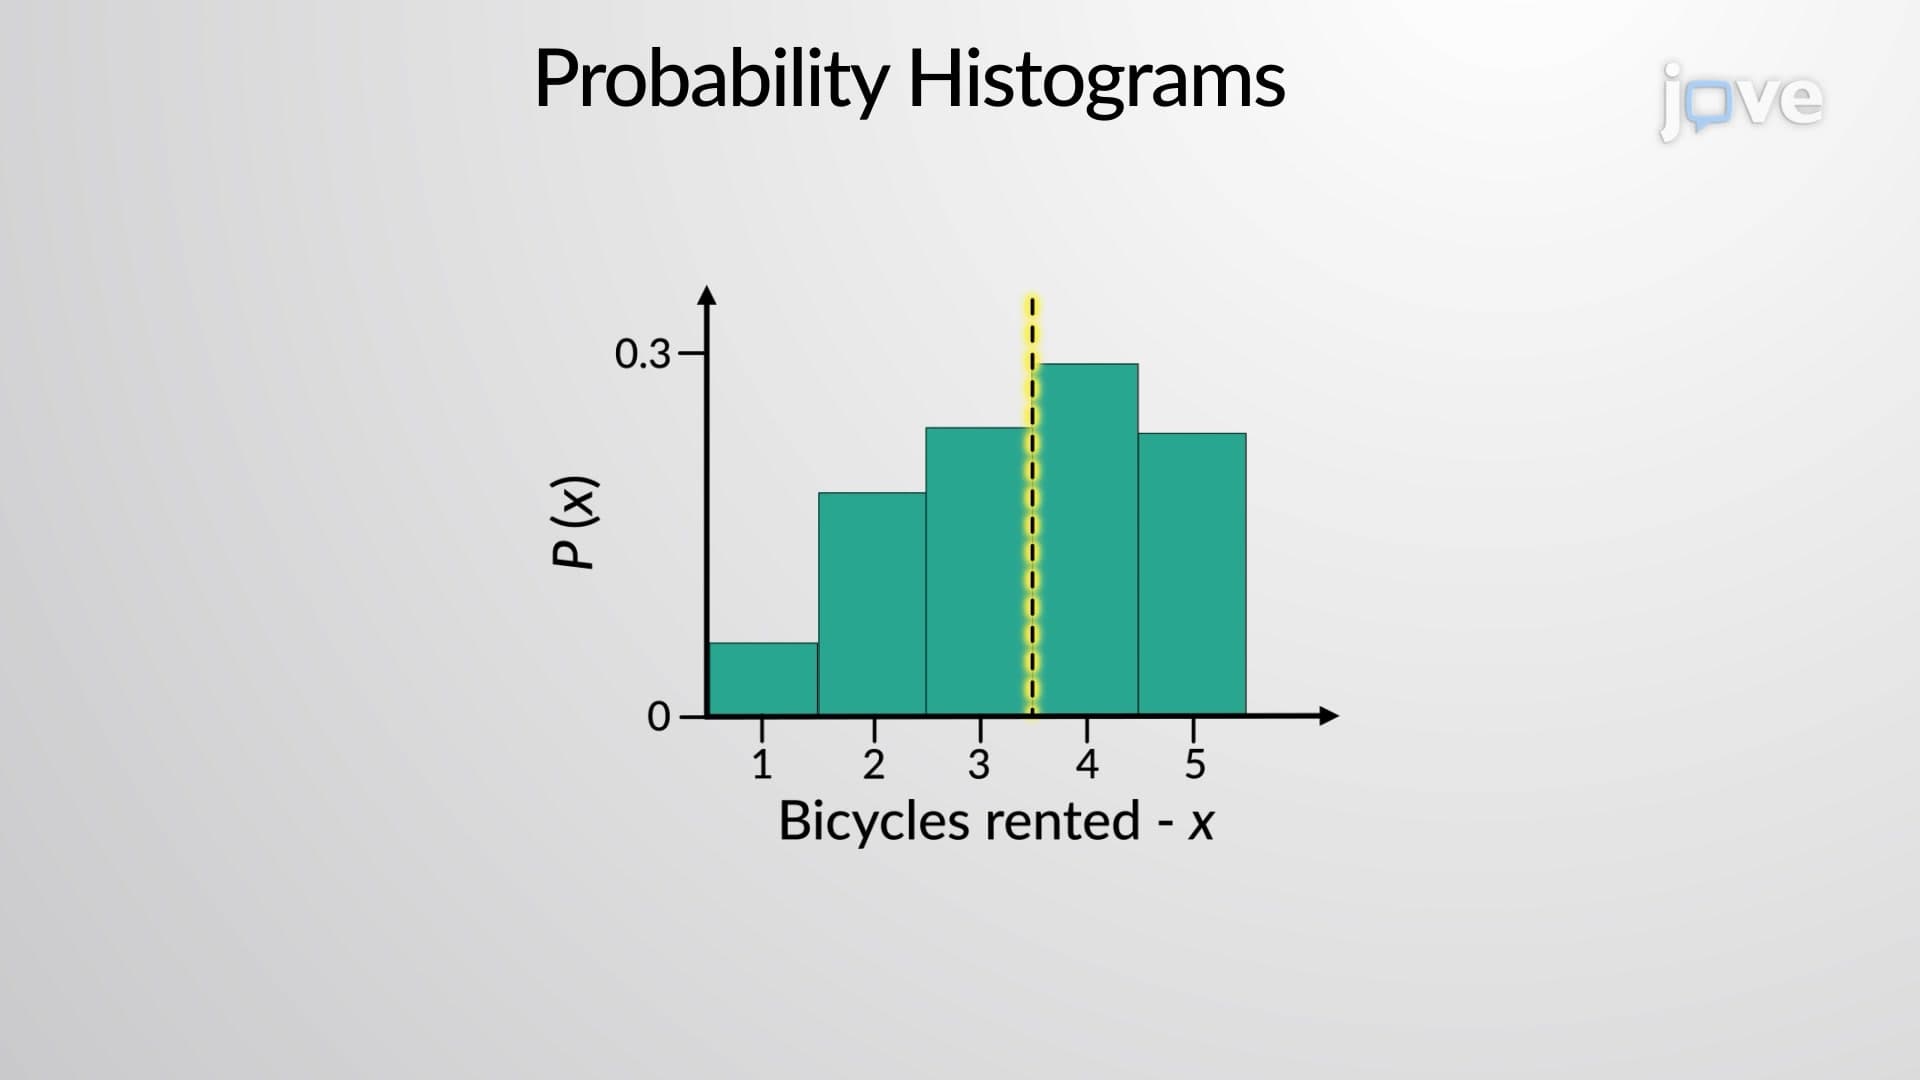
Probability Histograms