Related Experiment Video
Updated: Dec 21, 2025
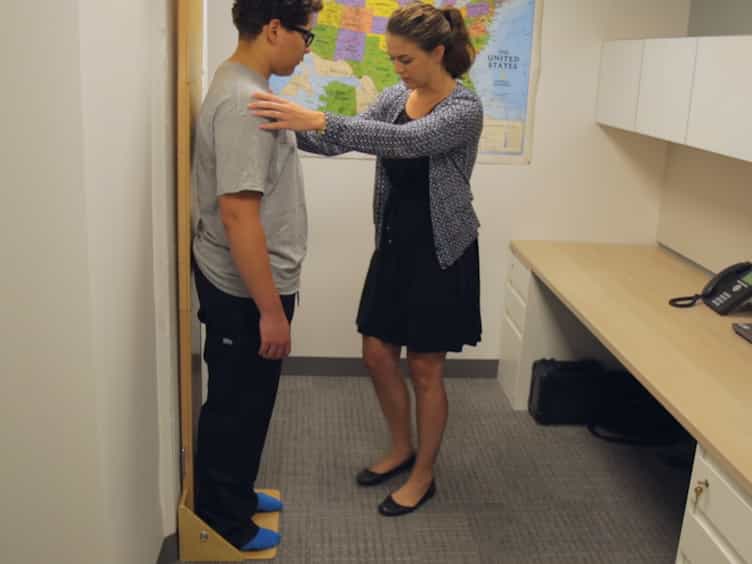

Assessment of Child Anthropometry in a Large Epidemiologic Study
Published on: February 2, 2017
Dynamic prediction model to identify young children at high risk of future overweight: Development and internal
Marieke Welten1, Alet H Wijga2, Marleen Hamoen3
1Department of Epidemiology and Biostatistics, Amsterdam Public Health Research Institute, VU University Medical Center, Amsterdam, The Netherlands.

Insights
A new dynamic prediction model can identify children at high risk of developing overweight by age 8. This model uses easily obtainable information for early intervention, prioritizing primary prevention strategies.
Area of Science:
- Pediatrics
- Public Health
- Obesity Research
Background:
- Primary prevention of childhood overweight is more effective than secondary prevention.
- Identifying at-risk children early is crucial for effective intervention.
- Existing methods for predicting childhood overweight have limitations.
Purpose of the Study:
- To develop and internally validate a dynamic prediction model for childhood overweight.
- The model aims to identify children at high risk of future overweight (age 8).
- The model is applicable from birth up to age 6.
Main Methods:
- Utilized data from the 1996-1997 Netherlands birth cohort (N=2265).
- Included longitudinal Body Mass Index Standard Deviation Scores (BMI SDS) from infancy to age 6.
- Employed Generalized Estimating Equations for model development and internal validation.
Main Results:
- The final model included maternal and paternal BMI, paternal education, birthweight, sex, ethnicity, indoor smoke exposure, and longitudinal BMI SDS.
- The dynamic model demonstrated good predictive ability with an Area Under the Curve of 0.845.
- Nagelkerke R-squared was 0.351, indicating substantial model performance.
Conclusions:
- A dynamic prediction model for childhood overweight was successfully developed.
- The model shows good predictive accuracy using readily available information.
- External validation is recommended to confirm its practical utility.
Background:
Primary prevention of overweight is to be preferred above secondary prevention, which has shown moderate effectiveness.
Objective:
To develop and internally validate a dynamic prediction model to identify young children in the general population, applicable at every age between birth and age 6, at high risk of future overweight (age 8).
Methods:
Data were used from the Prevention and Incidence of Asthma and Mite Allergy birth cohort, born in 1996 to 1997, in the Netherlands. Participants for whom data on the outcome overweight at age 8 and at least three body mass index SD scores (BMI SDS) at the age of ≥3 months and ≤6 years were available, were included (N = 2265). The outcome of the prediction model is overweight (yes/no) at age 8 (range 7.4-10.5 years), defined according to the sex- and age-specific BMI cut-offs of the International Obesity Task Force.
Results:
After backward selection in a Generalized Estimating Equations analysis, the prediction model included the baseline predictors maternal BMI, paternal BMI, paternal education, birthweight, sex, ethnicity and indoor smoke exposure; and the longitudinal predictors BMI SDS, and the linear and quadratic terms of the growth curve describing a child's BMI SDS development over time, as well as the longitudinal predictors' interactions with age. The area under the curve of the model after internal validation was 0.845 and Nagelkerke R2 was 0.351.
Conclusions:
A dynamic prediction model for overweight was developed with a good predictive ability using easily obtainable predictor information. External validation is needed to confirm that the model has potential for use in practice.
Related Concept Videos
 01:26
Longitudinal Studies
 01:52
Regression Toward the Mean
 02:20
Longitudinal Research
 01:29
Bias in Epidemiological Studies
 01:24
Obesity
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.