A Framework for Effective Application of Machine Learning to Microbiome-Based Classification Problems
Related Experiment Video
Updated: Dec 18, 2025
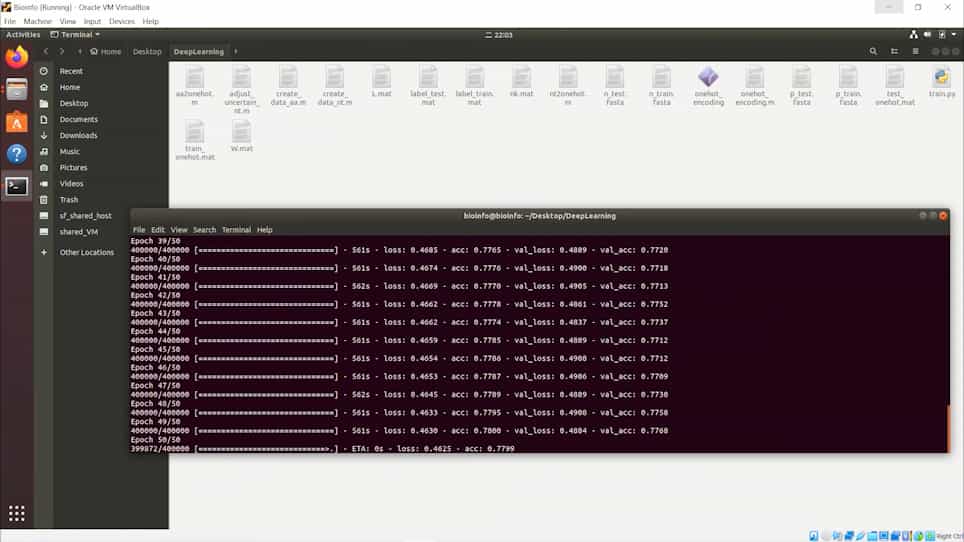
A Virtual Machine Platform for Non-Computer Professionals for Using Deep Learning to Classify Biological Sequences of Metagenomic Data
Published on: September 25, 2021
Begüm D Topçuoğlu1, Nicholas A Lesniak1, Mack T Ruffin2
1Department of Microbiology and Immunology, University of Michigan, Ann Arbor, Michigan, USA.

Abstract:
Machine learning (ML) modeling of the human microbiome has the potential to identify microbial biomarkers and aid in the diagnosis of many diseases such as inflammatory bowel disease, diabetes, and colorectal cancer. Progress has been made toward developing ML models that predict health outcomes using bacterial abundances, but inconsistent adoption of training and evaluation methods call the validity of these models into question. Furthermore, there appears to be a preference by many researchers to favor increased model complexity over interpretability. To overcome these challenges, we trained seven models that used fecal 16S rRNA sequence data to predict the presence of colonic screen relevant neoplasias (SRNs) (n = 490 patients, 261 controls and 229 cases). We developed a reusable open-source pipeline to train, validate, and interpret ML models. To show the effect of model selection, we assessed the predictive performance, interpretability, and training time of L2-regularized logistic regression, L1- and L2-regularized support vector machines (SVM) with linear and radial basis function kernels, a decision tree, random forest, and gradient boosted trees (XGBoost). The random forest model performed best at detecting SRNs with an area under the receiver operating characteristic curve (AUROC) of 0.695 (interquartile range [IQR], 0.651 to 0.739) but was slow to train (83.2 h) and not inherently interpretable. Despite its simplicity, L2-regularized logistic regression followed random forest in predictive performance with an AUROC of 0.680 (IQR, 0.625 to 0.735), trained faster (12 min), and was inherently interpretable. Our analysis highlights the importance of choosing an ML approach based on the goal of the study, as the choice will inform expectations of performance and interpretability.IMPORTANCE Diagnosing diseases using machine learning (ML) is rapidly being adopted in microbiome studies. However, the estimated performance associated with these models is likely overoptimistic. Moreover, there is a trend toward using black box models without a discussion of the difficulty of interpreting such models when trying to identify microbial biomarkers of disease. This work represents a step toward developing more-reproducible ML practices in applying ML to microbiome research. We implement a rigorous pipeline and emphasize the importance of selecting ML models that reflect the goal of the study. These concepts are not particular to the study of human health but can also be applied to environmental microbiology studies.

Related Concept Videos
 01:20
Applications of Molecular Taxonomy
 01:24
Microbial Classification System
 01:29
Modern Molecular Taxonomy
 01:28
Methods of Classification and Identification
 01:19
MALDI-TOF Mass Spectrometry
 01:30
Environmental Applications of Microorganisms