Related Experiment Video
Updated: Dec 14, 2025


Development of an Individual-Tree Basal Area Increment Model using a Linear Mixed-Effects Approach
Published on: July 3, 2020
Inference for variance components in linear mixed-effect models with flexible random effect and error distributions
1Department of Population Medicine, Harvard Medical School and Harvard Pilgrim Health Care Institute, Boston, MA, USA.

Abstract:
In many biomedical investigations, parameters of interest, such as the intraclass correlation coefficient, are functions of higher-order moments reflecting finer distributional characteristics. One popular method to make inference for such parameters is through postulating a parametric random effects model. We relax the standard normality assumptions for both the random effects and errors through the use of the Fleishman distribution, a flexible four-parameter distribution which accounts for the third and fourth cumulants. We propose a Fleishman bootstrap method to construct confidence intervals for correlated data and develop a normality test for the random effect and error distributions. Recognizing that the intraclass correlation coefficient may be heavily influenced by a few extreme observations, we propose a modified, quantile-normalized intraclass correlation coefficient. We evaluate our methods in simulation studies and apply these methods to the Childhood Adenotonsillectomy Trial sleep electroencephalogram data in quantifying wave-frequency correlation among different channels.
Related Concept Videos
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:04
Random Error
 01:19
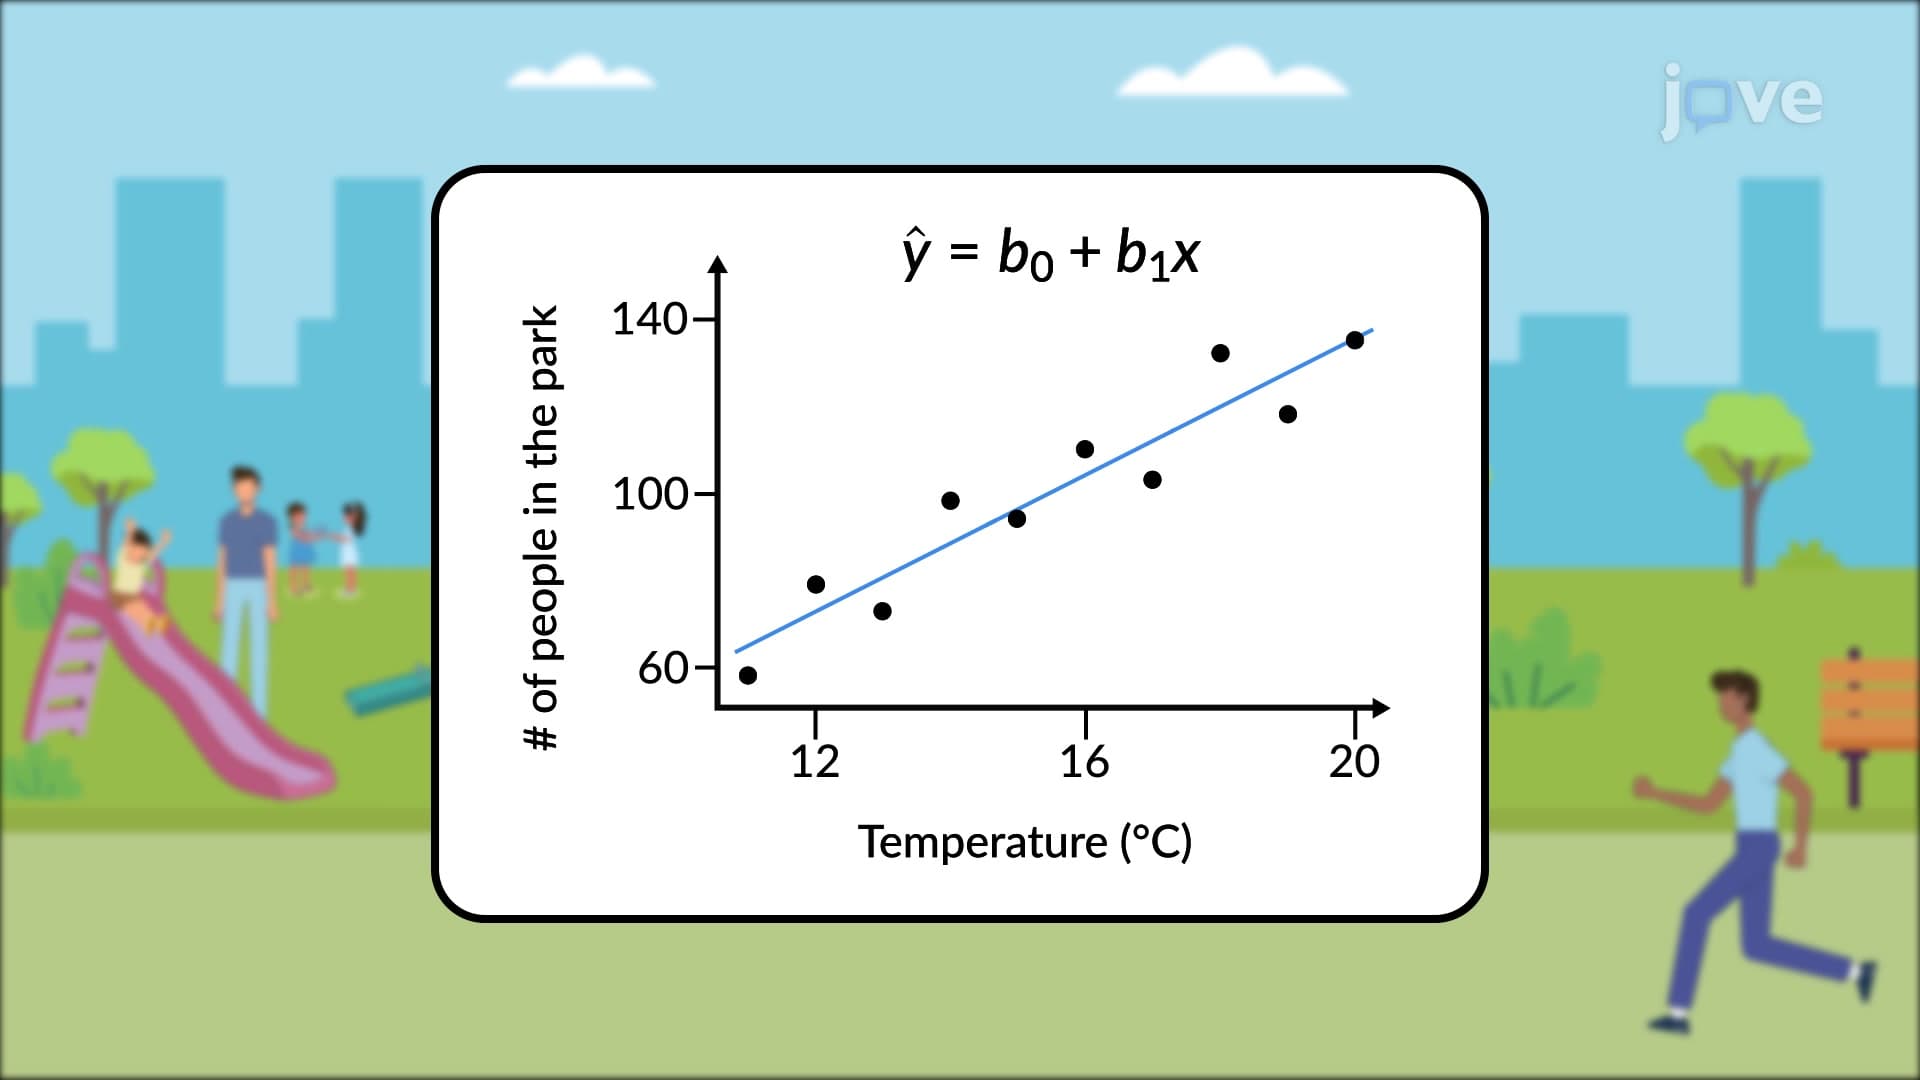
Variation
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
On...
 01:29
Mechanistic Models: Compartment Models in Algorithms for Numerical Problem Solving
In individual population analyses, different algorithms are employed, such as Cauchy's method, which uses a...