Semantic Object Accuracy for Generative Text-to-Image Synthesis
Related Experiment Video
Updated: Dec 10, 2025

Augmenting Large Language Models via Vector Embeddings to Improve Domain-Specific Responsiveness
Published on: December 6, 2024

Abstract:
Generative adversarial networks conditioned on textual image descriptions are capable of generating realistic-looking images. However, current methods still struggle to generate images based on complex image captions from a heterogeneous domain. Furthermore, quantitatively evaluating these text-to-image models is challenging, as most evaluation metrics only judge image quality but not the conformity between the image and its caption. To address these challenges we introduce a new model that explicitly models individual objects within an image and a new evaluation metric called Semantic Object Accuracy (SOA) that specifically evaluates images given an image caption. The SOA uses a pre-trained object detector to evaluate if a generated image contains objects that are mentioned in the image caption, e.g., whether an image generated from "a car driving down the street" contains a car. We perform a user study comparing several text-to-image models and show that our SOA metric ranks the models the same way as humans, whereas other metrics such as the Inception Score do not. Our evaluation also shows that models which explicitly model objects outperform models which only model global image characteristics.
Related Concept Videos
 02:07
Improving Translational Accuracy
02:07Improving Translational Accuracy
 01:28
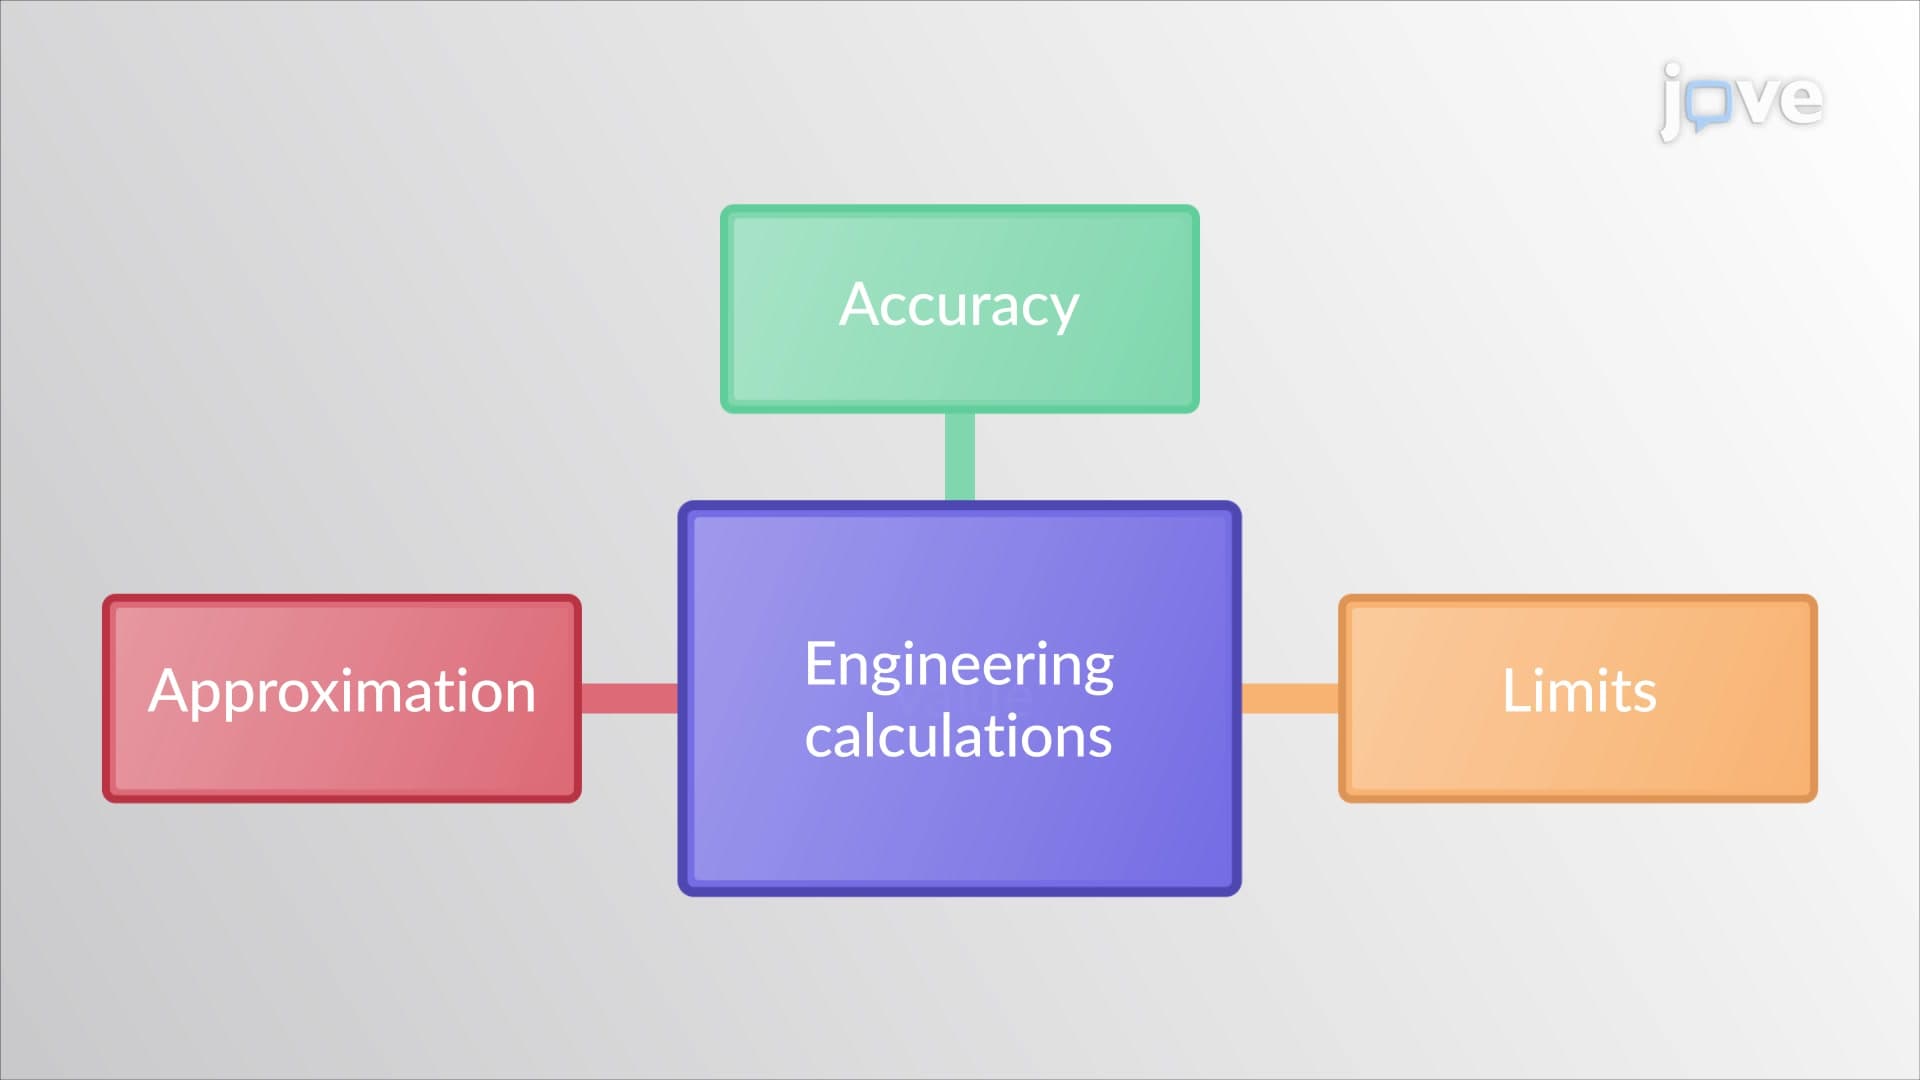
Accuracy, limits, and approximation
Accuracy is defined as the closeness of the measured value to the true or actual value. In engineering mechanics, repeated measurements are taken during theoretical or experimental analyses to ensure that the result is precise and accurate.
The accuracy of any solution is based on the...
 01:13
Nonconscious Mimicry
 02:16
Stereotype Content Model
 01:52
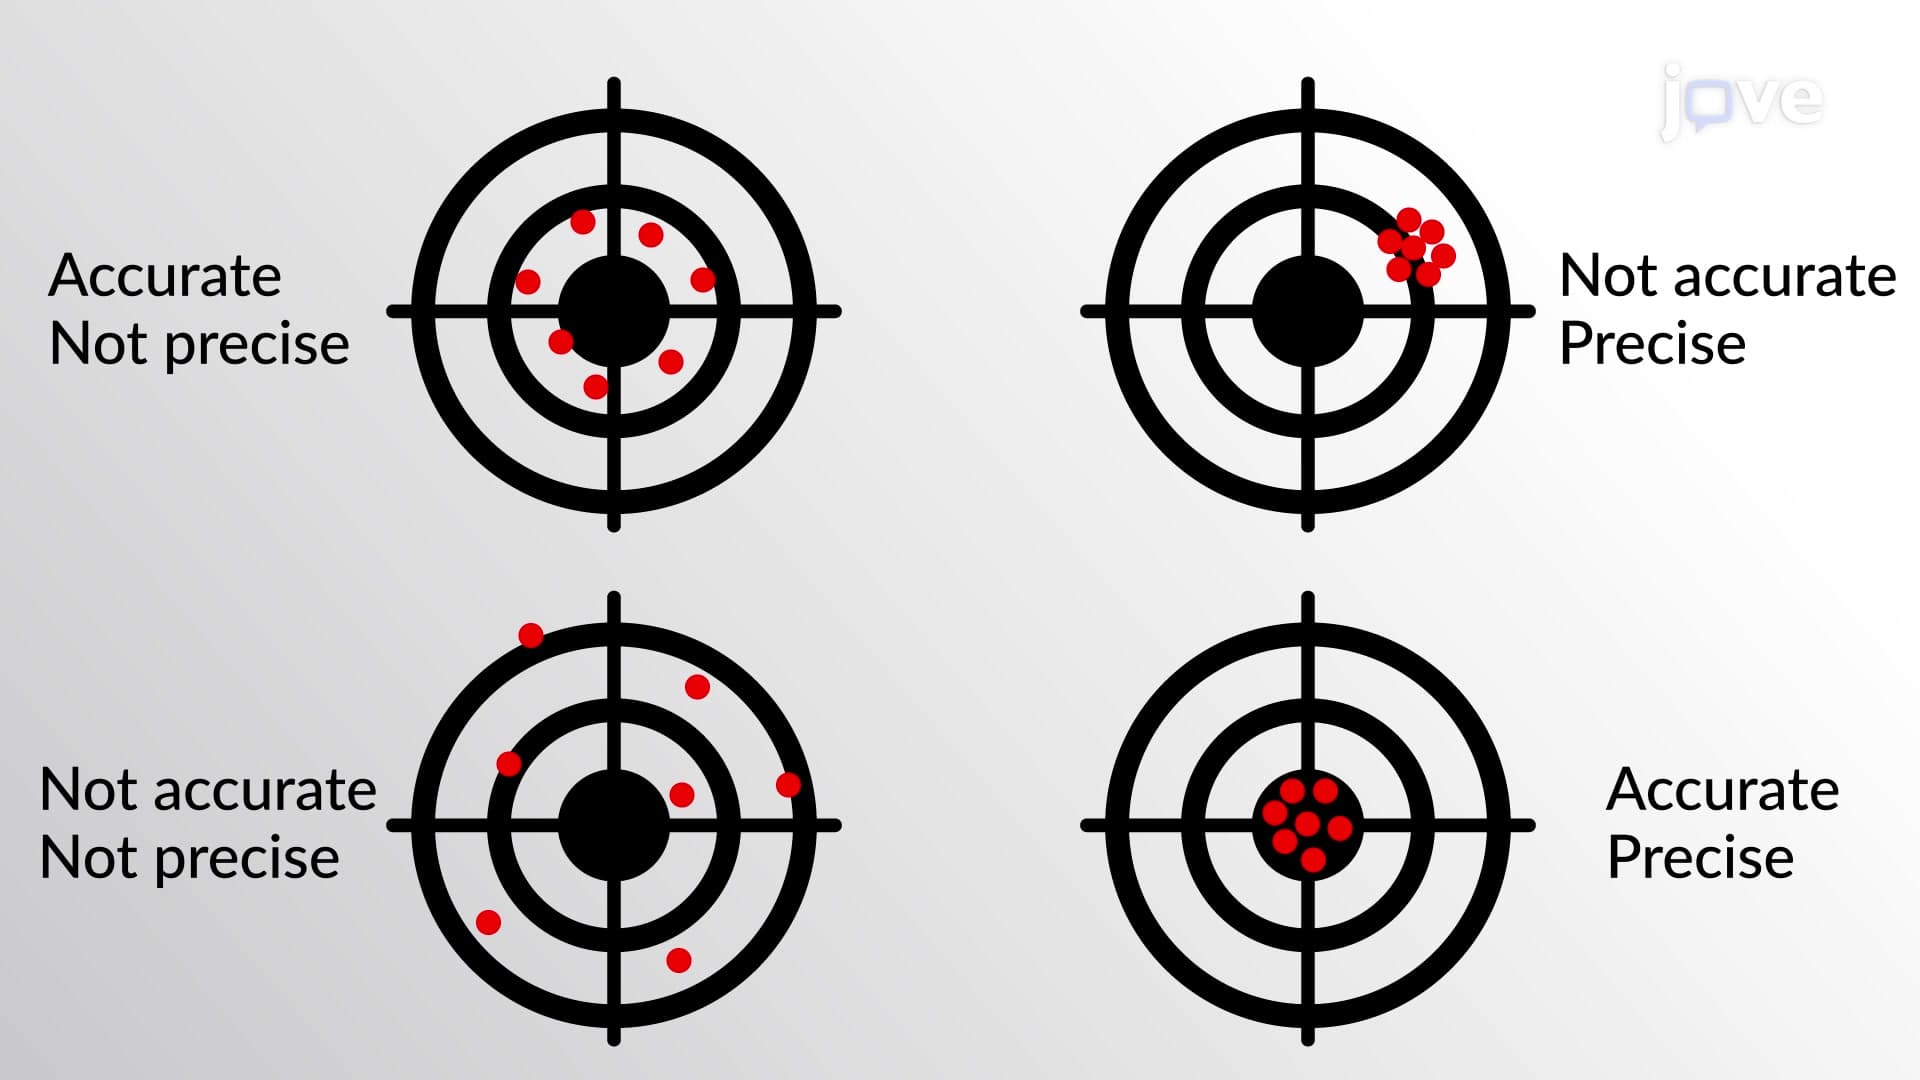
Accuracy and Precision