Related Experiment Video
Updated: Dec 9, 2025

Cloud-Based Phrase Mining and Analysis of User-Defined Phrase-Category Association in Biomedical Publications
Published on: February 23, 2019
Finding semantic patterns in omics data using concept rule learning with an ontology-based refinement operator
František Malinka1,2, Filip Železný1, Jiří Kléma1
1Department of Computer Science, Czech Technical University in Prague, Karlovo náměstí 13, Prague, 121 35 Czech Republic.

Background:
Identification of non-trivial and meaningful patterns in omics data is one of the most important biological tasks. The patterns help to better understand biological systems and interpret experimental outcomes. A well-established method serving to explain such biological data is Gene Set Enrichment Analysis. However, this type of analysis is restricted to a specific type of evaluation. Abstracting from details, the analyst provides a sorted list of genes and ontological annotations of the individual genes; the method outputs a subset of ontological terms enriched in the gene list. Here, in contrary to enrichment analysis, we introduce a new tool/framework that allows for the induction of more complex patterns of 2-dimensional binary omics data. This extension allows to discover and describe semantically coherent biclusters.
Results:
We present a new rapid method called sem1R that reveals interpretable hidden rules in omics data. These rules capture semantic differences between two classes: a target class as a collection of positive examples and a non-target class containing negative examples. The method is inspired by the CN2 rule learner and introduces a new refinement operator that exploits prior knowledge in the form of ontologies. In our work this knowledge serves to create accurate and interpretable rules. The novel refinement operator uses two reduction procedures: Redundant Generalization and Redundant Non-potential, both of which help to dramatically prune the rule space and consequently, speed-up the entire process of rule induction in comparison with the traditional refinement operator as is presented in CN2.
Conclusions:
Efficiency and effectivity of the novel refinement operator were tested on three real different gene expression datasets. Concretely, the Dresden Ovary Dataset, DISC, and m2816 were employed. The experiments show that the ontology-based refinement operator speeds-up the pattern induction drastically. The algorithm is written in C++ and is published as an R package available at http://github.com/fmalinka/sem1r.
More Related Videos
Related Concept Videos
 01:24
Natural and Artificial Concepts
 01:34
Woodward–Hoffmann Selection Rules and Microscopic Reversibility
 01:24
Concepts and Prototypes
The brain organizes this information using concepts, which are mental categories grouping linguistic data,...
 02:09
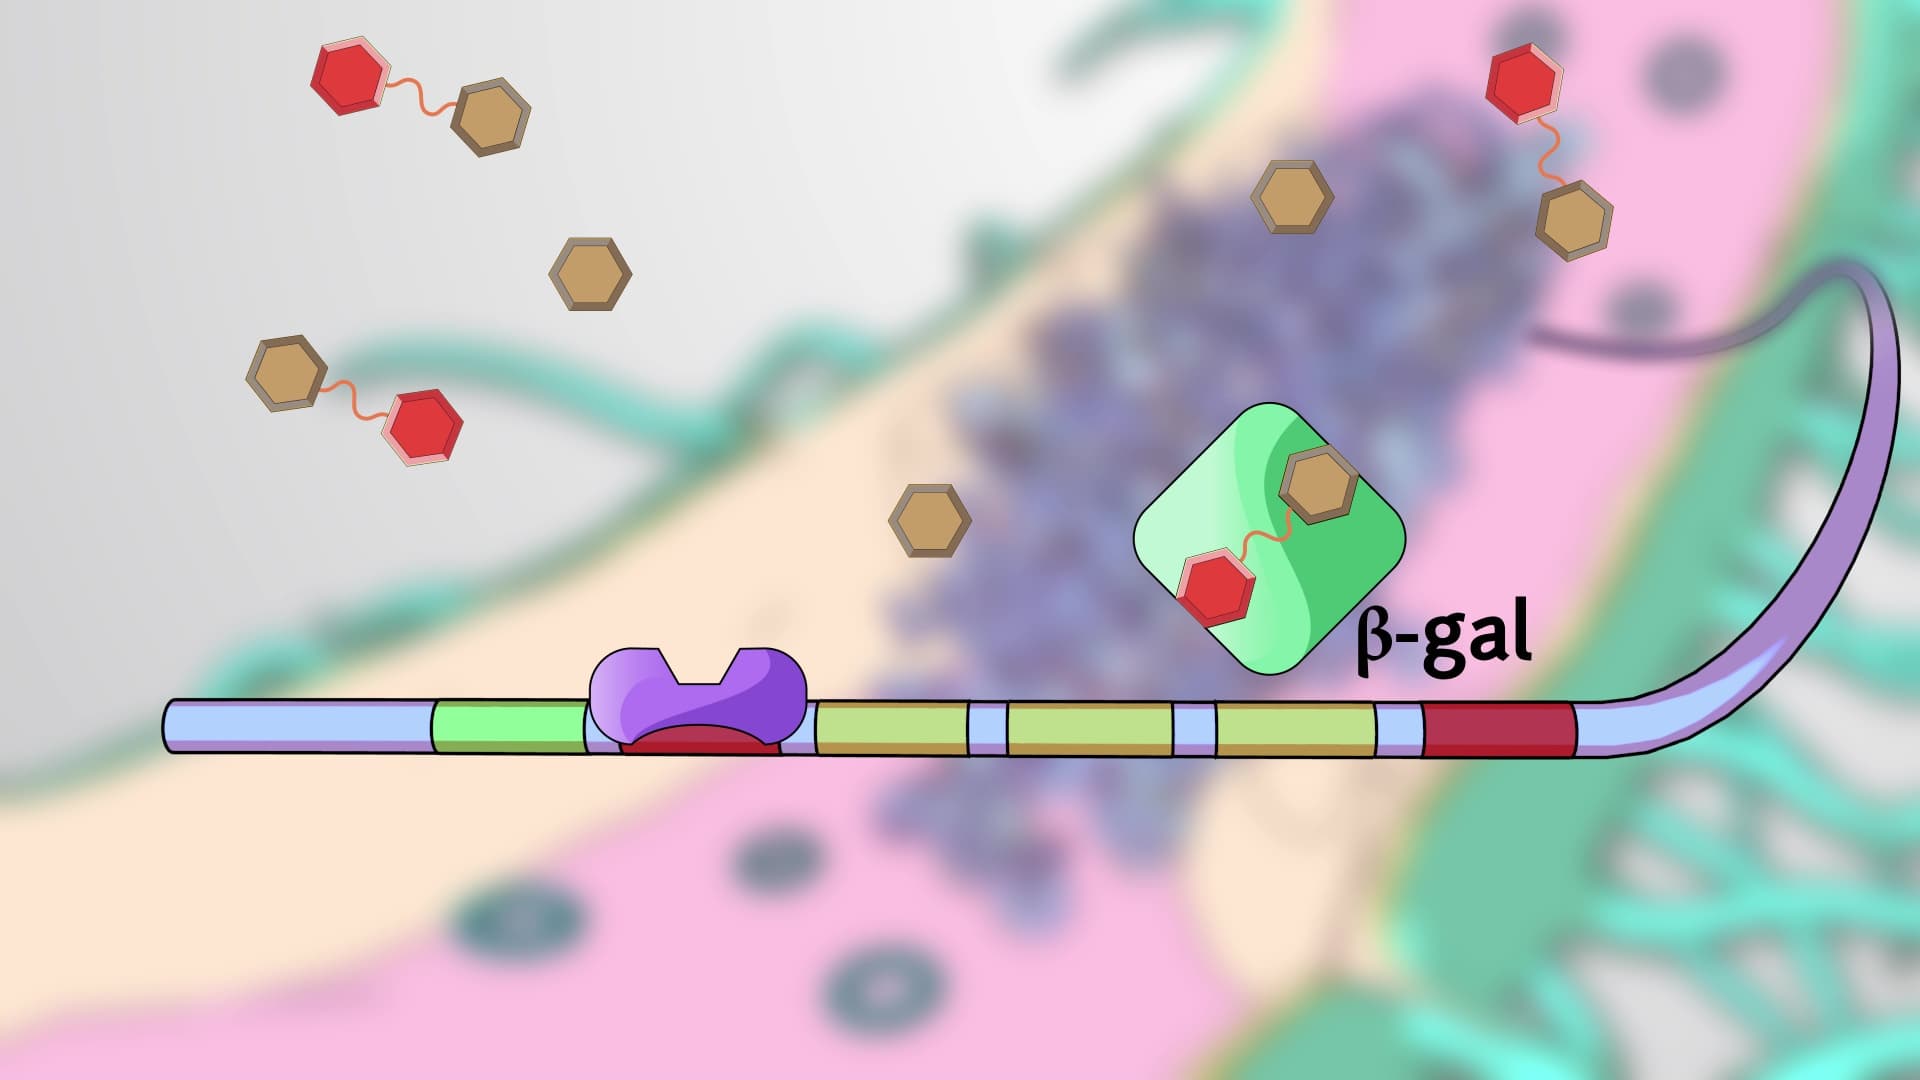
Operons
 01:26
Classification of Systems-I
Homogeneity dictates that if an input x(t) is multiplied by a constant c, the output y(t) is multiplied by the same constant. Mathematically, this is expressed as: