Related Experiment Video
Updated: Dec 7, 2025

Biosensor-based High Throughput Biopanning and Bioinformatics Analysis Strategy for the Global Validation of Drug-protein Interactions
Published on: December 1, 2020
PI1M: A Benchmark Database for Polymer Informatics
Ruimin Ma1, Tengfei Luo1,2
1Department of Aerospace and Mechanical Engineering, University of Notre Dame, Notre Dame, Indiana 46556, United States.

Abstract:
Open-source data on large scale are the cornerstones for data-driven research, but they are not readily available for polymers. In this work, we build a benchmark database, called PI1M (referring to ∼1 million polymers for polymer informatics), to provide data resources that can be used for machine learning research in polymer informatics. A generative model is trained on ∼12 000 polymers manually collected from the largest existing polymer database PolyInfo, and then the model is used to generate ∼1 million polymers. A new representation for polymers, polymer embedding (PE), is introduced, which is then used to perform several polymer informatics regression tasks for density, glass transition temperature, melting temperature, and dielectric constants. By comparing the PE trained by the PolyInfo data and that by the PI1M data, we conclude that the PI1M database covers similar chemical space as PolyInfo, but significantly populate regions where PolyInfo data are sparse. We believe that PI1M will serve as a good benchmark database for future research in polymer informatics.
Related Concept Videos
 02:21
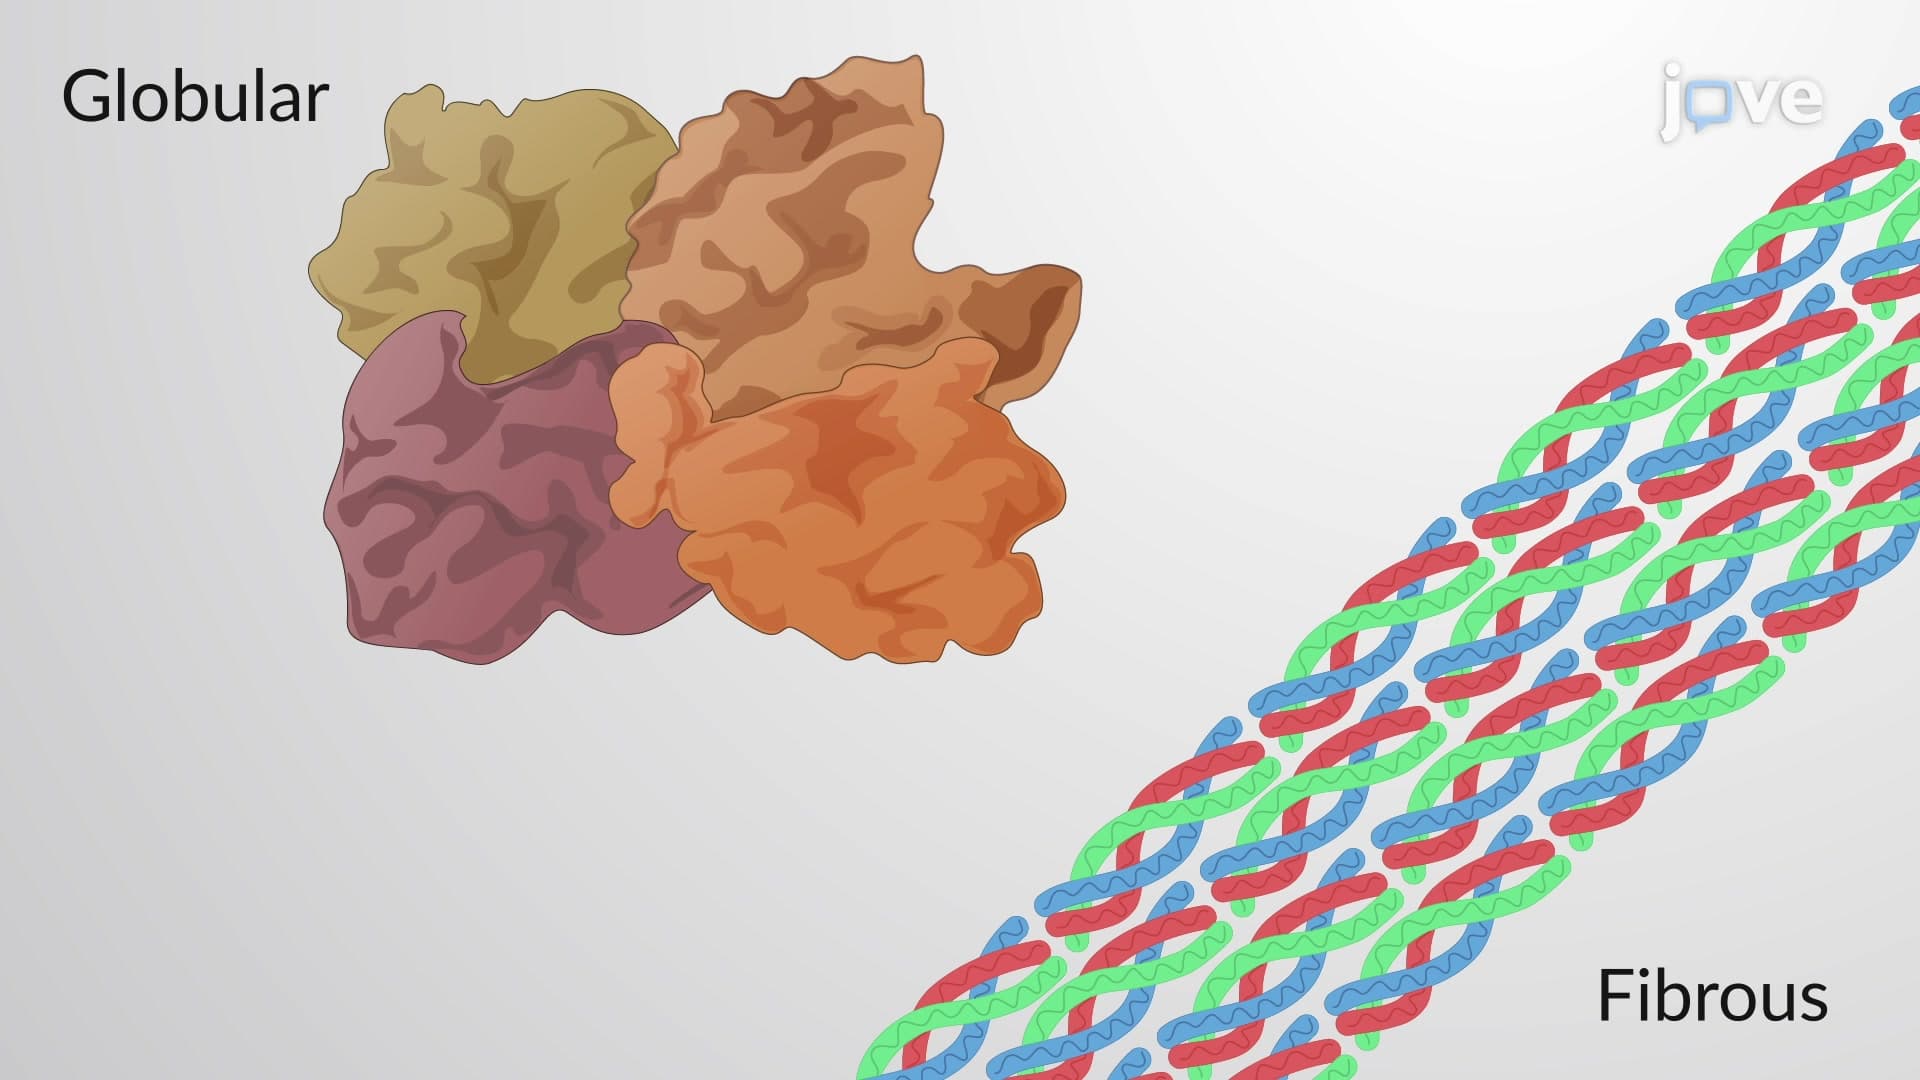
Globular and Fibrous Proteins
Globular proteins are also known as spheroproteins and typically are approximately round in shape. They contain a mix of amino acid types and contain differing sequences in their primary structures. Globular proteins have many different functions, such as enzymes, cellular messengers, and molecular transporters. These roles often require the proteins to be...
 01:10
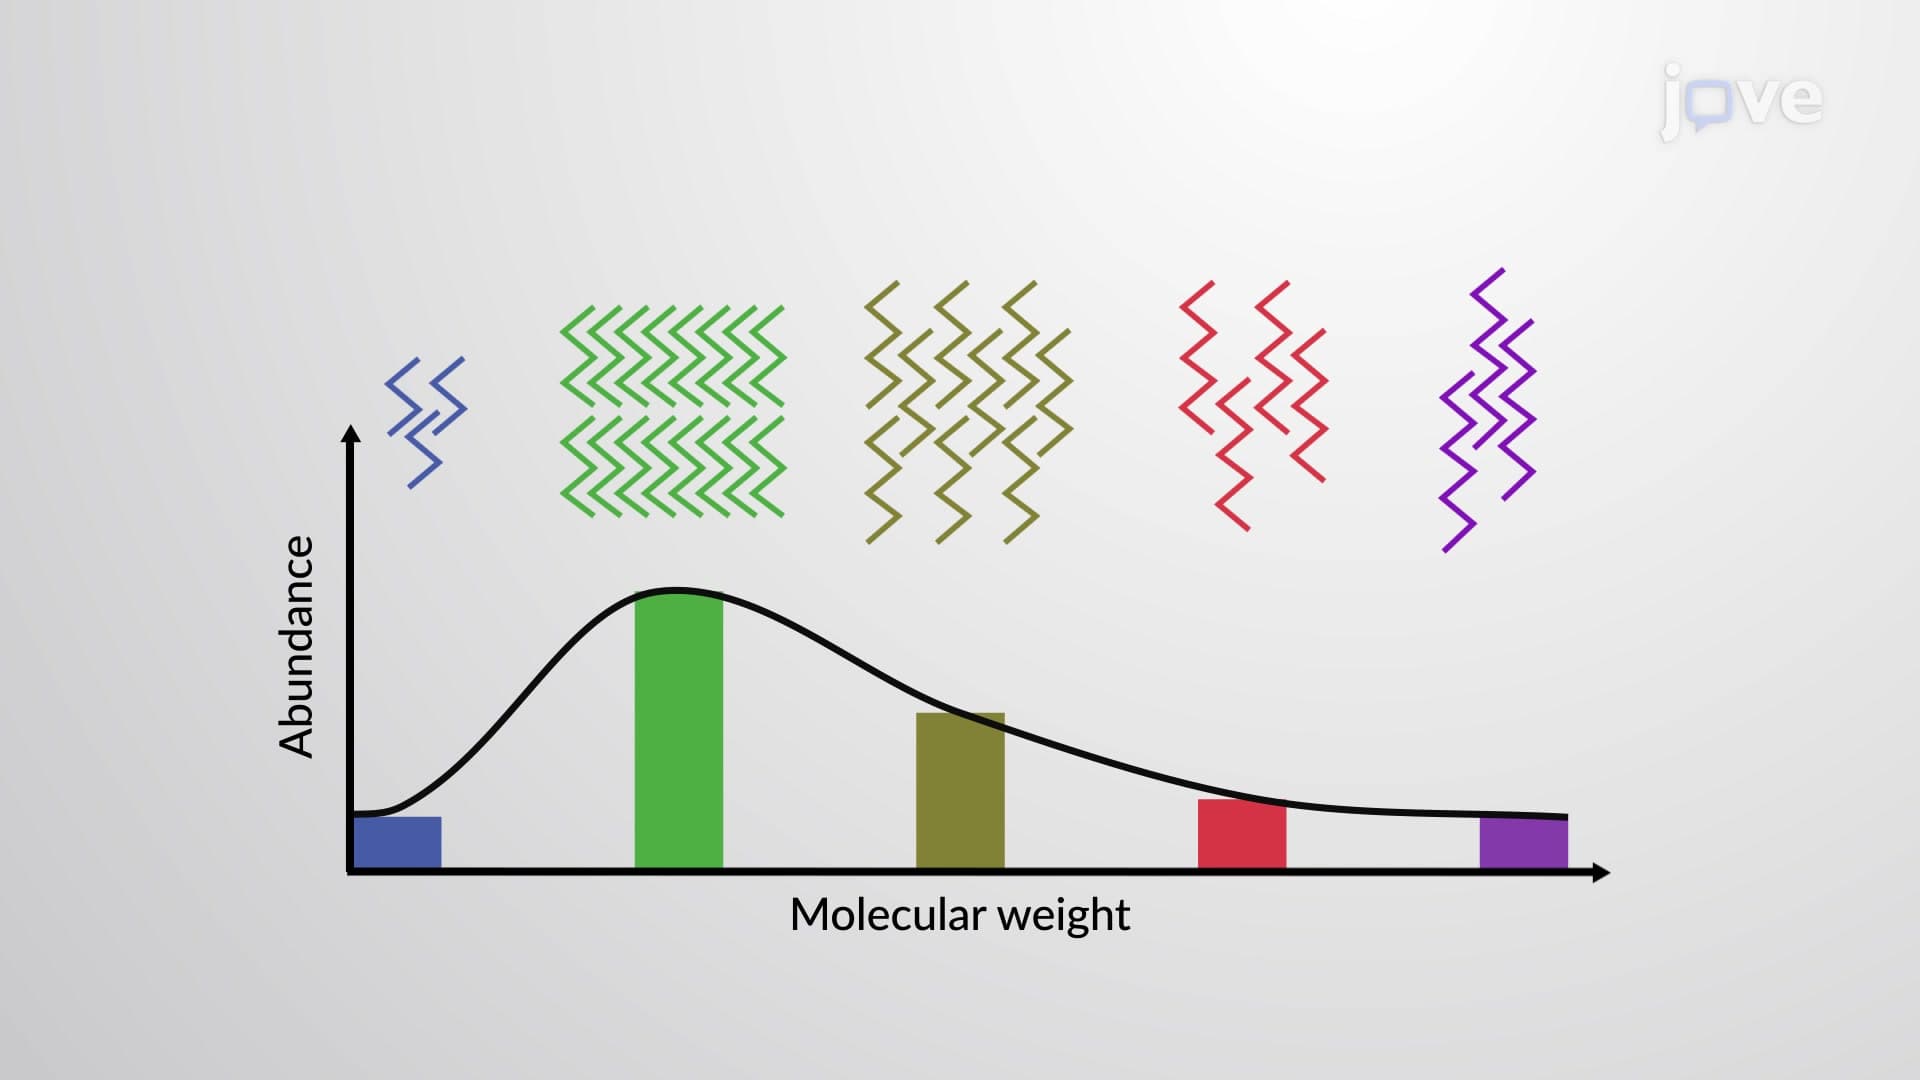
Polymers: Molecular Weight Distribution