Related Experiment Video
Updated: Dec 5, 2025

Measuring Statistical Learning Across Modalities and Domains in School-Aged Children Via an Online Platform and Neuroimaging Techniques
Published on: June 30, 2020
Statistical learning theory of structured data
Mauro Pastore1, Pietro Rotondo1, Vittorio Erba1
1Dipartimento di Fisica, Università degli Studi di Milano and INFN, Via Celoria 16, I-20133 Milan, Italy.

Abstract:
The traditional approach of statistical physics to supervised learning routinely assumes unrealistic generative models for the data: Usually inputs are independent random variables, uncorrelated with their labels. Only recently, statistical physicists started to explore more complex forms of data, such as equally labeled points lying on (possibly low-dimensional) object manifolds. Here we provide a bridge between this recently established research area and the framework of statistical learning theory, a branch of mathematics devoted to inference in machine learning. The overarching motivation is the inadequacy of the classic rigorous results in explaining the remarkable generalization properties of deep learning. We propose a way to integrate physical models of data into statistical learning theory and address, with both combinatorial and statistical mechanics methods, the computation of the Vapnik-Chervonenkis entropy, which counts the number of different binary classifications compatible with the loss class. As a proof of concept, we focus on kernel machines and on two simple realizations of data structure introduced in recent physics literature: k-dimensional simplexes with prescribed geometric relations and spherical manifolds (equivalent to margin classification). Entropy, contrary to what happens for unstructured data, is nonmonotonic in the sample size, in contrast with the rigorous bounds. Moreover, data structure induces a transition beyond the storage capacity, which we advocate as a proxy of the nonmonotonicity, and ultimately a cue of low generalization error. The identification of a synaptic volume vanishing at the transition allows a quantification of the impact of data structure within replica theory, applicable in cases where combinatorial methods are not available, as we demonstrate for margin learning.
Related Concept Videos
 01:17
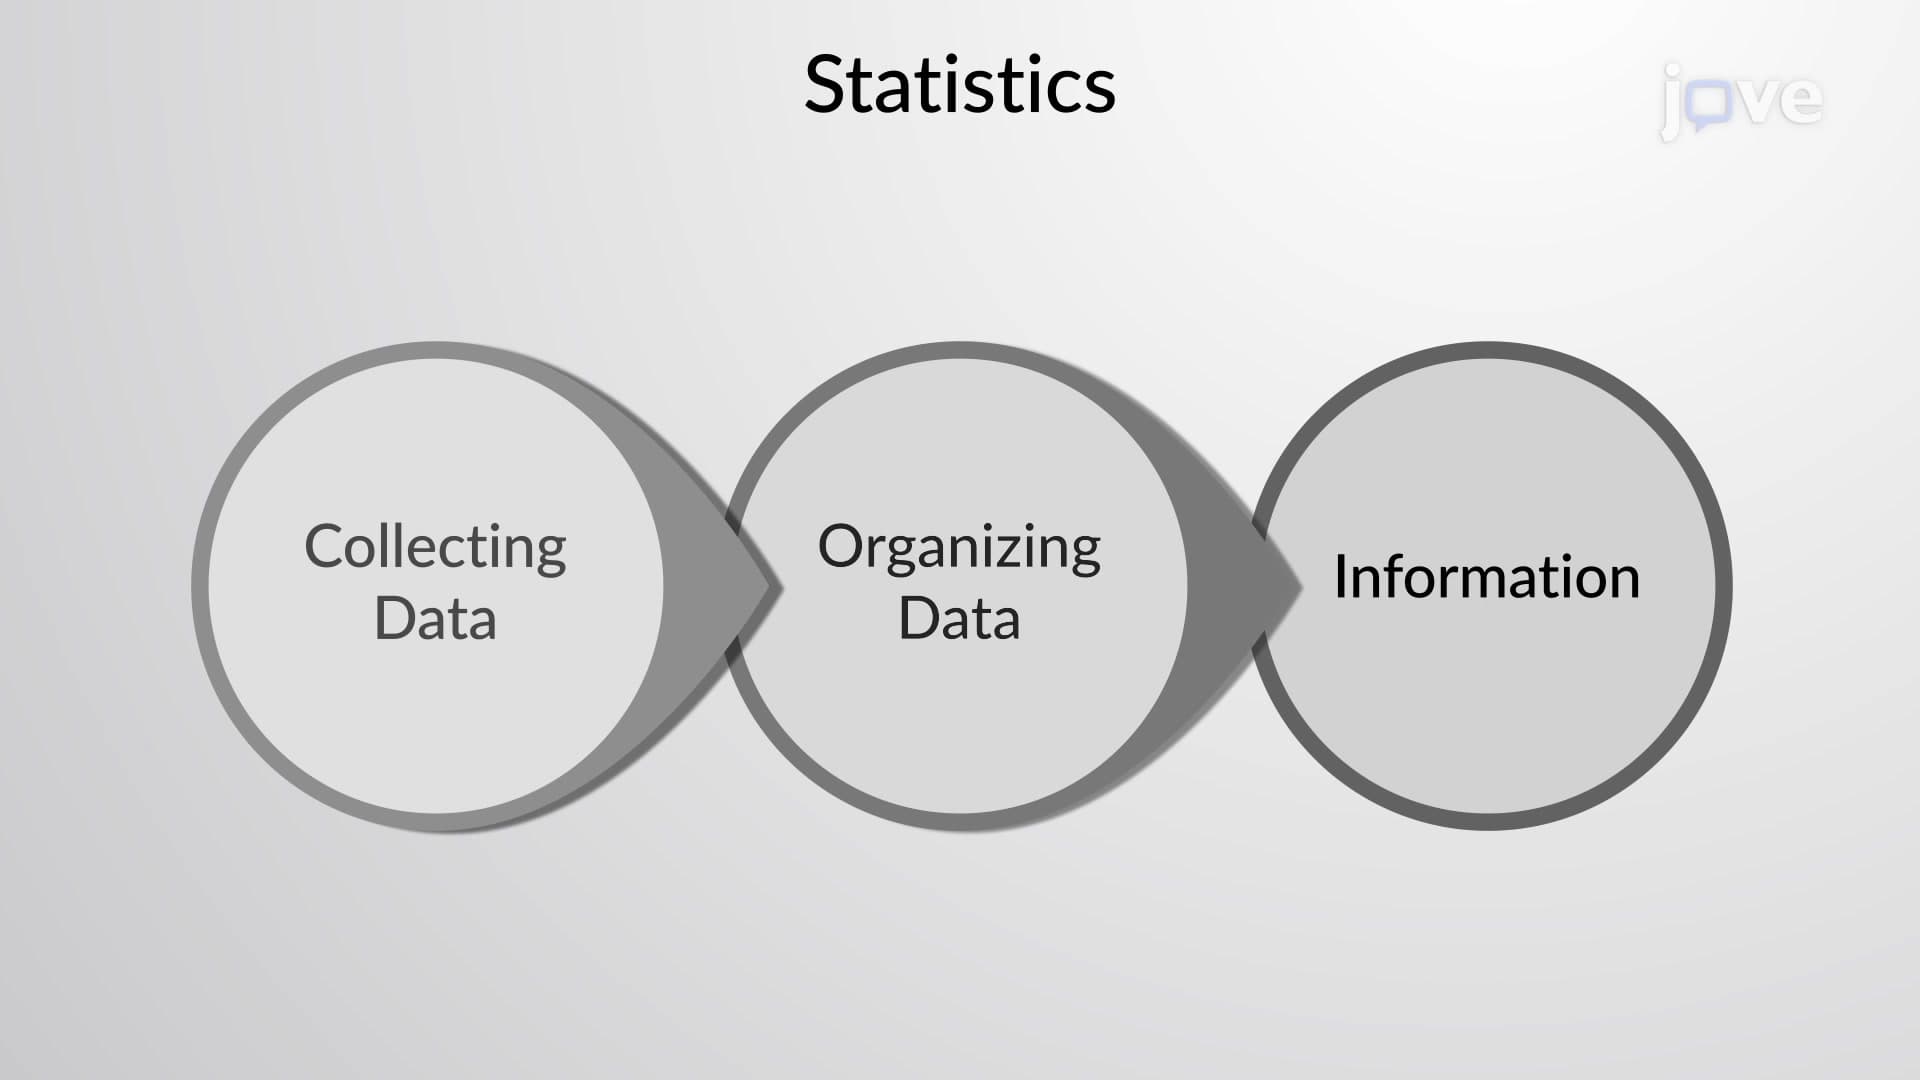
Introduction to Statistics
In statistics, the collection of individuals or objects under study is called population. The idea of sampling is to select a portion of the larger population...
 01:11
Statistical Analysis: Overview
One of the most commonly used statistical quantifiers is the mean, which is the ratio between the sum of the numerical values of all results and the...
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...
 01:16
Statistical Hypothesis Testing
Statistical significance measures the probability that an observed result occurred by chance. If this probability, known as...
 01:11
How Data are Classified: Categorical Data
Data are classified based on whether they are measurable or not. Categorical data cannot be measured; instead, it can be divided into categories. For example, if Y denotes a person's party affiliation, some examples of Y include...
 01:19
Data: Types and Distribution
Distributions in...