Related Experiment Video
Updated: Nov 28, 2025

An Integrated Workflow of Identification and Quantification on FDR Control-Based Untargeted Metabolome
Published on: September 20, 2022
A Workflow for Missing Values Imputation of Untargeted Metabolomics Data
Tariq Faquih1, Maarten van Smeden2, Jiao Luo1
1Department of Clinical Epidemiology, Leiden University Medical Center, Postal Zone C7-P, PO Box 9600, 2300 RC Leiden, The Netherlands.

Abstract:
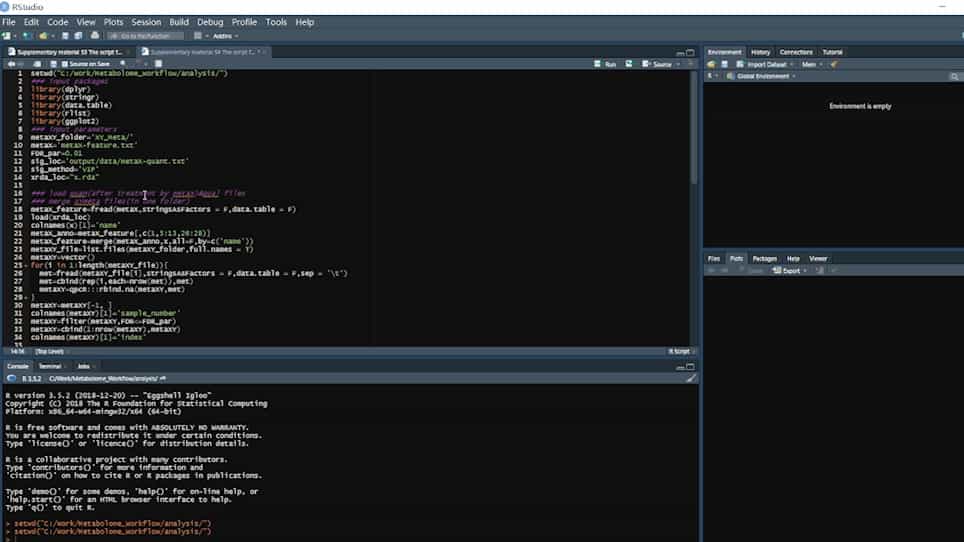
Metabolomics studies have seen a steady growth due to the development and implementation of affordable and high-quality metabolomics platforms. In large metabolite panels, measurement values are frequently missing and, if neglected or sub-optimally imputed, can cause biased study results. We provided a publicly available, user-friendly R script to streamline the imputation of missing endogenous, unannotated, and xenobiotic metabolites. We evaluated the multivariate imputation by chained equations (MICE) and k-nearest neighbors (kNN) analyses implemented in our script by simulations using measured metabolites data from the Netherlands Epidemiology of Obesity (NEO) study (n = 599). We simulated missing values in four unique metabolites from different pathways with different correlation structures in three sample sizes (599, 150, 50) with three missing percentages (15%, 30%, 60%), and using two missing mechanisms (completely at random and not at random). Based on the simulations, we found that for MICE, larger sample size was the primary factor decreasing bias and error. For kNN, the primary factor reducing bias and error was the metabolite correlation with its predictor metabolites. MICE provided consistently higher performance measures particularly for larger datasets (n > 50). In conclusion, we presented an imputation workflow in a publicly available R script to impute untargeted metabolomics data. Our simulations provided insight into the effects of sample size, percentage missing, and correlation structure on the accuracy of the two imputation methods.